

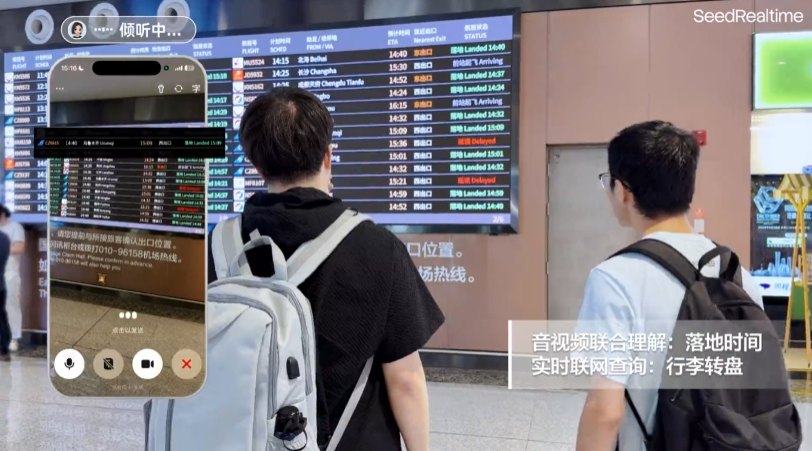
ByteDance Seed today announced the launch of SeedRealtime, a native full-duplex audio-visual model, advancing toward fully multimodal natural interaction.
SeedRealtime natively integrates audio, video, and text through a unified architecture, enabling real-time interaction across continuous multimodal streams and delivering a new experience of watching, listening, and speaking simultaneously. It achieves the following three core breakthroughs:
Joint audio-visual understanding: Natively supports the deep fusion of sound, visuals, and temporal information. The model can use scene context to resolve homophone ambiguities and accurately understand temporal references in visual content, integrating what is seen, heard, and said.
Proactive interaction: Provides continuous environmental awareness and proactive expression. When detecting changes in the visual state, such as the appearance of a key target, the model can issue proactive reminders. It can also call tools and incorporate them into its responses, upgrading interaction from passive response to proactive collaboration.
Natural interaction flow: Real-time awareness of the user's conversational state and communication rhythm enables the model to naturally take turns, pause, and respond at appropriate moments. It also offers strong interference resistance, distinguishing side conversations and background noise without being falsely triggered, thereby maintaining smooth and coherent communication.
End-to-end human evaluation shows that, compared with cascaded models, SeedRealtime cuts audio-visual dialogue timing issues in half. The model handles speaking turns more naturally, significantly reducing awkward moments such as interruptions before a speaker finishes, delayed responses after speech has ended, and false triggers from background noise or side conversations. The probability of completing a full, smooth exchange in a single conversation also increased significantly.
SeedRealtime is now fully available in the Doubao app, becoming the first in the industry to achieve large-scale deployment of full-duplex audio-visual technology. Update the Doubao app to the latest version, select “Call” in the dialogue box, and enter the video call interface to try it.
Project homepage:
https://seed.bytedance.com/seedrealtime