

The official BaLing large model team under Ant Group announced yesterday that the next-generation natively hybrid reasoning model Ling-3.0-flash is now officially open source.
Ling-3.0-flash uses an MoE architecture with 124B total parameters and 5.1B active parameters. The official release includes the base version as well as FP8, FP4, and INT4 versions, offering three deployment options:
API access: For developers who want rapid integration without building their own inference service, Ling-3.0-flash can be called directly through a cloud API;
Single-machine private deployment: For enterprises and teams whose data cannot leave their domain, the MXFP4 and INT4 versions can perform end-to-end inference on a single NVIDIA DGX Spark;
High-performance deployment: For high-performance services sensitive to single-request latency, the average output speed exceeds 1100 tokens/s under the specified GPU test configuration.
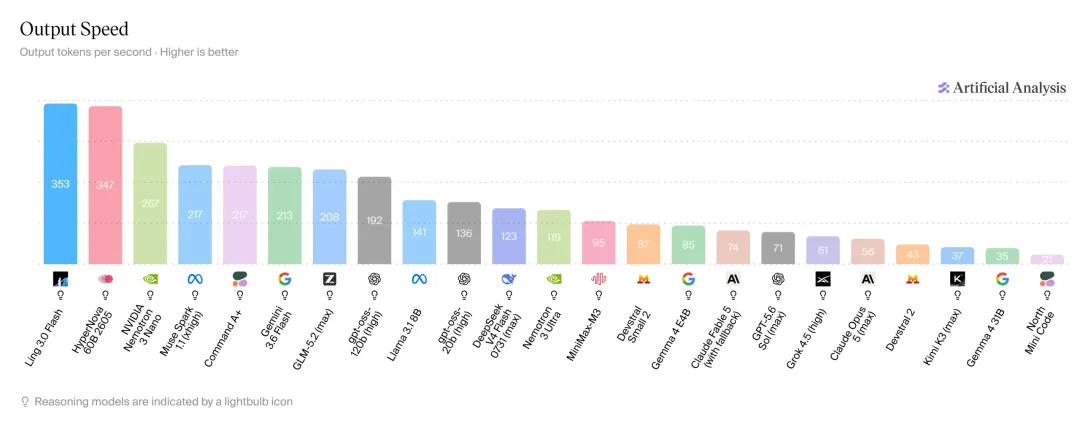
For developers and product teams looking to quickly validate products and launch Agent applications, the API is the lowest-barrier integration method. On the Artificial Analysis leaderboard, Ling-3.0-flash achieves an output speed of 353 tokens/s.
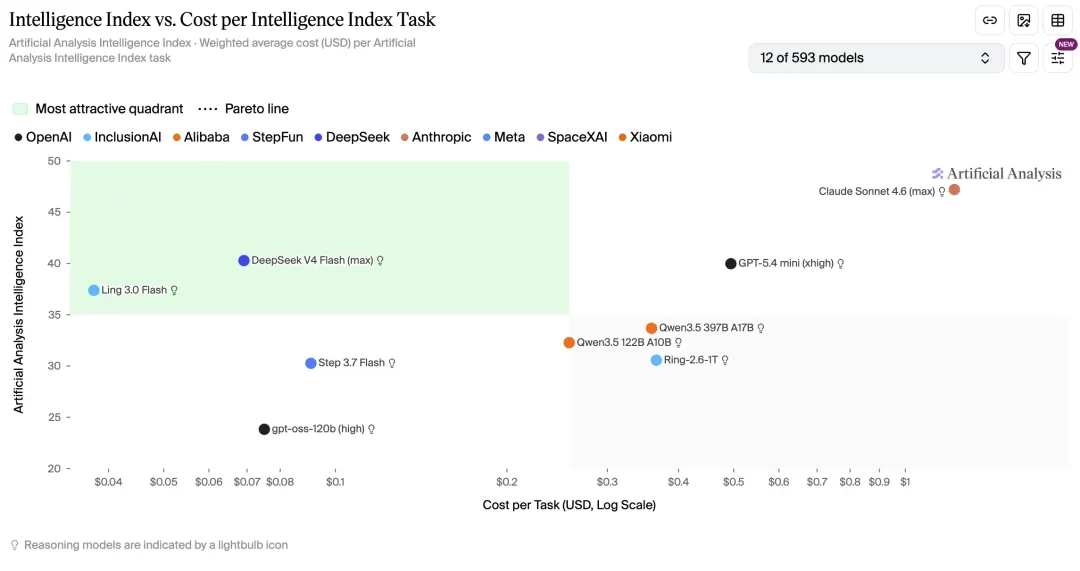
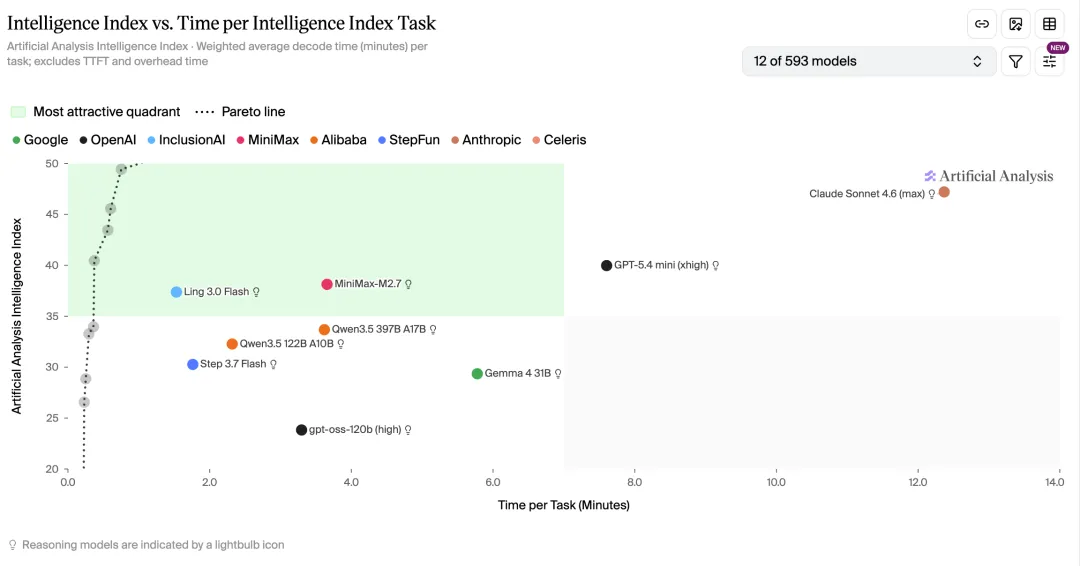
On the AA Intelligence Index leaderboard, Ling-3.0-flash has a weighted average cost of approximately $0.04 per task (approximately 0.27 yuan at the current exchange rate) and a weighted average decoding time of approximately 1.4 minutes. It also enters the favorable zones for “intelligence level — task cost” and “intelligence level — task duration.”
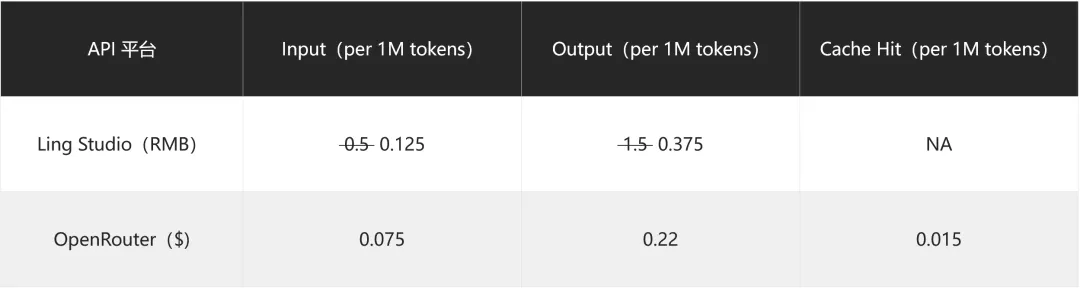
The official announcement states that from 00:00 on August 7, 2026, to 24:00 on August 31, Ling-3.0-flash will be available on Ling Studio at 2.5-fold pricing; regular pricing will resume at 00:00 on September 1.
Open-source links:
Hugging Face: https://huggingface.co/inclusionAI/Ling-3.0-flash
ModelScope: https://modelscope.cn/models/inclusionAI/Ling-3.0-flash