

Today, MiniMax officially open-sourced its next-generation general-purpose video model, MiniMax H3.
According to the introduction, MiniMax H3 is a general-purpose omni-modal generation system. It can uniformly understand multimodal contexts composed of text, images, videos, and audio, and can generate videos with up to 2K resolution, a maximum length of 15 seconds, and native stereo audio. Thanks to a system design oriented toward task generalization, H3 already possesses broad multimodal context understanding and generation capabilities during the pretraining stage, enabling it to effectively follow complex multimodal instructions.
H3 supports the following input and output specifications:
Output duration: 4–15 seconds
Output aspect ratios: Supports various aspect ratios, including but not limited to 21:9, 16:9, 4:3, 1:1, 3:4, and 9:16
Output resolution: Supports multiple resolution sizes, with the shorter side set to 768 pixels by default. 2K resolution generation can be achieved using H3-Regenerate-2K
Output frame rate: 24 FPS
Output audio: 32 kHz stereo
Supported conversation languages: Reliably supports 11 languages: Arabic, Chinese, English, French, German, Italian, Japanese, Korean, Portuguese, Russian, and Spanish. Other languages are also supported to varying degrees.
Model versions and input specifications:
① H3-Base-FL2VA
First-and-last-frame mode: Supports input of 0, 1, or 2 images:
With no image input, it operates in text-to-video mode;
With a first-frame image, it operates in first-frame-to-video mode;
With a last-frame image, it operates in last-frame-to-video mode;
With both first- and last-frame images, it operates in first-and-last-frame-to-video mode
② H3-Base-Ref2VA
Omni-modal reference mode:
Images: Up to 9;
Videos: Up to 3 clips; each clip must be 2–15 seconds long, with a total duration of no more than 15 seconds;
Audio: Up to 3 clips. Audio must be input together with images or videos and cannot be the sole input; each clip must be 2–15 seconds long, with a total duration of no more than 15 seconds;
Mixed input: A maximum of 12 input files in total across all types
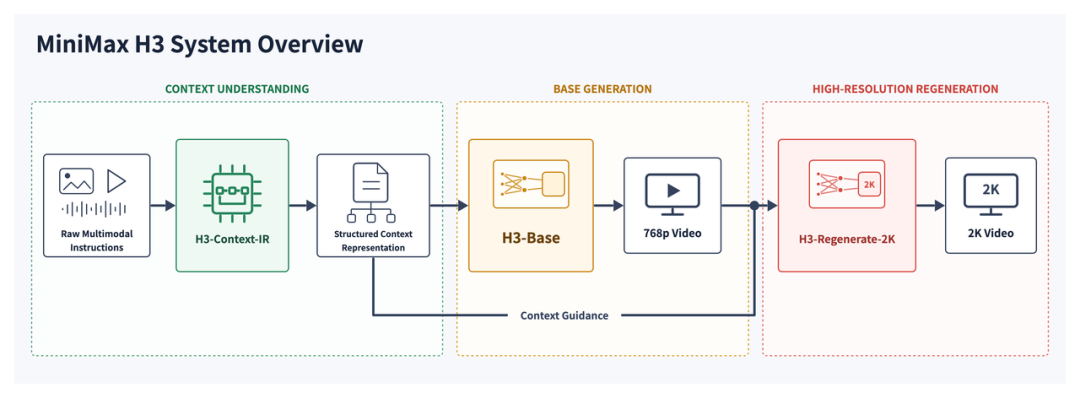
The complete H3 system consists of the following three modules:
H3-Contex t-IR: As inputs become increasingly complex, we built a dedicated system to deeply understand and distill multimodal instructions and convert them into a form that H3 can understand more easily and use directly for generation: Context Intermediate Representation. H3-Context-IR is very important to the quality of the final output. Therefore, we strongly recommend integrating the H3-Context-IR API into the generation workflow. Alternatively, you can refer to the prompt guide to build your own context processing system.
H3-Base: Generates audio and video based on the output of H3-Context-IR and outputs results at 768p resolution.
H3-Regenerate-2K: Sends the 768p generated result, together with the original context, back to H3 to regenerate the output at 2K resolution. This both leverages H3’s powerful generation capabilities and makes full use of the rich information contained in the original context, producing high-resolution results with more accurate details and higher visual fidelity.
MiniMax H3 is released under the MiniMax H3 Community License.
Open-source address: huggingface.co/MiniMaxAI/MiniMax-H3