

The Alibaba Tongyi Qianwen team officially released Qwen3.8-Flash tonight. The Tongyi team also released the open-source weights for Qwen3.8-Flash-Next, whose new architecture will serve as the prototype for the next-generation Qwen4 series models.
This is a multimodal MoE model with 125B parameters in the main model, an additional 51B N-gram Embedding, and 6B parameters activated per token. It natively supports a 262,144-token context and can be extended to 1M tokens through YaRN.
According to the team, Qwen3.8-Flash has undergone systematic upgrades in four areas:
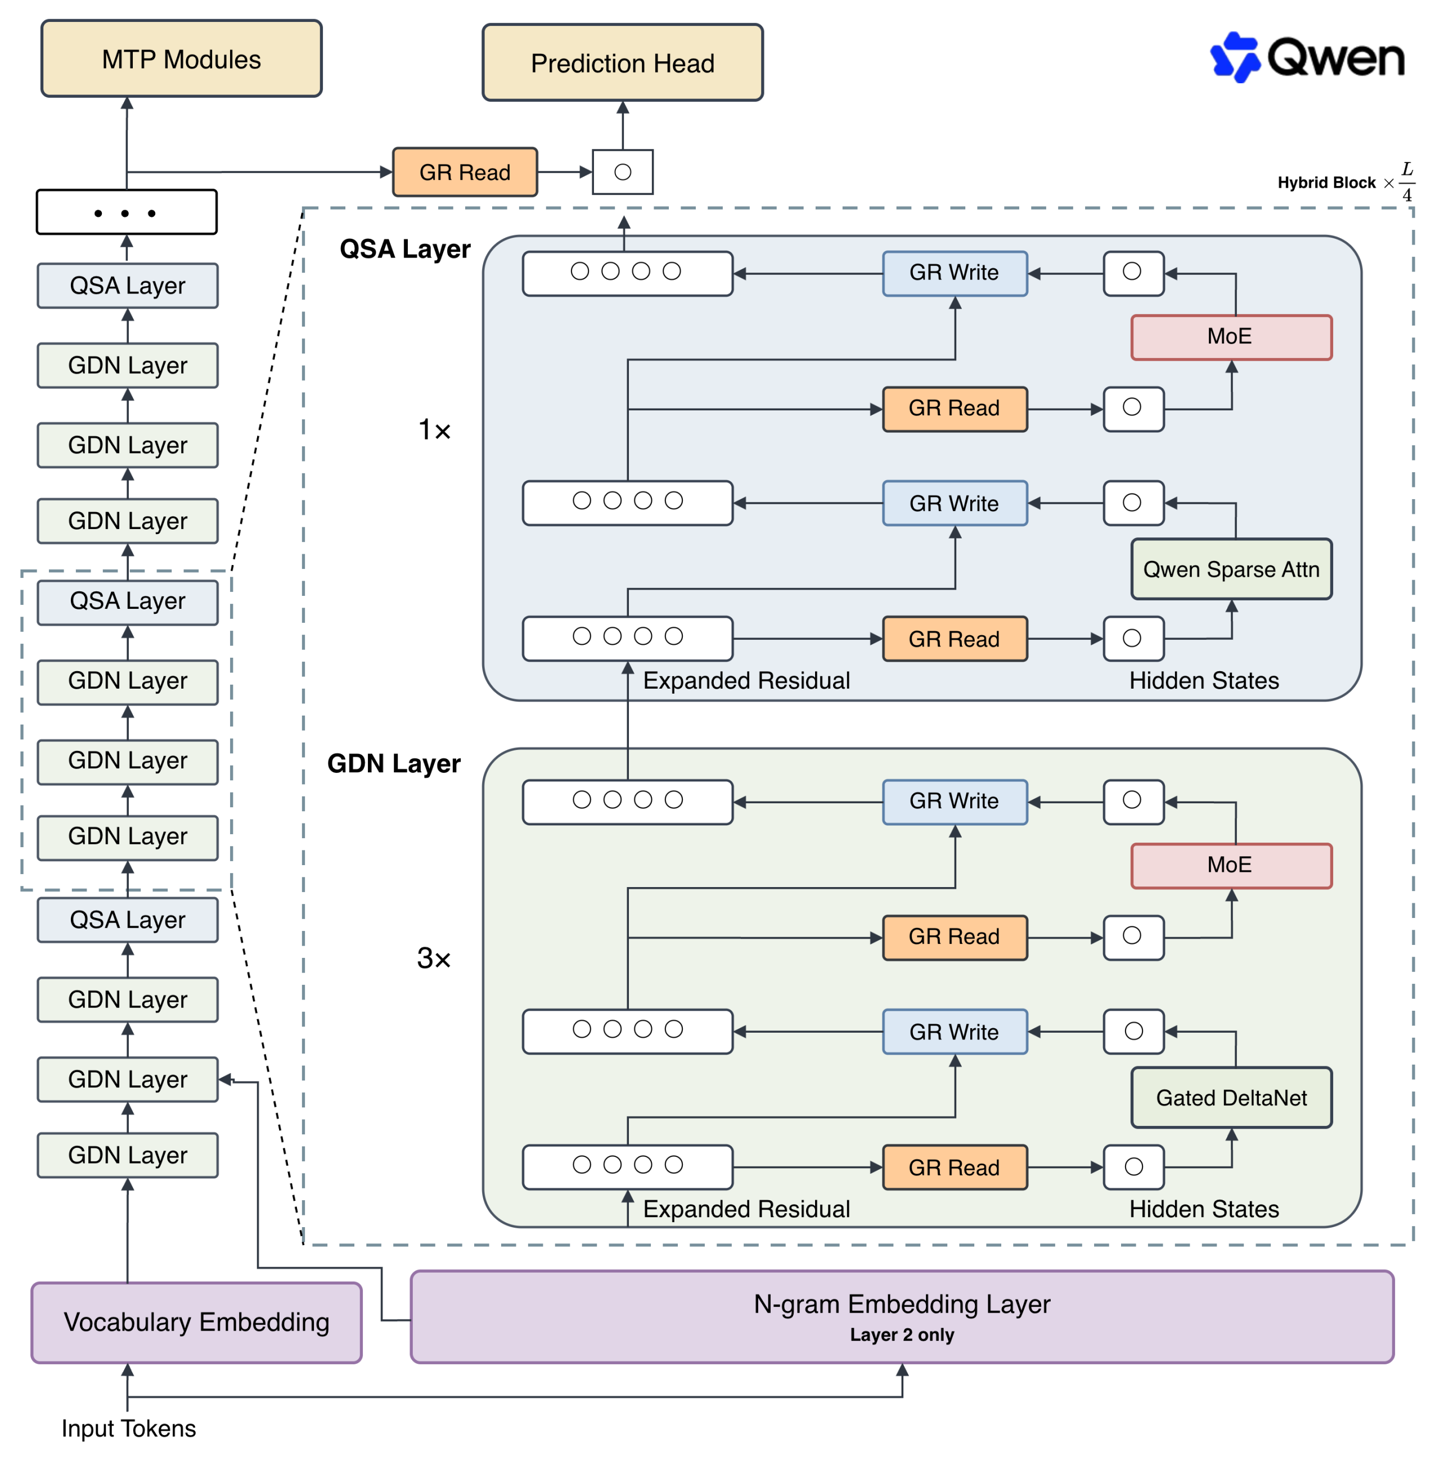
For Attention, it uses a hybrid GDN (Gated DeltaNet) + QSA (Qwen Sparse Attention) architecture. GDN efficiently compresses historical information, while QSA uses a lightweight Indexer to select important context at the micro-block level, significantly reducing Attention overhead for long sequences. For an ultra-long context of 1M tokens, QSA's Attention Kernel achieves maximum speedups of 7.6x and 4.9x during the Prefill and Decode stages, respectively.
For Residual, it introduces the Gated Residual (GR) mechanism, expanding the residual stream into four parallel branches and using dynamic Gates to control information reading and writing. Residual states support FP8 storage, substantially reducing memory access overhead.
For Embedding, it introduces a 51B-parameter N-gram Embedding that expands model capacity by looking up local context. These parameters can be offloaded to Host Memory, where asynchronous Prefetch overlaps with model computation, avoiding long-term occupation of GPU memory.
For Optimization, it uses the Muon Optimizer and has been optimized for orthogonalization precision, parameter specialization, fused matrix splitting, and other strategies. The Scaling Law was refitted for the new architecture.
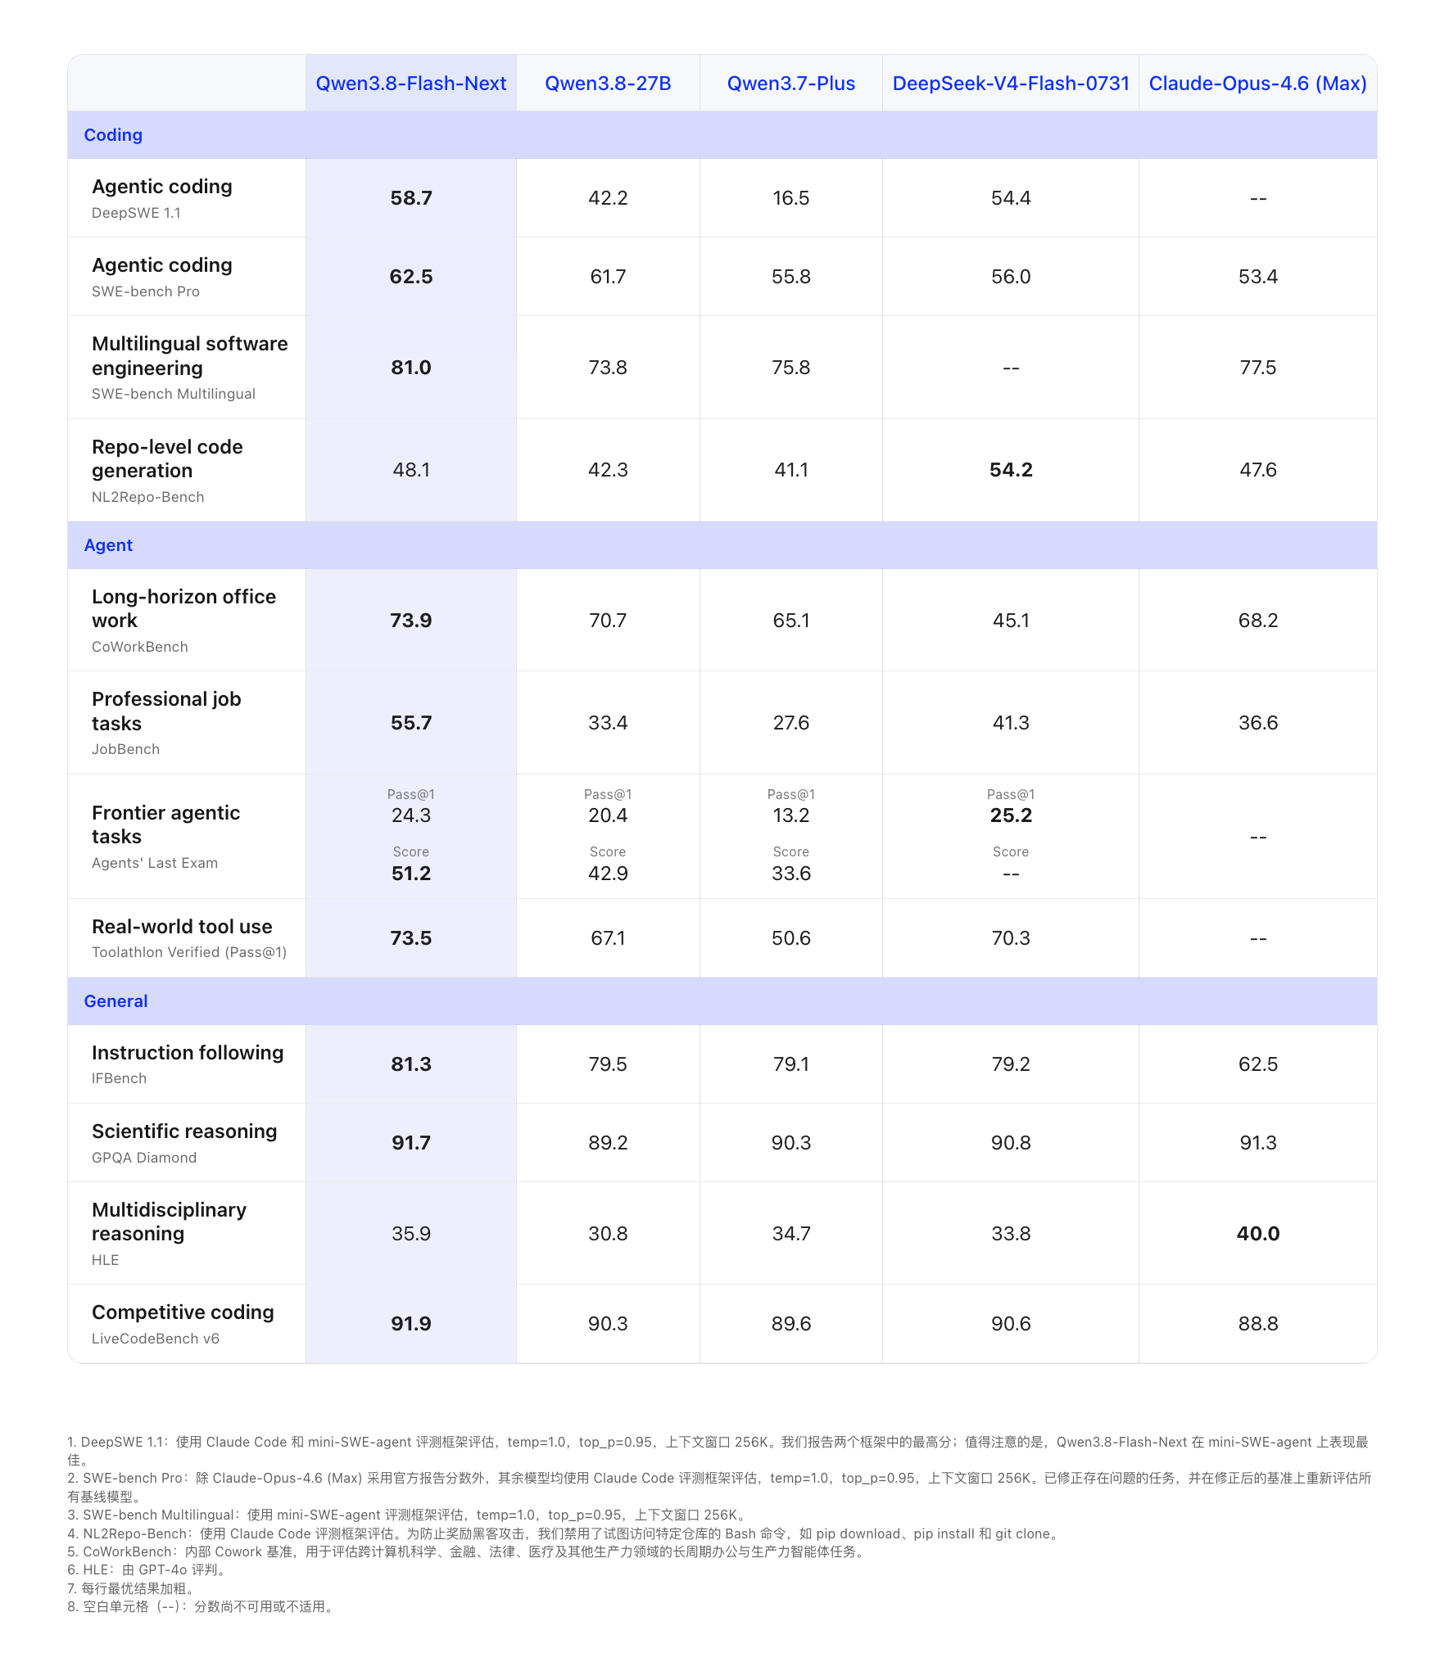
Compared with Qwen3.7-Plus, Qwen3.8-Flash costs only about one-ninth as much to train while offering stronger capabilities for coding and office tasks.
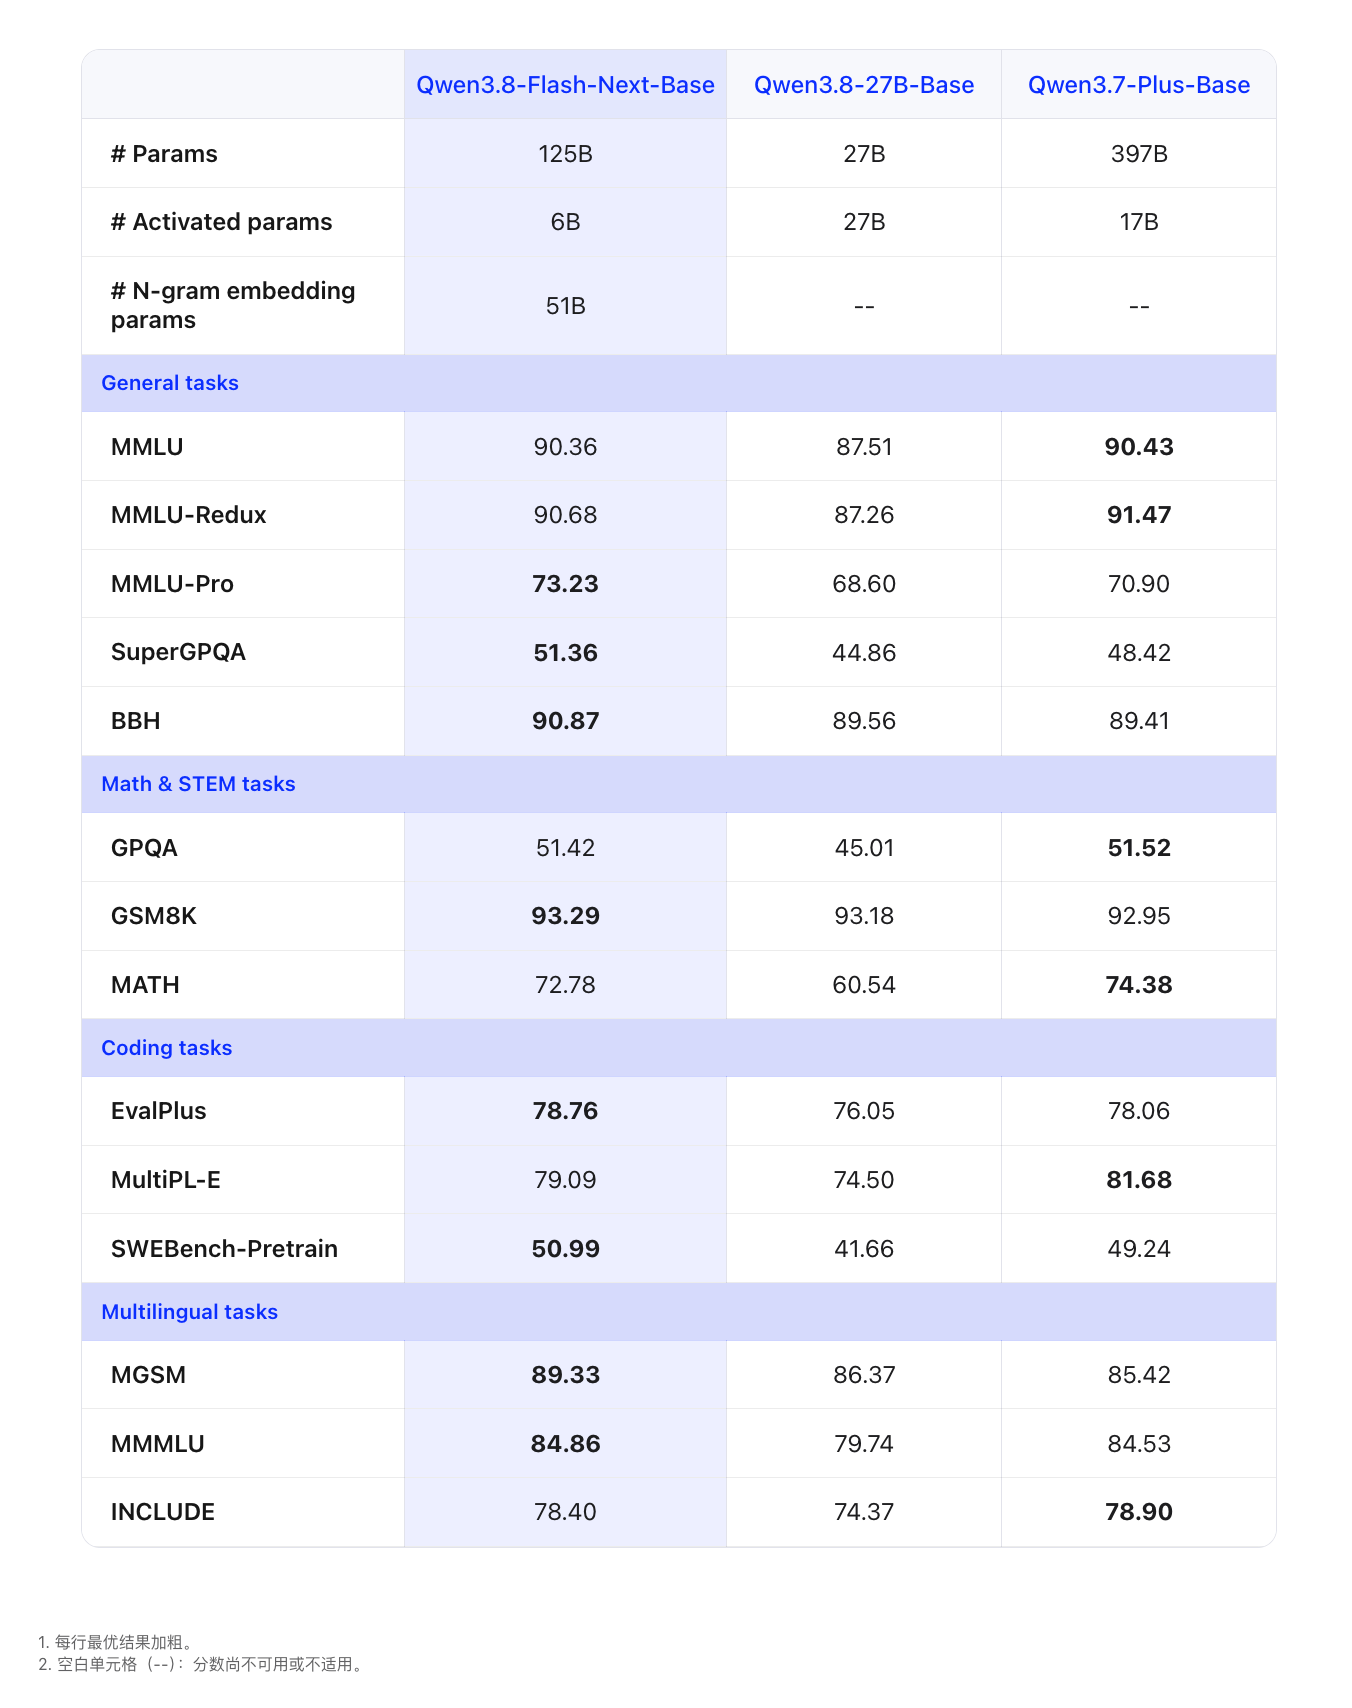
With 6B activated parameters, Qwen3.8-Flash-Next-Base achieved the best results on 8 of 14 benchmarks, including MMLU-Pro, SuperGPQA, BBH, SWEBench-Pretrain, MGSM, and MMMU.
Text only:
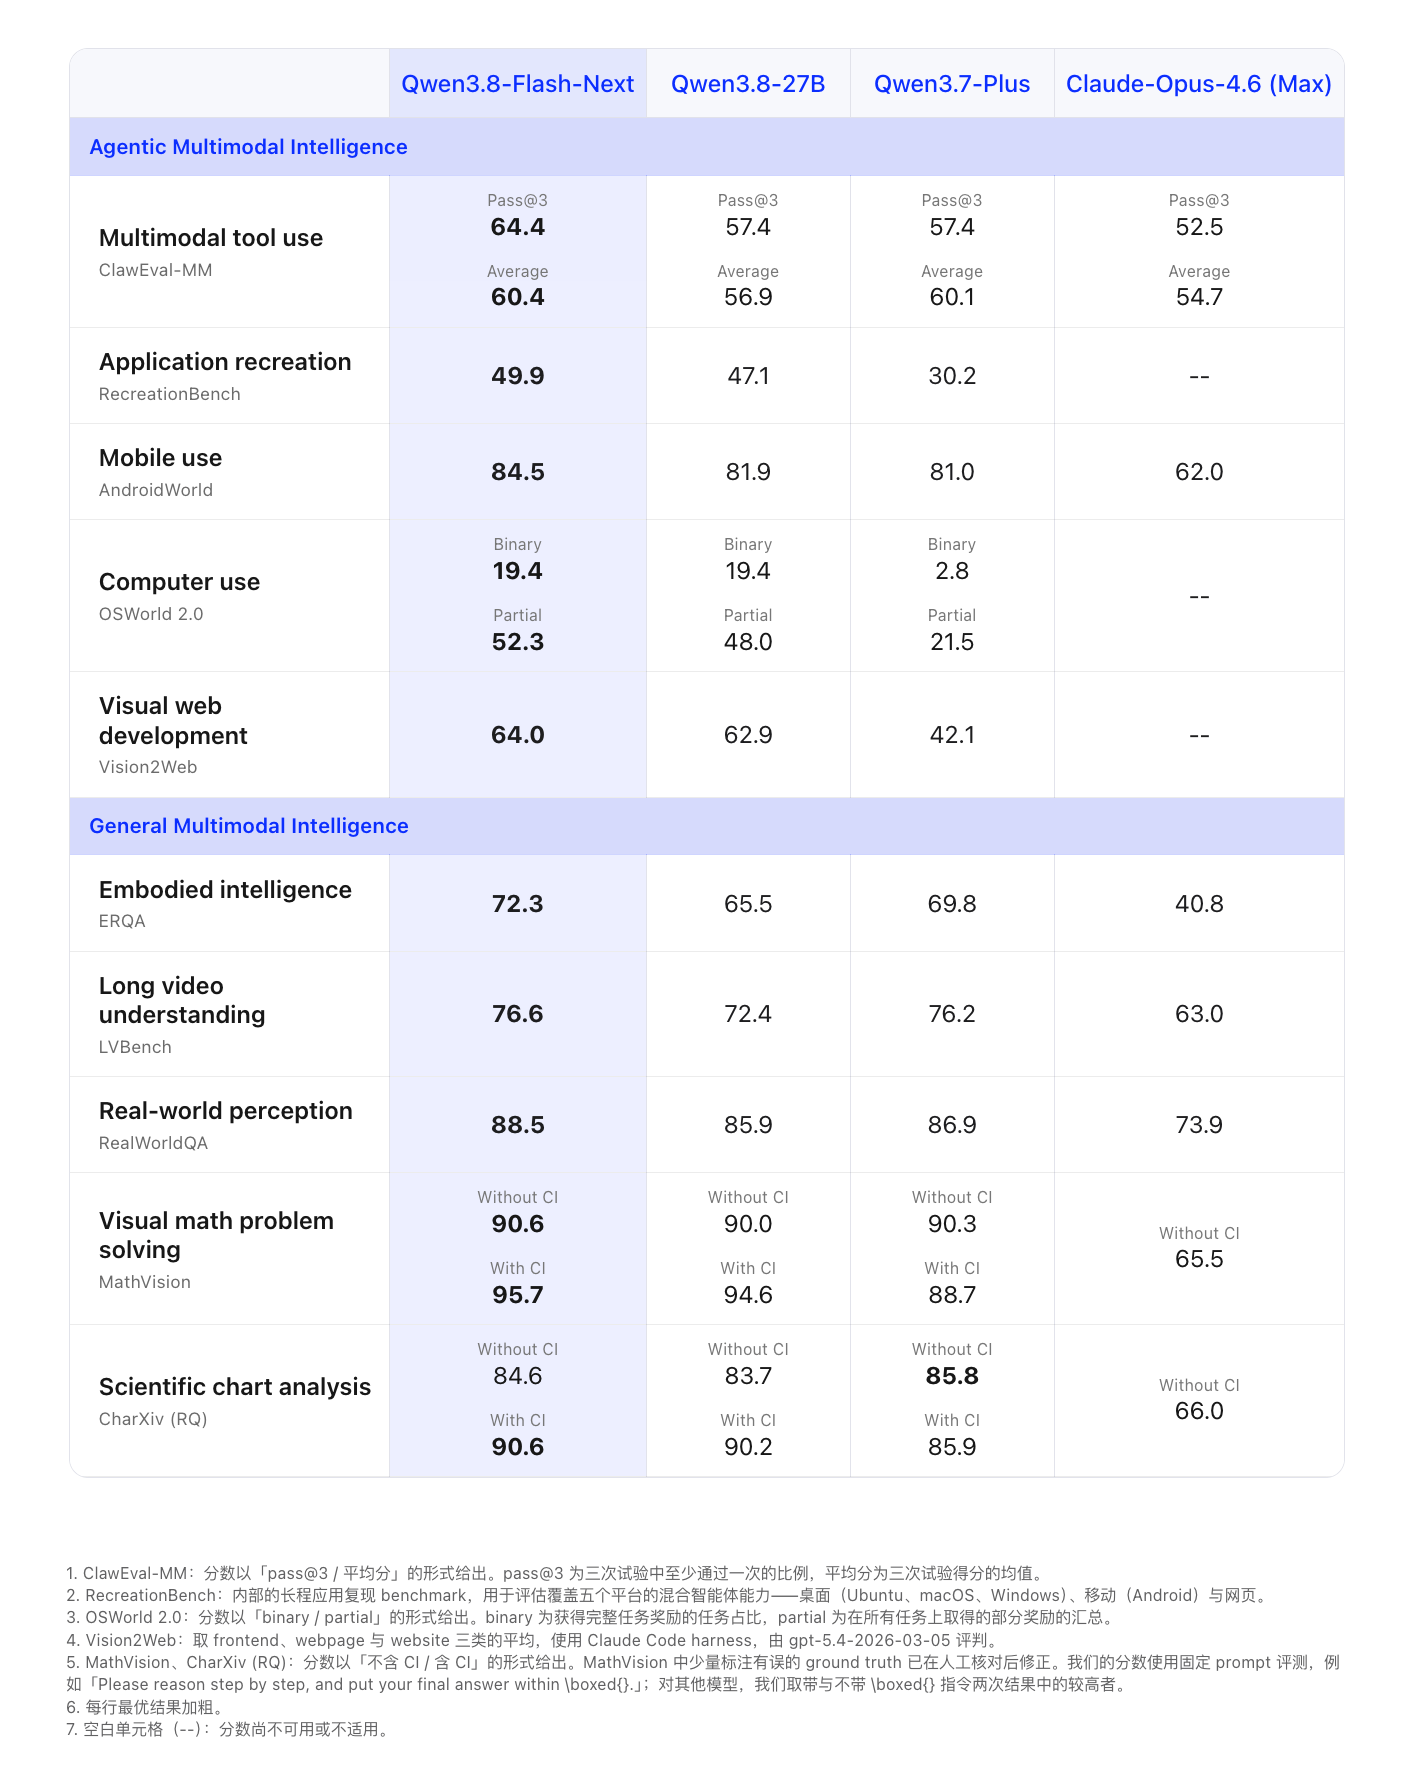
Multimodal:
Model architecture:
Base model performance:
Qwen3.8-Flash will soon launch on the Qianwen AI platform with API services available to the public, priced at 1 yuan per million input Tokens and 3 yuan per million output Tokens.
The model weights were released as open source on Hugging Face and ModelScope at 23:00 Beijing time on August 26, along with an FP8 quantized version. Qwen3.8-Flash-Next supports a 1M context by default and includes official tools.
References:
Technical report: https://github.com/ QwenLM / Qwen3.8-Flash-Next / blob / main / tech_report.pdf
Technical blog: https://qwen.ai/ blog?id=qwen3.8-flash-next
Hugging Face: https://huggingface.co/Qwen/Qwen3.8-Flash-Next ?spm= a2ty_o06.30285417.0.0.1d73c921FsyOPe& ;amp;amp;file=Qwen3.8-Flash-Next
ModelScope: https://modelscope.cn/models/Qwen/Qwen3.8-Flash-Next ?spm= a2ty_o06.30285417.0.0.1d73c921XAP2dV& ;amp;amp;file=Qwen3.8-Flash-Next