

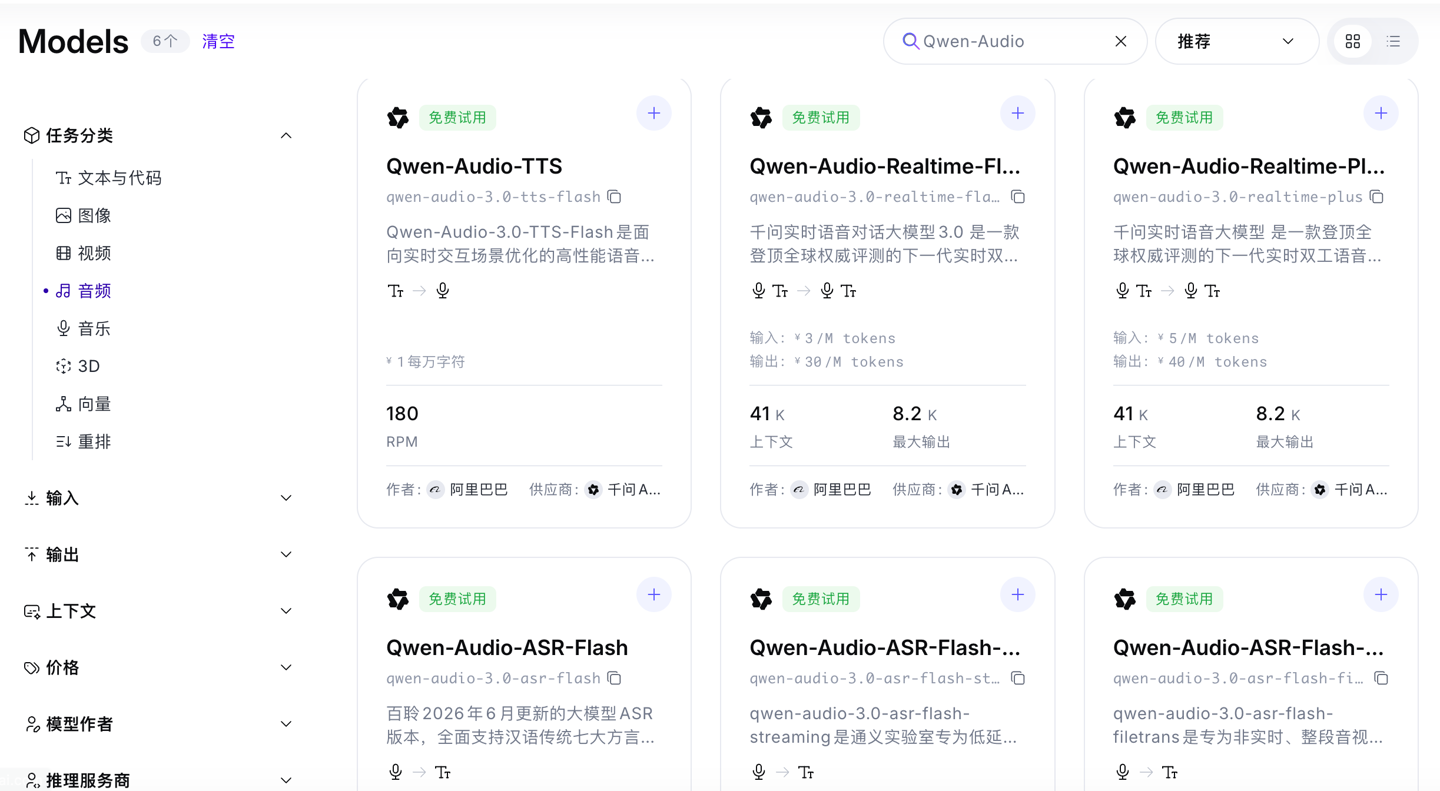
This afternoon (the 17th), Alibaba Cloud announced via its official WeChat account that the Qwen-Audio-3.0 speech model series is now available on the Qwen AI and Alibaba Cloud Model Studio platforms. Developers can access the models through API services or subscribe to a Token Plan.
The Qwen-Audio-3.0 series consists of proprietary speech models developed by Alibaba. IT Home lists the full product lineup below:
Speech recognition model Qwen-Audio-3.0-ASR
Speech synthesis model Qwen-Audio-3.0-TTS
Real-time voice interaction model Qwen-Audio-3.0-Realtime
According to the announcement, the series ranked No. 1 globally in all three categories—automatic speech recognition (ASR), real-time interaction (RealTime), and text-to-speech synthesis (TTS)—on the July speech leaderboards published by Artificial Analysis, a leading global AI benchmarking platform, completing a clean sweep.
Qwen-Audio-3.0-ASR converts speech into text and supports recognition in complex contexts and specialized fields; Qwen-Audio-3.0-TTS converts text into speech, supports multiple languages and dialects, and allows control over emotion, tone, and pacing; Qwen-Audio-3.0-Realtime supports end-to-end speech understanding and conversation, enabling simultaneous listening and speaking, interruptions and follow-up questions at any time, as well as tool calling.
The model series is currently used in products including the Qwen app, Qwen Office, and Qoder.