

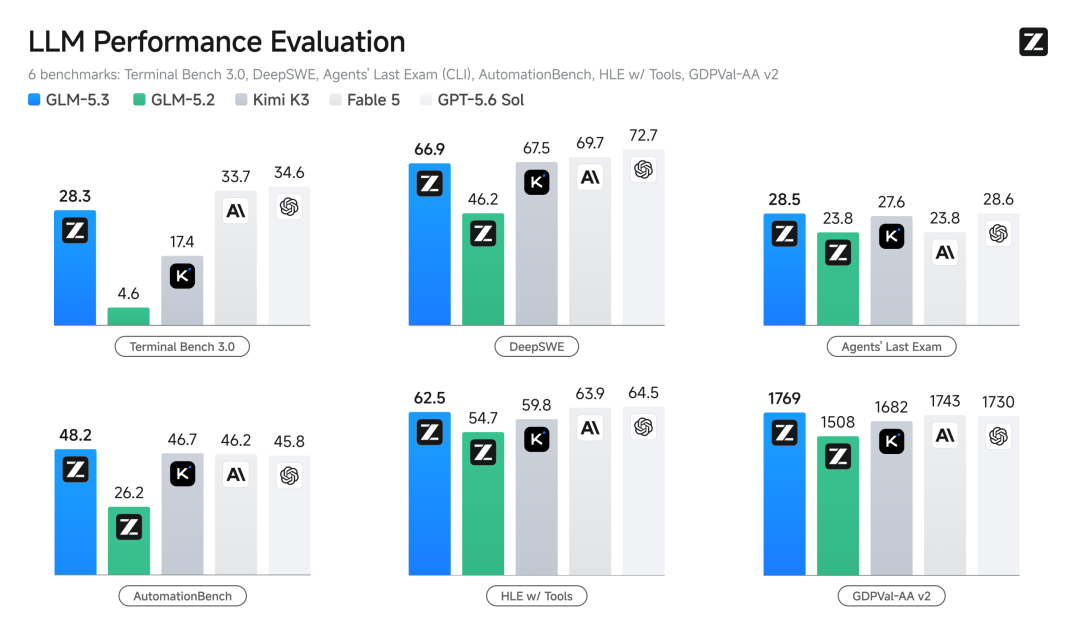
Zhipu officially released GLM-5.3 today. Compared with GLM-5.2, the base model remains unchanged, but post-training scaling has greatly raised the model’s intelligence ceiling: dozens of times more long-horizon task environments, richer and more diverse environment types, and much longer post-training.
Compared with its predecessor, GLM-5.3 introduces the following new capabilities:
Stronger programming capabilities. GLM-5.3 is the strongest open-source model for programming. In Zhipu’s internally developed hands-on evaluations, it improved by 50% over GLM-5.2, and it achieved the top position among open-source models on public benchmarks including Terminal Bench 3.0 and Agents' Last Exam (CLI).
Cybersecurity capabilities. On security tasks such as white-box code review and vulnerability discovery, GLM-5.3 performs on par with Mythos 5, demonstrating strong potential for cybersecurity defense scenarios.
Post-training scaling. All of the improvements above come from post-training. Based on IndexShare, SAO, and the continuously evolving next-generation Slime framework, Zhipu has efficiently advanced reinforcement learning on exactly the same base model as GLM-5.2. It is possible that Zhipu has still not fully reached this base model’s intelligence ceiling.
Open source. Zhipu will release the model weights two weeks after launch, following completion of safety evaluations and model hardening.
Zhipu says that GLM-5.3 is currently the highest-ranked open-source model across multiple mainstream benchmarks, with programming and agent capabilities approaching Claude Fable 5, while its hands-on programming experience surpasses that of other Chinese models.
On Terminal-Bench 3.0, which measures a model’s ability to complete complex tasks in real terminal environments, GLM-5.3’s score increased from 4.6 to 28.3;
On DeepSWE v1.1, which focuses on long-horizon software engineering and continuous code modification capabilities, its score increased from 46.2 to 66.9;
On Agents' Last Exam, which covers various real-world professional scenarios and emphasizes cross-tool collaboration and long-horizon tasks, its score increased from 23.8 to 28.5;
On GDPval-AA v2, which covers 44 occupations and evaluates real, high-value knowledge work, it scored 1,769, demonstrating professional task execution capabilities emerging from its programming abilities.
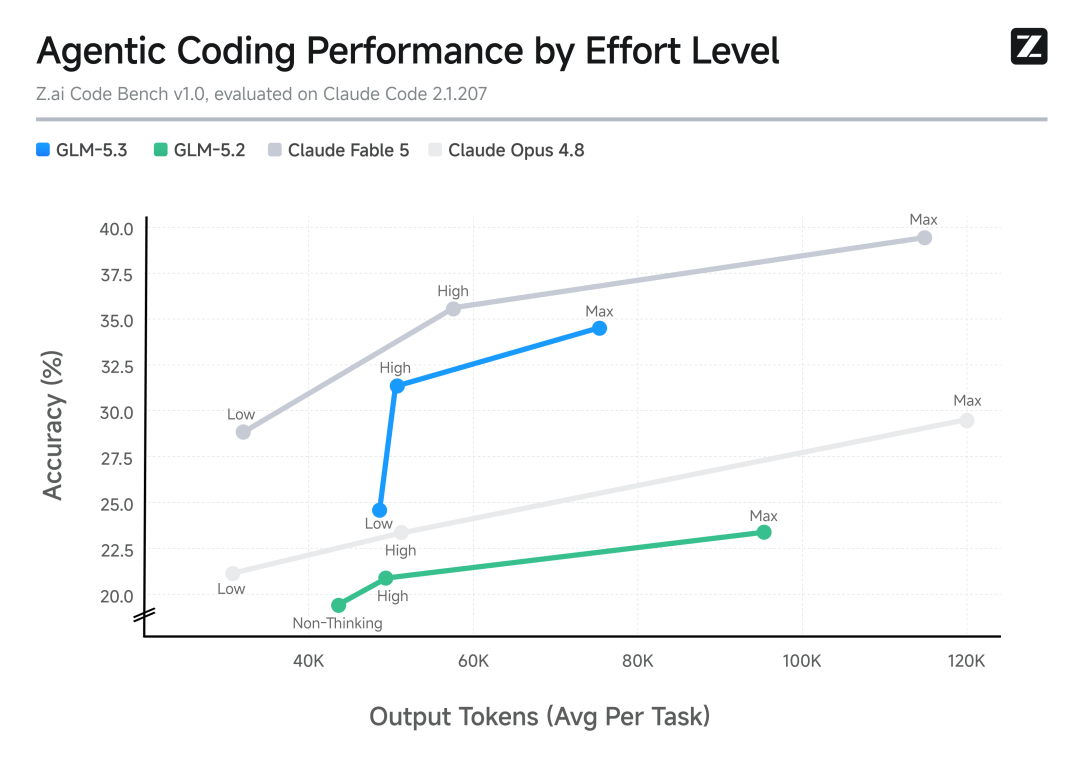
Zhipu’s self-developed Z.ai Code Bench evaluates a model’s overall hands-on performance in real-world programming scenarios. The model is placed in a complex local development environment and performs end-to-end tasks at different reasoning levels, more closely reflecting developers’ actual experience when using a Coding Agent.
The test results show that GLM-5.3 achieves a better balance between performance and token efficiency. At the High level, GLM-5.3 achieved an accuracy rate of 31.4%, exceeding the 29.5% achieved by Claude Opus 4.8 at its highest level. It output approximately 50,000 tokens per task on average, while Opus 4.8 required approximately 120,000 tokens, meaning that GLM-5.3 can complete tasks through a shorter execution path.
Starting today, Zhipu’s official programming tool ZCode and productivity tool AutoClaw are available, along with GLM Coding Plan access and subscriptions for all users.
TraeWork / TraeCode / Coze, WorkBuddy / CodeBuddy, Qoder / QwenWork, CatPaw, JoyCode, OpenCode, and other coding platforms are opening early access.
The API will be available soon. The complete model weights will be open-sourced within two weeks. Before then, necessary security hardening must be completed to limit its potential attack capabilities as much as possible while preserving its defensive value.
At 13:00 today, GLM Coding Plan quotas will be reset for all users, and the restored usage quota will be visible in the “Usage Statistics” section of every user’s account.