

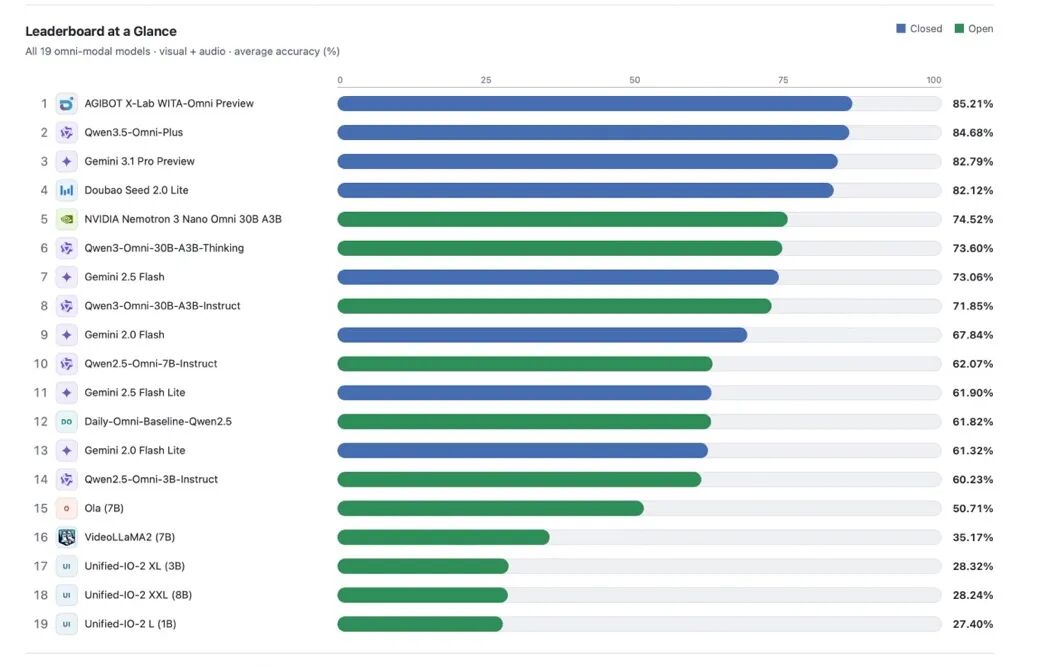
According to a post on the AgiBot AGIBOT WeChat public account, the latest evaluation results from DailyOmni, an authoritative leaderboard for embodied omni-modal understanding, were recently released. AgiBot’s self-developed embodied-native omni-modal foundation model, WITA-Omni Preview, topped the leaderboard with an overall score of 85.21, thanks to its leading audio-video joint understanding and temporal reasoning capabilities. It surpassed leading models from China and abroad, including Qwen, Gemini, Doubao, and NVIDIA models, and ranked first in six of the eight sub-metrics.
According to ITHome, DailyOmni is an industry-recognized third-party leaderboard for evaluating audio-video temporal alignment and cross-modal joint reasoning capabilities. Unlike conventional evaluation tasks focused on images and text or short videos, the leaderboard makes extensive use of audio-video materials from real-world open environments. It primarily tests a model’s overall ability to integrate visual scenes and environmental audio, accurately identify audio-visual correspondences and event sequences, and perform cross-modal semantic reasoning. These capabilities closely align with the core perception abilities required by humanoid robots for human-robot interaction in real physical spaces.
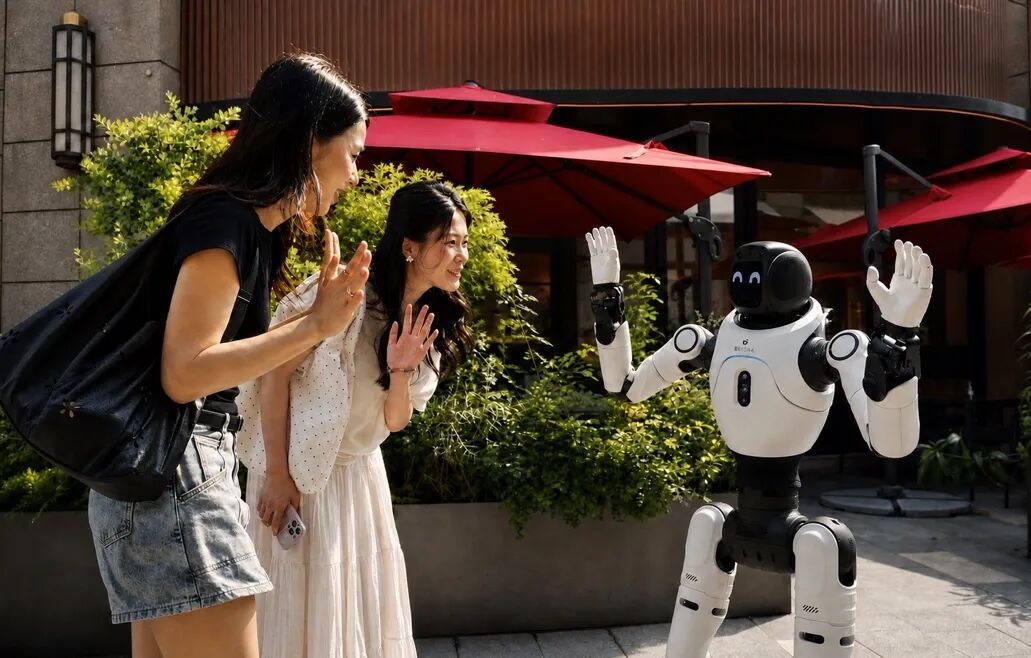
According to the company, the key to WITA-Omni’s leading performance is that it does not simply “put” a chat model into a robot. Instead, it elevates physical actions and facial expressions to first-class outputs on par with speech, using a native end-to-end model to jointly drive perception, decision-making, and expression. This extends the Thinker–Talker paradigm into the Thinker–Talker–Actor architecture for embodied outputs.
WITA-Omni’s lead does not rely solely on model scale, but comes from a hierarchical data system and targeted training methods built around embodied omni-modal interaction. During the mid-training stage, WITA-Omni uses tens of millions of hours of open-source and proprietary multimodal data, further upgrading strong text and vision foundations into an omni-modal model capable of “hearing, understanding what it sees, and performing joint audio-visual reasoning.”
In addition, publicly available audio-video data typically lacks turn-taking, response timing, actions, and facial expressions from real interactions, making it difficult to directly train an end-to-end embodied interaction model. To address this, AgiBot built a large-scale, high-quality omni-modal dataset centered on people and designed for real-world interaction scenarios, fully preserving the natural temporal relationships among sound, visuals, language, actions, and facial expressions.