

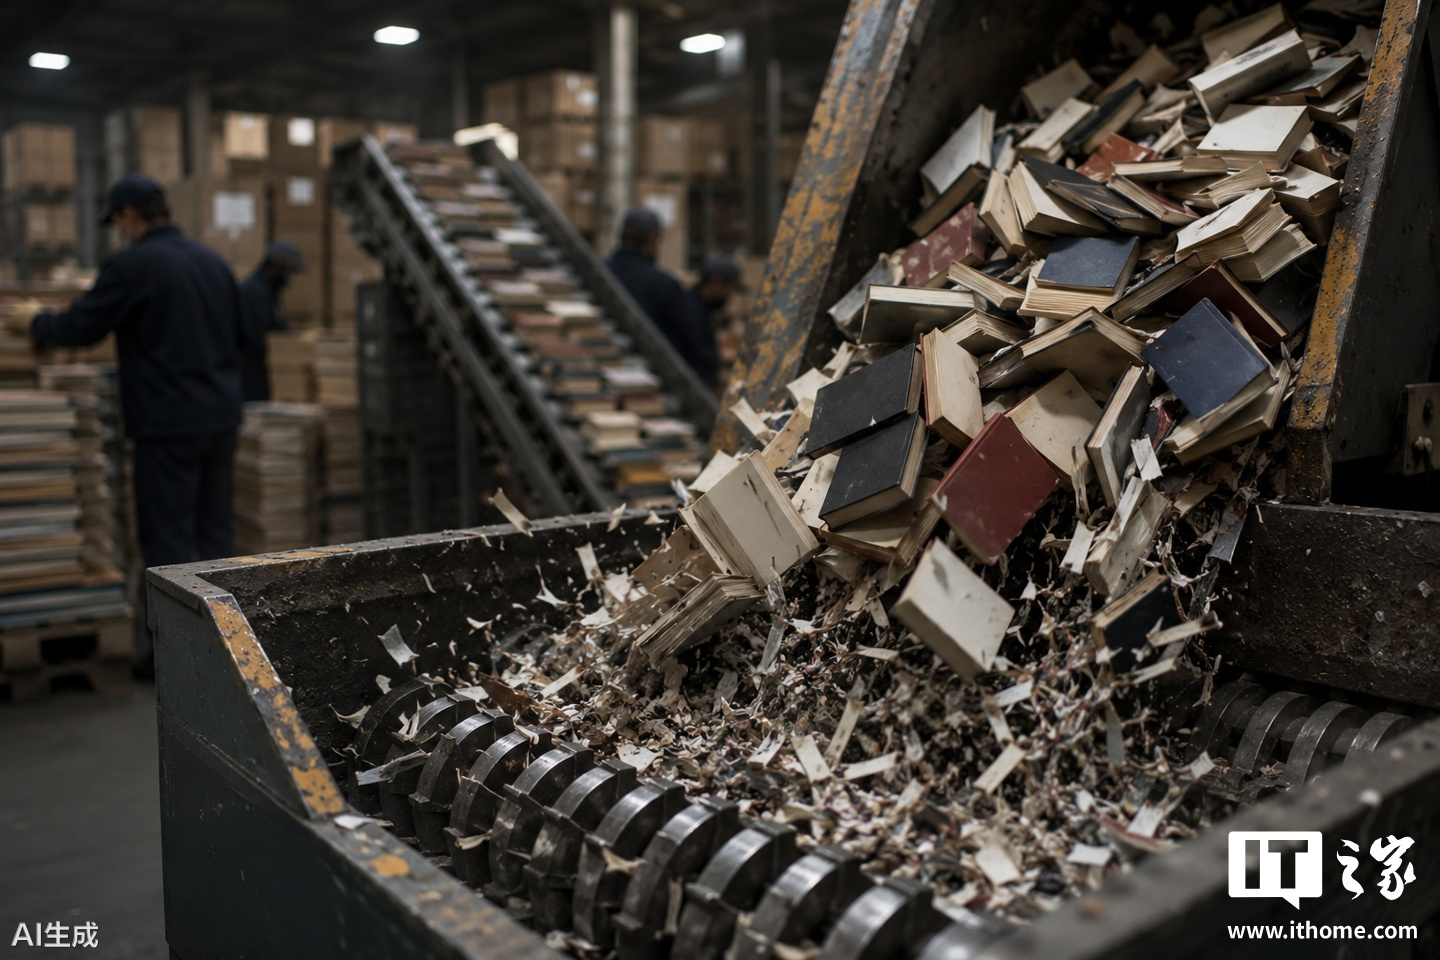
After driving memory and storage resources into increasingly short supply, AI companies now appear to be turning their attention to humanity’s literary heritage. Investigative outlet 404 Media recently reported that multiple AI companies are purchasing used books on a large scale through intermediaries to obtain high-quality training data for AI models while avoiding public backlash.
AI’s development depends on vast amounts of data, but not all data is valuable; the key lies in data quality. In recent years, large quantities of low-quality AI-generated content, commonly known as “AI slop,” have flooded the internet, contaminating the data environment and reducing the effectiveness of further AI training. As a result, leading AI companies have begun searching again for content created by humans, especially printed books published before 2022, because such content is more likely to be original work that has not yet been contaminated by AI-generated content.
In fact, AI companies have previously used printed books to train models. Anthropic, one of the major AI companies currently involved in copyright litigation, reportedly spent millions of dollars purchasing large quantities of printed books to extract their contents for training its Claude AI models, after which the books were destroyed. The company is said to have purchased the books in large quantities from Better World Books. Although a court ruled that using lawfully purchased books to train AI constituted “fair use” under copyright law, Anthropic was ultimately ordered to pay as much as $1.5 billion in damages for infringing the copyrights of authors and publishers by keeping a database containing 7 million pirated books for an extended period. (Note: at the current exchange rate, approximately RMB 10.162 billion.)
A similar dispute has also emerged involving Google. Recently, a coalition of publishers sued Google, alleging that it used millions of copyrighted books without authorization to train its Gemini AI models.
ISBNdb, an online database containing catalog information for more than 111 million books, has long been an important platform for booksellers, libraries, and distributors. As the AI industry has developed rapidly, ISBNdb has also begun adjusting its business direction by launching large-scale book-purchasing services specifically for AI companies.
404 Media reported that the orders range from 1,000 books per purchase to 1 million books per purchase.
An unnamed professional bookseller said that book sales had experienced unprecedented growth since April this year. In the past, even during good periods, the business could sell only about 20 books per week; in recent months, however, weekly sales have surged to several hundred books, approximately five times the usual volume.
Other booksellers on used-book platforms such as Alibris and Biblio have also reported similar instances of bulk purchasing.
Although there is currently no conclusive evidence that these purchases definitely originated from ISBNdb or a particular AI company, there are many unusual signs. For example, almost all of the books being purchased in bulk carry an International Standard Book Number (ISBN), a 13-digit code that serves as a unique identifier for books worldwide.
In addition, these purchases show almost no preference for subject, genre, or author. Novels, textbooks, and professional books all fall within the purchasing scope. Even more surprisingly, buyers appear completely unconcerned about price: they will purchase books directly even when some are clearly priced above market value.
During Anthropic’s copyright litigation, Tom Harvey, who had participated in the Google Books project and later managed Anthropic’s “Project Panama” digitization project, confirmed that Anthropic had hired multiple professional document-scanning companies to digitize printed books.
One of its partner companies was Datamation Information Services, which provides both non-destructive and destructive book-scanning services.
Non-destructive scanning typically uses overhead scanners, flatbed scanners, or V-shaped scanning equipment to digitize books without disassembling them. Destructive scanning, by contrast, involves directly taking books apart and feeding each page into a high-speed industrial scanner.
Because destructive scanning is more efficient and less expensive, AI companies generally choose this approach, ultimately resulting in the destruction of millions of printed books.
There is no doubt that printed books represent a vast treasure trove of knowledge for AI. However, this practice has also sparked growing ethical controversy.
Critics argue that it remains unclear whether AI companies distinguish between ordinary books and valuable or out-of-print books during digitization. If these rare books are destroyed, they may disappear from circulation permanently.
An even larger issue is that the scanned content ultimately enters AI companies’ private databases, where it is used only to train AI and is inaccessible to the general public.
This means that people may be able to obtain more intelligent AI, but the price could be that vast amounts of knowledge accumulated by humanity will no longer be preserved for future generations in an open and accessible form.