

Alibaba Cloud's ModelScope Community public account announced late yesterday (the 12th) that Alibaba's Qwen team has officially released the model weights for Qwen3.8-2.4T-A95B.
This is the first time a Qwen-Max-level model has had its weights open-sourced. The model has 2.4T total parameters, activates 95B parameters per token, natively supports a 262,144-token context, and can be extended to 1,010,000 tokens.
Qwen3.8 continues the hybrid architecture of Qwen3.5, focusing on improving end-to-end completion capabilities for coding, office work, research, and long-horizon agent tasks. The official cloud version, Qwen3.8-Max, is based on this released-weight model and adds more production capabilities.
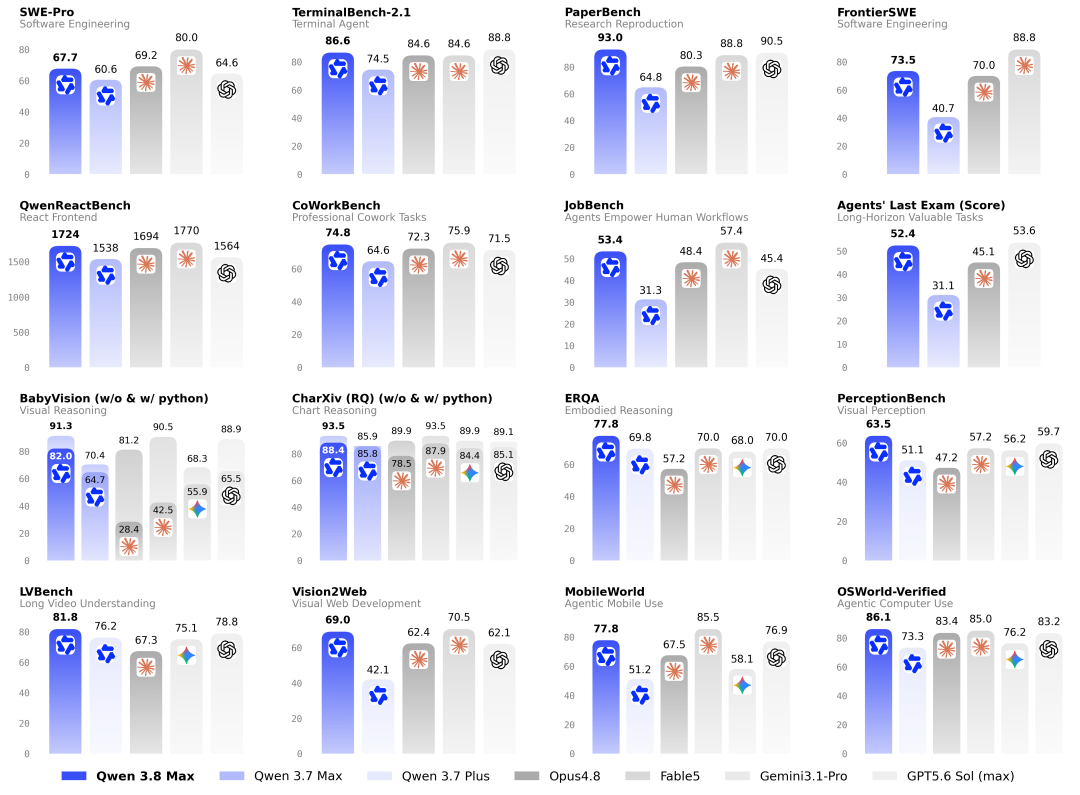
The official evaluations cover coding agents, general-purpose agents, professional work, and long-context tasks. Compared with models such as Opus 4.8, Fable 5, and GPT 5.6 Sol, the results vary by category, while Qwen3.8-A95B achieved relatively high scores among the listed models on benchmarks including PaperBench and IFBench.
The relevant links are as follows:
Model: https://modelscope.cn/models/Qwen/Qwen3.8-2.4T-A95B
Blog: https://qwen.ai/blog?id=qwen3.8
Qwen Studio: https://chat.qwen.ai
Qwen3.8-2.4T-A95B is an autoregressive language model with 2.4T total parameters and 95B active parameters per token. Each MoE layer contains 512 experts. Each token selects 10 routed experts and simultaneously activates 1 shared expert.
The model also underwent multi-step MTP (Multi-Token Prediction) training, enabling inference engines that support this mechanism to predict multiple subsequent tokens.
According to the introduction, the office-work and agent post-training for Qwen3.8-Max consists of three stages:
Continuously expand real-world environments while decoupling them across independent dimensions: tasks (Task) (single task → multiple tasks → multiday tasks), workspaces (Workspace) (multiple files → hierarchical directories → complex heterogeneous directories), and harnesses (different categories, versions, and skills). This allows the number of environments to grow naturally through composition rather than relying on individually customized integrations.
Build a unified reward system that internalizes the heterogeneous verification methods used in real-world tasks. The system covers execution-based checks, rubric-based evaluations of text and rendered visual outputs, and agentic checks. We unify multiple formats and modalities within one reward system, providing consistent and reliable reward signals for all environments and eliminating the inconsistencies inherent in maintaining task-specific verifiers.
Build an online data balancer that reconstructs each batch so that its distributions across tasks, difficulty levels, workspaces, and harnesses are highly balanced. This reduces gradient variance between batches and supports the stable, continuous scaling of training compute for reinforcement learning.