

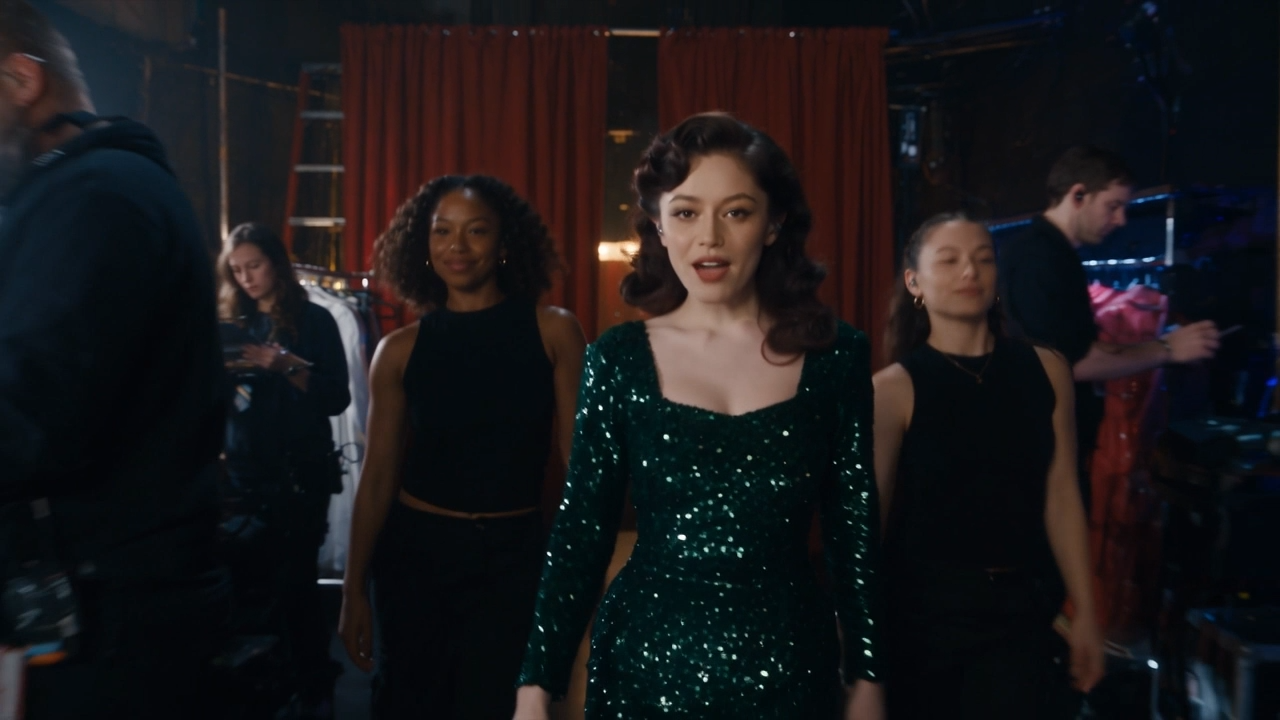
ByteDance announced today (July 31) the launch of the Seedance 2.5 video generation model in China. It can generate high-quality 30-second video clips in a single run and is being gradually rolled out on Jimeng AI and Doubao Pro. API services will also soon be integrated into Volcano Ark.
According to the official announcement, Seedance 2.5 continues the unified multimodal audio-video joint generation architecture of Seedance 2.0, with a focus on improving long-form narrative, multimodal reference, and editing capabilities.
The model is designed for scenarios including film and television, advertising, education, industrial manufacturing, embodied intelligence, and autonomous driving. Its goal is to shift video generation from “generating a clip” to “completing a creative work.”
For generation, Seedance 2.5 increases the maximum duration of a single video generation from 15 seconds to 30 seconds and supports multiple extensions. According to the official announcement, the model can organize multiple logically connected shots within 30 seconds, allowing a story to unfold through setup, development, turning point, and conclusion.
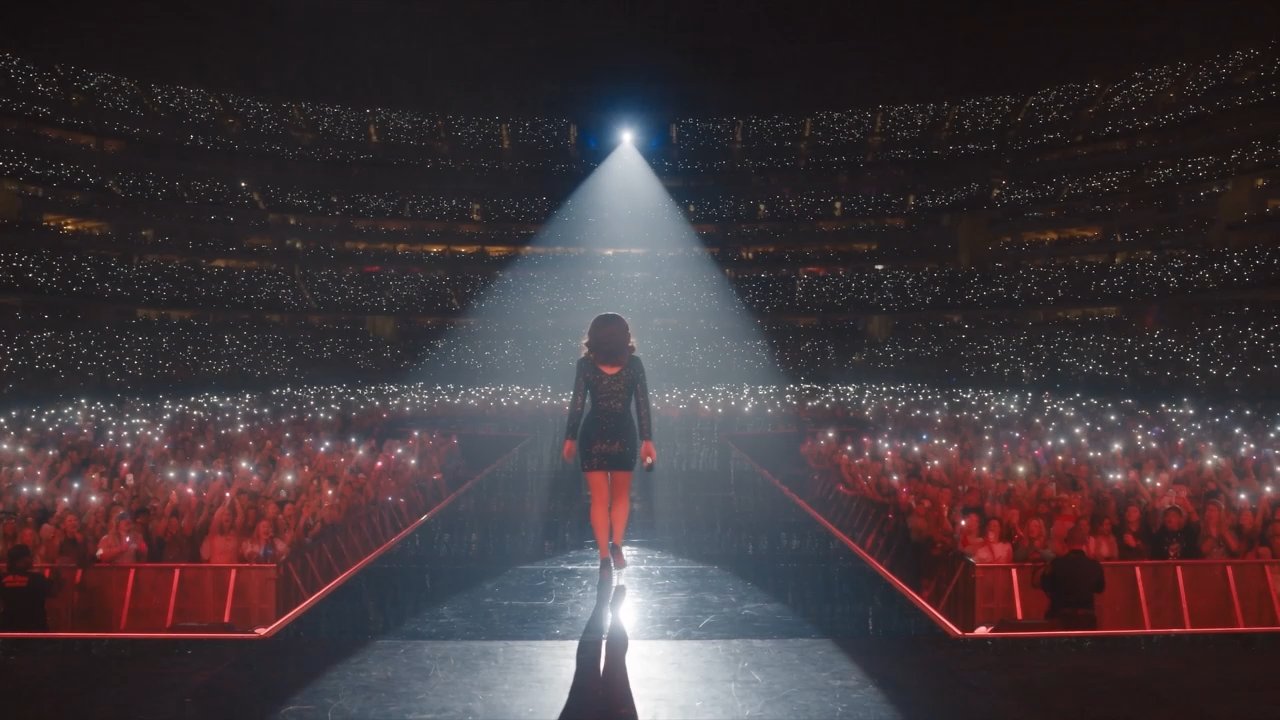
In an official example, a continuous-shot performance by a singer demonstrates a complete narrative: The camera moves through a gap in heavy red curtains into a warm backstage dressing room; a young female singer adjusts her earpiece as a staff member reminds her to go on stage; the singer walks through the backstage corridor, interacts with a dance partner, and takes a microphone; she then steps onto the stage, and the camera finally pulls back to a wide view of the stadium, showing the audience, light boards, glow sticks, and cheers.
For multiple extensions, an official example asked the model to generate another 30 seconds based on an existing video while maintaining consistency in the main characters, setting, visual style, voices, and sound effects. The example plot includes a series of continuous actions: a little boy runs through a train carriage holding a soccer ball, rushes out of the doors after the subway stops, and is chased and eventually caught by the male protagonist.
Seedance 2.5 supports users entering up to 30 images, 10 video clips, and 10 audio clips as reference materials in a single input. According to the official announcement, the model can comprehensively understand elements such as composition, settings, style, characters, and props in different materials and use them for video generation according to instructions.
In scenes featuring multiple people and ensemble narratives, Seedance 2.5 can simultaneously reproduce the appearances and voices of multiple characters while maintaining stable subject characteristics. The 30-second concert clip demonstrated by the official announcement uses a 16:9 landscape format and a cinematic realistic style, with reference materials covering a setting image, a pianist, a cello, a violin, a lead singer, an orchestra, a choir, and the audience area.
Reference links
Seedance 2.5 project homepage