

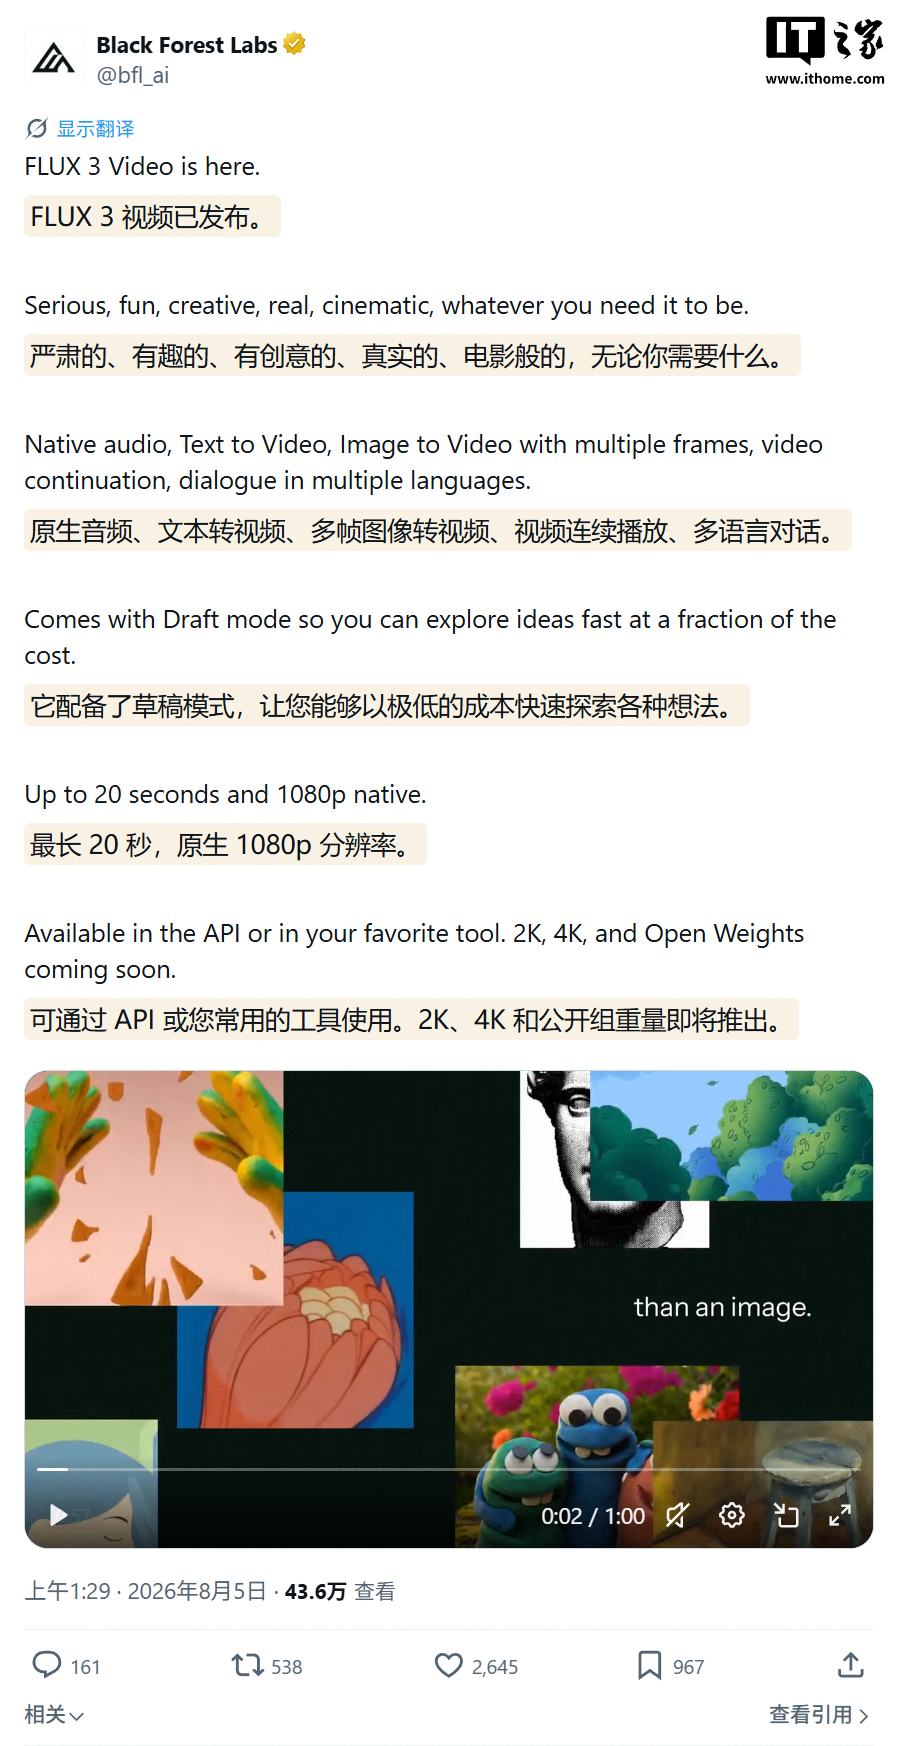
Black Forest Labs announced yesterday (August 5) the official launch of the FLUX 3 video generation model, which supports videos of up to 20 seconds at native 1080p resolution and outperforms ByteDance's Seedance 2.0, Minimax's H3, and other models.
The FLUX 3 model was launched in Early Access on July 23, using a unified architecture to jointly learn images, videos, and audio.
FLUX 3 can generate videos of up to 20 seconds in a single generation, complete with native audio. The company says the model supports text-to-video, image-to-video, video-to-video, continuation from input videos and audio, keyframe-to-video, multilingual dialogue, and multi-shot sequencing.
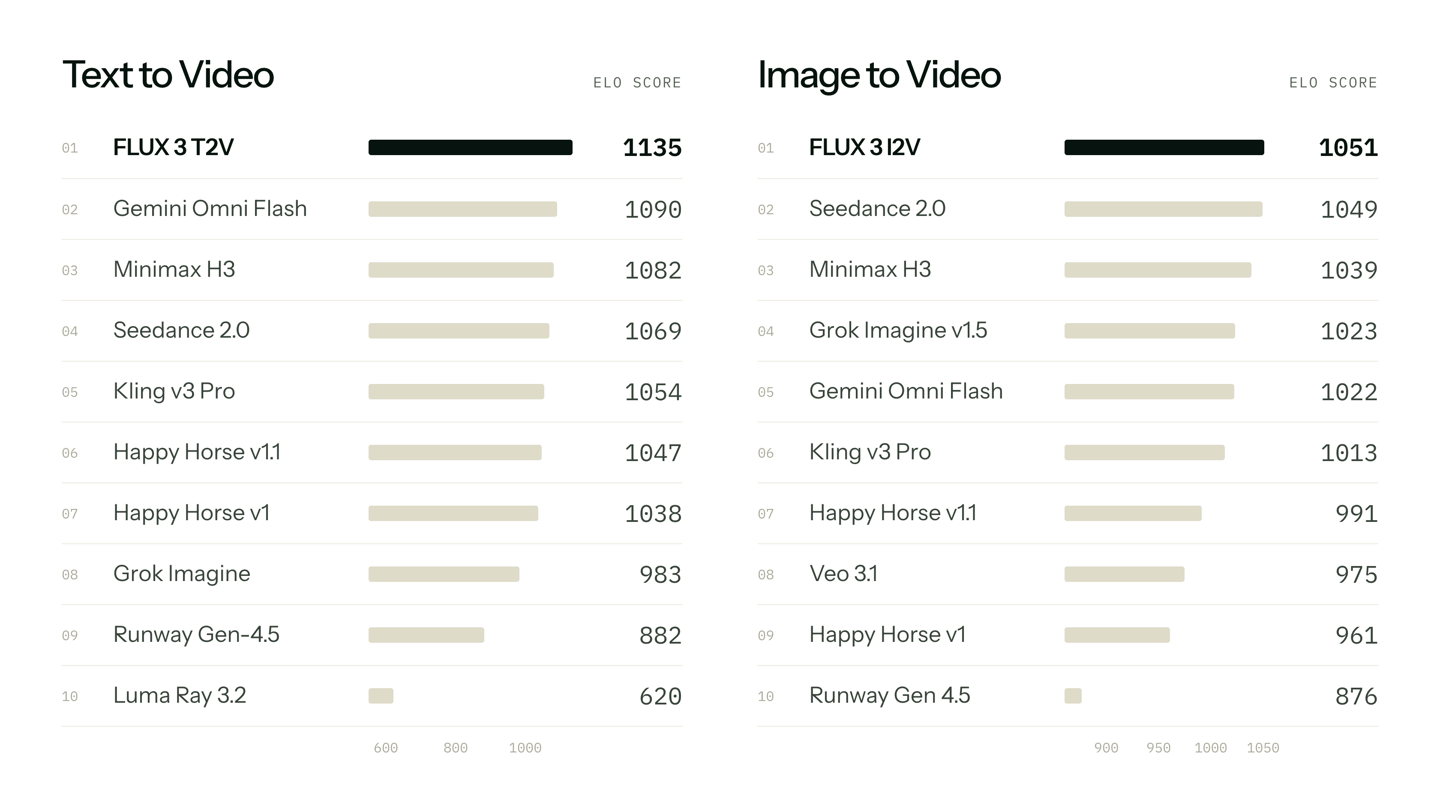
According to data published in the official blog post, the model scored 1,135 points in text-to-video generation, surpassing the Gemini Omni Flash and Minimax H3 models; in image-to-video generation, it scored 1,051 points, surpassing the Seedance 2.0 and Minimax H3 models.
In terms of pricing, usage of the model is calculated based on the number of seconds of video output:
Draft mode (fast / economical) is limited to HD. Text-to-video or image-to-video costs $0.06 per second (note: approximately 0.41 yuan at the current exchange rate), while video-to-video costs $0.12 per second (approximately 0.81 yuan at the current exchange rate).
Under normal HD conditions, text-to-video or image-to-video costs $0.17 per second (approximately 1.1 yuan at the current exchange rate), while video-to-video costs $0.41 per second (approximately 2.8 yuan at the current exchange rate).
In Full HD mode, text-to-video or image-to-video costs $0.29 per second (approximately 2 yuan at the current exchange rate), while video-to-video costs $0.53 per second (approximately 3.6 yuan at the current exchange rate).