

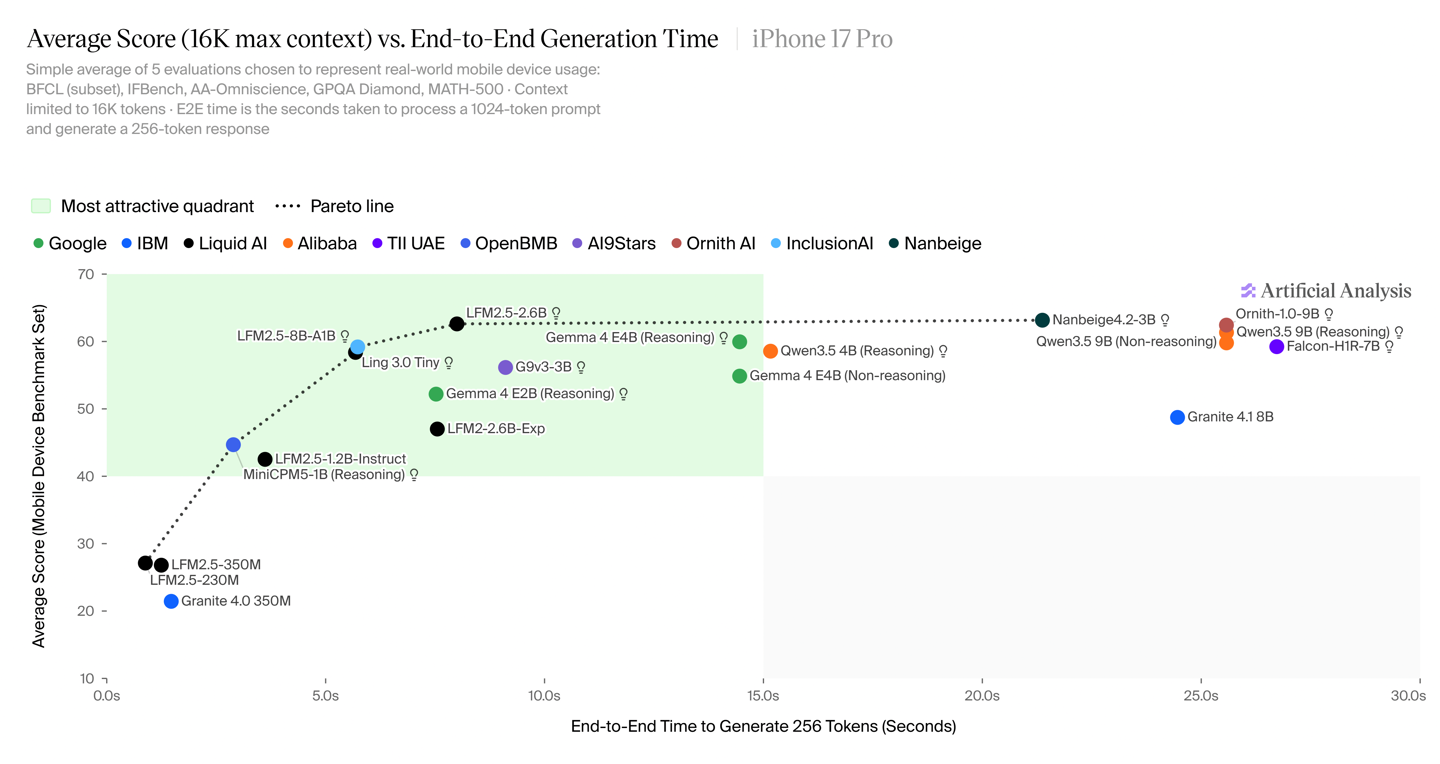
On August 24, Artificial Analysis published a blog post announcing a collaboration with Liquid AI to launch a mobile AI benchmark focused on the performance of AI models on the Apple iPhone 17 Pro.
Artificial Analysis is responsible for the intelligence evaluation system, while Liquid AI is responsible for the inference performance evaluation system. The two parties selected five benchmarks:
BFCL (Berkeley Function Calling Leaderboard)
IFBench (instruction-following evaluation)
AA-Omniscience (knowledge and cognition evaluation)
GPQA Diamond (advanced question-answering evaluation)
MATH-500 (mathematics problem evaluation).
The evaluated models were 4-bit quantized models no larger than 8GB, including Gemma 4 E2B and LFM2-2.6B-Exp.
With the context length limited to 16K tokens, Nanbeige4.2-3B and LFM2.5-2.6B achieved the highest average benchmark scores. With the response time limited to a maximum of 1 minute, LFM2.5-8B-A1B ranked first, followed by LFM2-2.6B-Exp, Gemma 4 E4B (Non-reasoning), and Granite 4.1 8B.
Nanbeige4.2-3B was developed by the Nanbeige Laboratory under BOSS Zhipin. It contains only 3 billion non-embedding parameters, with approximately 4 billion parameters in total, and uses a Looped Transformer architecture. By reusing Transformer layers for two cycles without increasing the parameter count, it improves the model's effective computational depth and capacity.
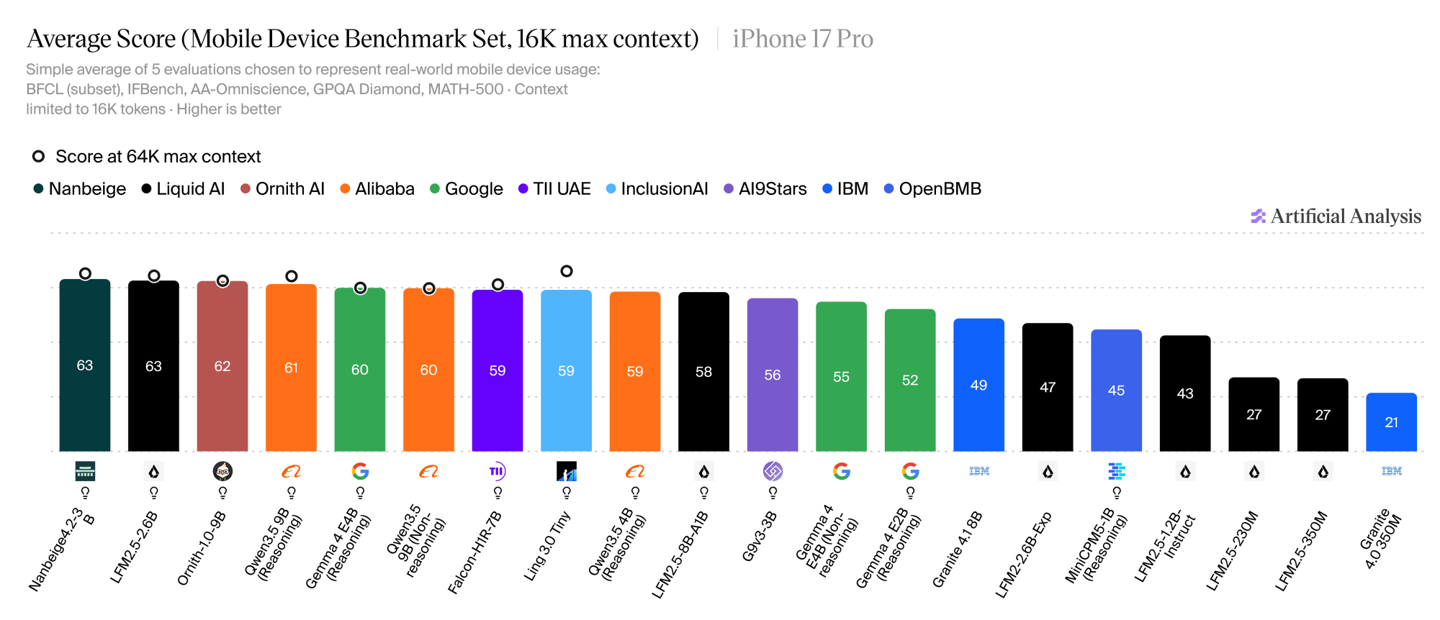
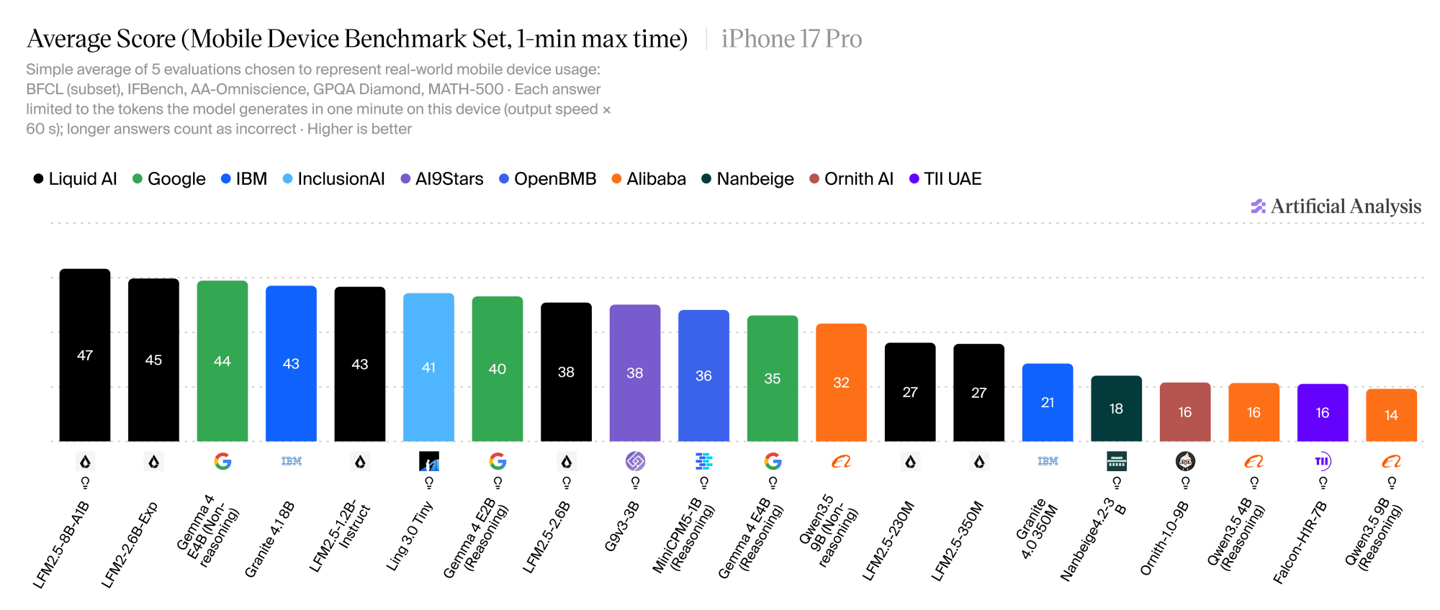
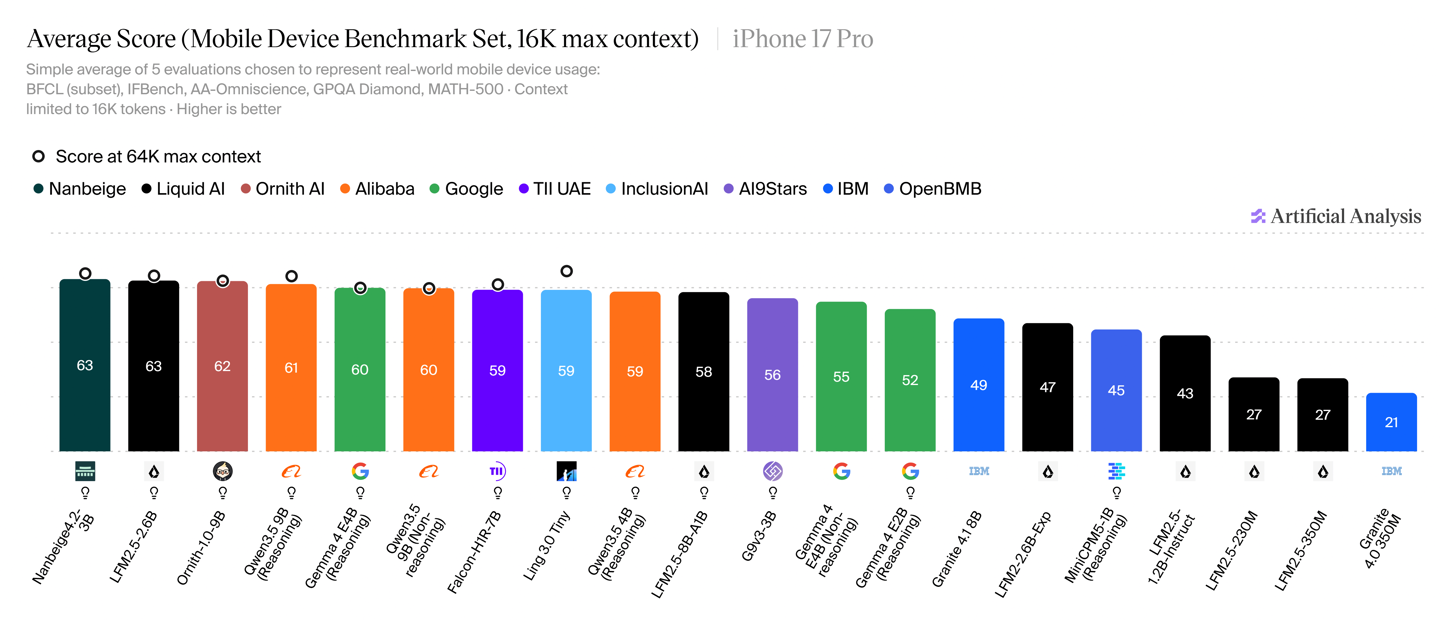
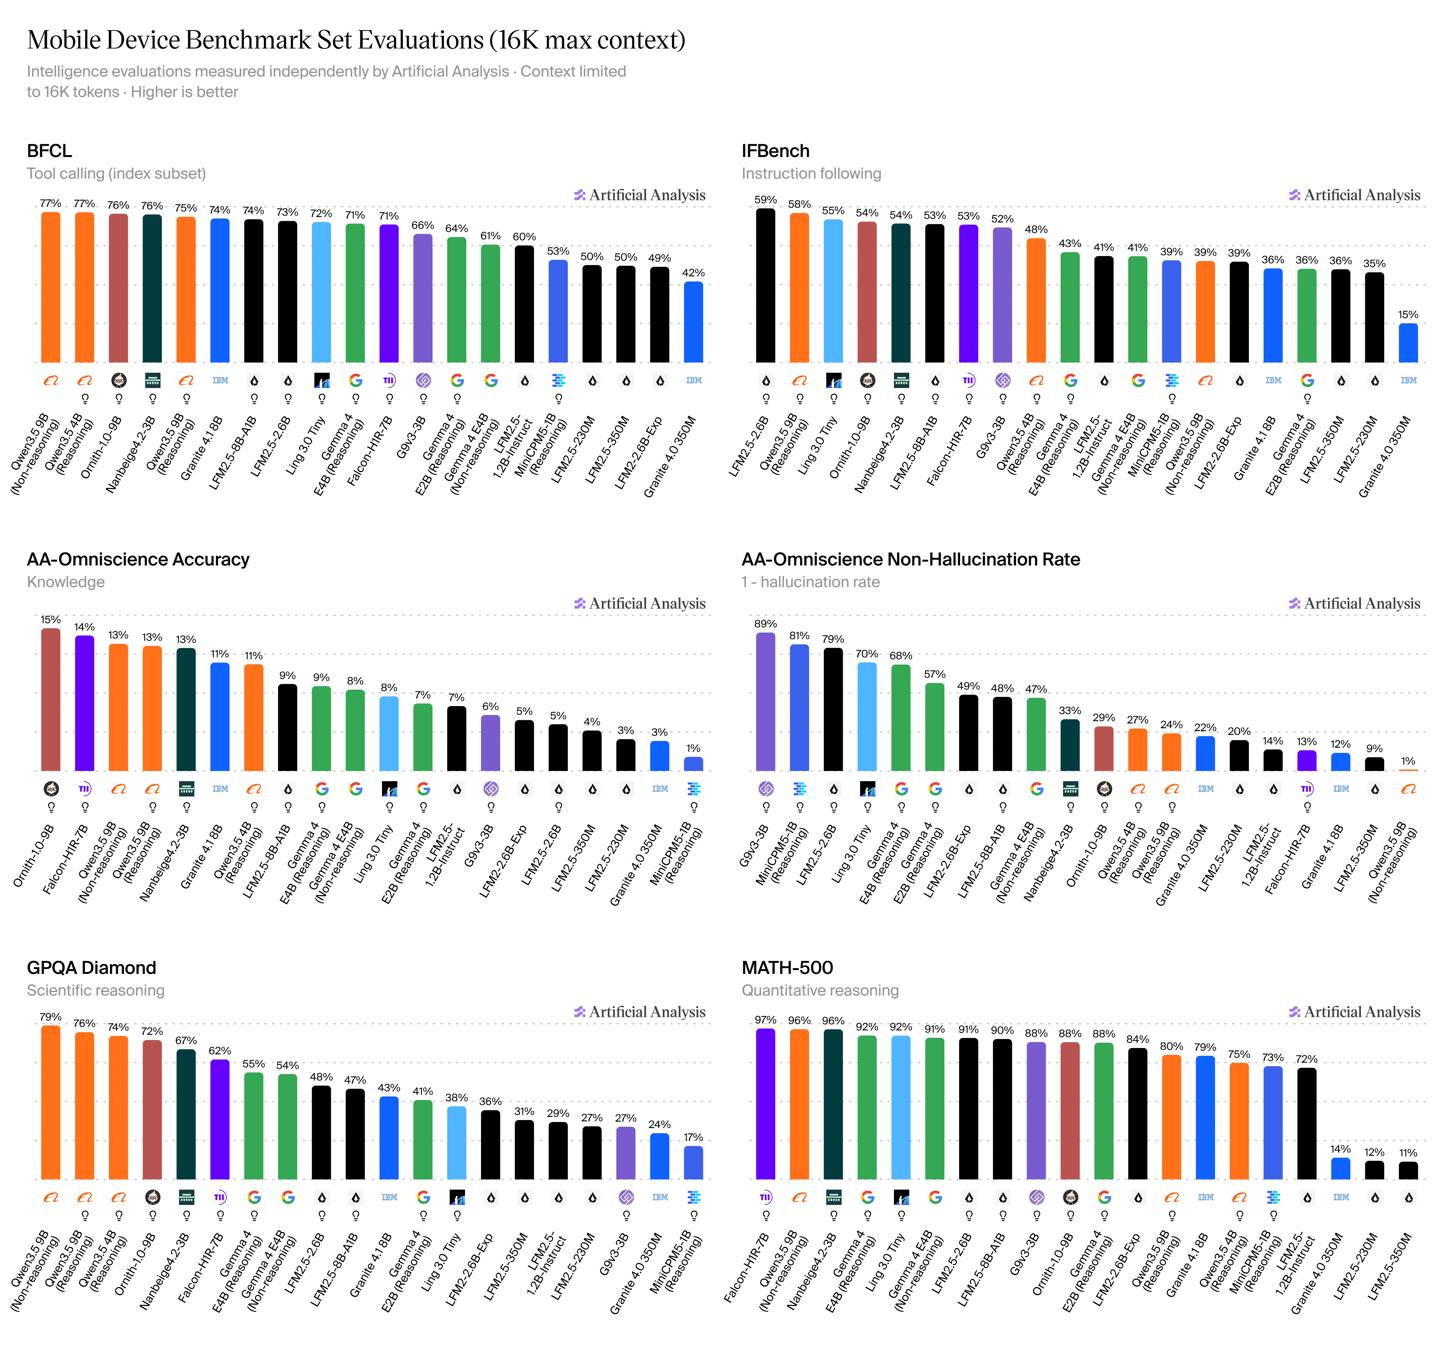
Related screenshots are shown below:
