

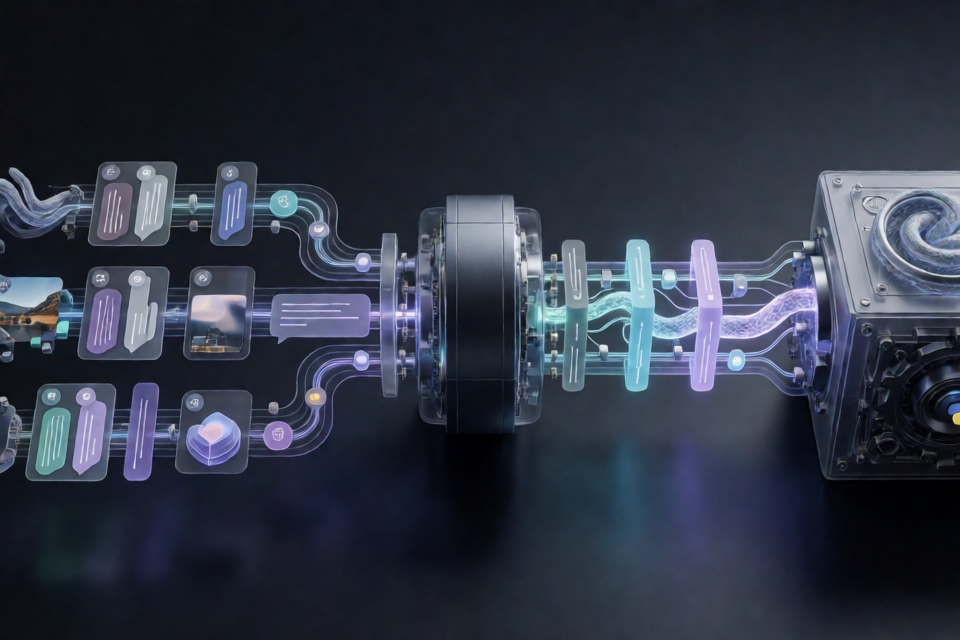
What is deepseek-recipe?
deepseek-recipe is a collection of Rust libraries and Python bindings for connecting API services to DeepSeek inference backends. It converts requests from supported API formats into a shared Conversation representation, renders those conversations as DeepSeek V4 or V4.1 prompts, and converts model output back into the corresponding response format.
The project is a protocol and prompt-processing layer rather than a complete inference server. You must provide model inference, HTTP transport, and tool execution separately.
How the processing pipeline works
- Receive a request in the Messages, Chat Completions, or Responses format.
- Convert the request into the library's common Conversation format.
- Render the conversation as a DeepSeek V4 or V4.1 prompt, or encode it into token IDs.
- Send the prompt or token IDs to an external inference backend.
- Parse the generated output, including supported thinking content, tool calls, JSON objects, and stop sequences.
- Return a complete or streaming response in the format expected by the client.
deepseek-recipe does not run the model, execute tools, or expose an HTTP service by itself. Example Rust and Python servers are available in the repository as integration references.
Key features
- Unified protocol conversion: Handles Messages, Chat Completions, and Responses requests and responses.
- DeepSeek prompt encoding: Renders DeepSeek V4 and V4.1 conversations as prompts or token IDs.
- Streaming and complete responses: Supports conversion of both response styles.
- Generation settings: Carries thinking mode, reasoning effort,
temperature,top_p, and output token limits. - Output parsing: Recognizes thinking content, client tool calls, JSON object output, and stop sequences.
- Multimodal input: Accepts images supplied as base64 data or external URLs. The image package provides DeepSeek V4.1 preprocessing with OpenCV.
- Tool definitions: Supports function tools. The Responses API additionally supports tool namespaces and the
apply_patchcustom tool.
Python installation and setup
Requirements
The Python bindings require Python 3.10 or newer. Install the published package with pip:
python3 -m pip install deepseek-recipeThe installed module is imported as deepseek_recipe.
Convert a Chat Completions request
The following example constructs a Chat Completions request, converts it into the common Conversation representation, and renders that conversation as a DeepSeek V4.1 prompt:
from deepseek_recipe import (
    ChatCompletionRequest,
    ConversionOptions,
    DeepseekV41Encoding,
)

request = ChatCompletionRequest({
    "model": "deepseek-flash",
    "messages": [
        {"role": "user", "content": "Hello"}
    ],
})

converted = request.convert(ConversionOptions())
rendered = DeepseekV41Encoding().render_conversation(
    converted.conversation
)

print(rendered.prompt)
Understand each step
ChatCompletionRequestreads the incoming Chat Completions data.request.convert(ConversionOptions())normalizes the request into a Conversation.DeepseekV41Encoding()selects the DeepSeek V4.1 encoding rules.render_conversationcreates the model-ready representation.rendered.promptcontains the prompt to send to your external inference backend.
After inference, use the project's response-conversion and output-parsing components to translate generated model output into the API format required by your client. The exact integration depends on whether your backend returns complete output or streams generated data.
Rust installation and setup
Add the crates
Add the protocol conversion and encoding crates to a Rust project:
cargo add deepseek-recipe@0.1 deepseek-recipe-encoding@0.1If you are building from source or enabling image processing, consult the repository's development guide for build instructions and image dependencies.
Render a DeepSeek V4.1 prompt
use deepseek_recipe::openai::ChatCompletionRequest;
use deepseek_recipe::request::{ConversionOptions, ProtocolRequest};
use deepseek_recipe_encoding::PromptEncoding;
use deepseek_recipe_encoding::v4::dsv41::DeepseekV41Encoding;
use serde_json::json;

fn main() -> Result<(), Box<dyn std::error::Error>> {
    let request: ChatCompletionRequest = serde_json::from_value(json!({
        "model": "deepseek-flash",
        "messages": [
            {"role": "user", "content": "Hello"}
        ],
    }))?;

    let converted = request.convert(ConversionOptions::default())?;
    let rendered = DeepseekV41Encoding::new()
        .render_conversation(&converted.conversation);

    println!("{}", rendered.prompt);
    Ok(())
}
Here, Serde deserializes JSON into ChatCompletionRequest. The ProtocolRequest trait provides request conversion, while PromptEncoding provides conversation rendering. The resulting prompt can then be passed to a separately managed inference engine.
Explore the encoding and decoding demo
The repository includes a web interface for rendering prompts, inspecting special tokens, and decoding complete model output into Chat Completions, Responses, or Messages formats.
From the repository root, run:
cargo run -p encoding-decoding-demo --lockedThen open http://127.0.0.1:7778 in a browser.
This demo is useful for checking prompt structure and understanding how generated output maps back to supported API response formats before integrating the libraries into a server.
Package overview
deepseek-recipe: Protocol conversion and model-output parsing.deepseek-recipe-core: Shared conversation, message, image, and tool types.deepseek-recipe-encoding: DeepSeek V4 and V4.1 prompt rendering and token encoding.deepseek-recipe-image: Image fetching and preprocessing.deepseek-recipe-python: Python bindings exposed through thedeepseek_recipeimport.encoding-decoding-demo: Browser-based prompt and output inspection.server-rs: An Axum API example using mock inference.server-py: A FastAPI example using mock inference.
Advanced integration tips
Keep protocol handling separate from inference
Use deepseek-recipe at the boundaries of your application. Convert incoming requests before inference and parse generated output afterward. Keep model loading, batching, scheduling, and hardware management inside your inference backend.
Choose prompts or token IDs deliberately
You can render conversations as text prompts or encode them into token IDs. Use prompt rendering when your backend accepts formatted text. Use token encoding when your backend works directly with tokenizer IDs. The repository's tokenizer guide covers encoding conversations and decoding backend token IDs.
Plan streaming as an end-to-end feature
Both Rust and Python support converting model output into streaming responses. Your transport and inference backend must also stream data; the library does not provide those layers. Follow the streaming response guide when connecting incremental model output to a client-facing API.
Handle images before inference
Requests may reference images through base64 content or external URLs. The dedicated image component supports fetching and DeepSeek V4.1 preprocessing with OpenCV. Ensure the required image dependencies are installed when building from source.
Keep tool execution outside the library
The project can represent tool definitions and parse client tool calls, but it does not execute those tools. Your application must validate each call, run the appropriate function or custom tool, and add the result to the next conversation turn.
Respect the current boundaries
Before designing an API around the project, account for features that are not yet supported:
- Token probabilities through
logprobsortop_logprobs. - Document content, audio or video input, and retrieval by
file_id. - Server-executed tools such as
web_search. - JSON Schema and regular-expression output constraints.
- Enforcement of tool
strictsettings. - Multiple Chat Completions choices when
n > 1. - Responses custom tool definitions other than
apply_patch. - Responses conversation storage or context retrieval through
previous_response_id. - Encrypted thinking content through
encrypted_content.
Conclusion
deepseek-recipe provides reusable Rust and Python components for normalizing several API protocols, creating DeepSeek V4 and V4.1 inputs, and translating generated output back into client-facing responses. Start with the basic request conversion example, inspect behavior through the demo, and then connect the conversion pipeline to your own inference, transport, and tool-execution infrastructure.
The project code and public documentation are available under the MIT License.