

Understand the Scope of Use First
ARTEX is intended only for personal learning, code research, and technical validation in locally isolated environments. According to the project statement, it must not be used to scan, probe, exploit, or attack any online system, website, internet-connected system, or production environment, even if the target belongs to you or you have authorization. Before you begin, confirm that you understand and comply with the project's AGPL-3.0 license, applicable cybersecurity laws, and the usage restrictions and disclaimers in the repository.
This article assumes local deployment in a secure, isolated environment and explains how to install ARTEX, configure PostgreSQL and an LLM, observe tasks through the interface, and use features such as asset synchronization and vulnerability retesting.
ARTEX is an AI multi-agent system with a Go backend and Next.js frontend. The project provides an online Demo for previewing the interaction experience. In production, the frontend can be embedded into a single binary using Go's go:embed.
What ARTEX Can Do
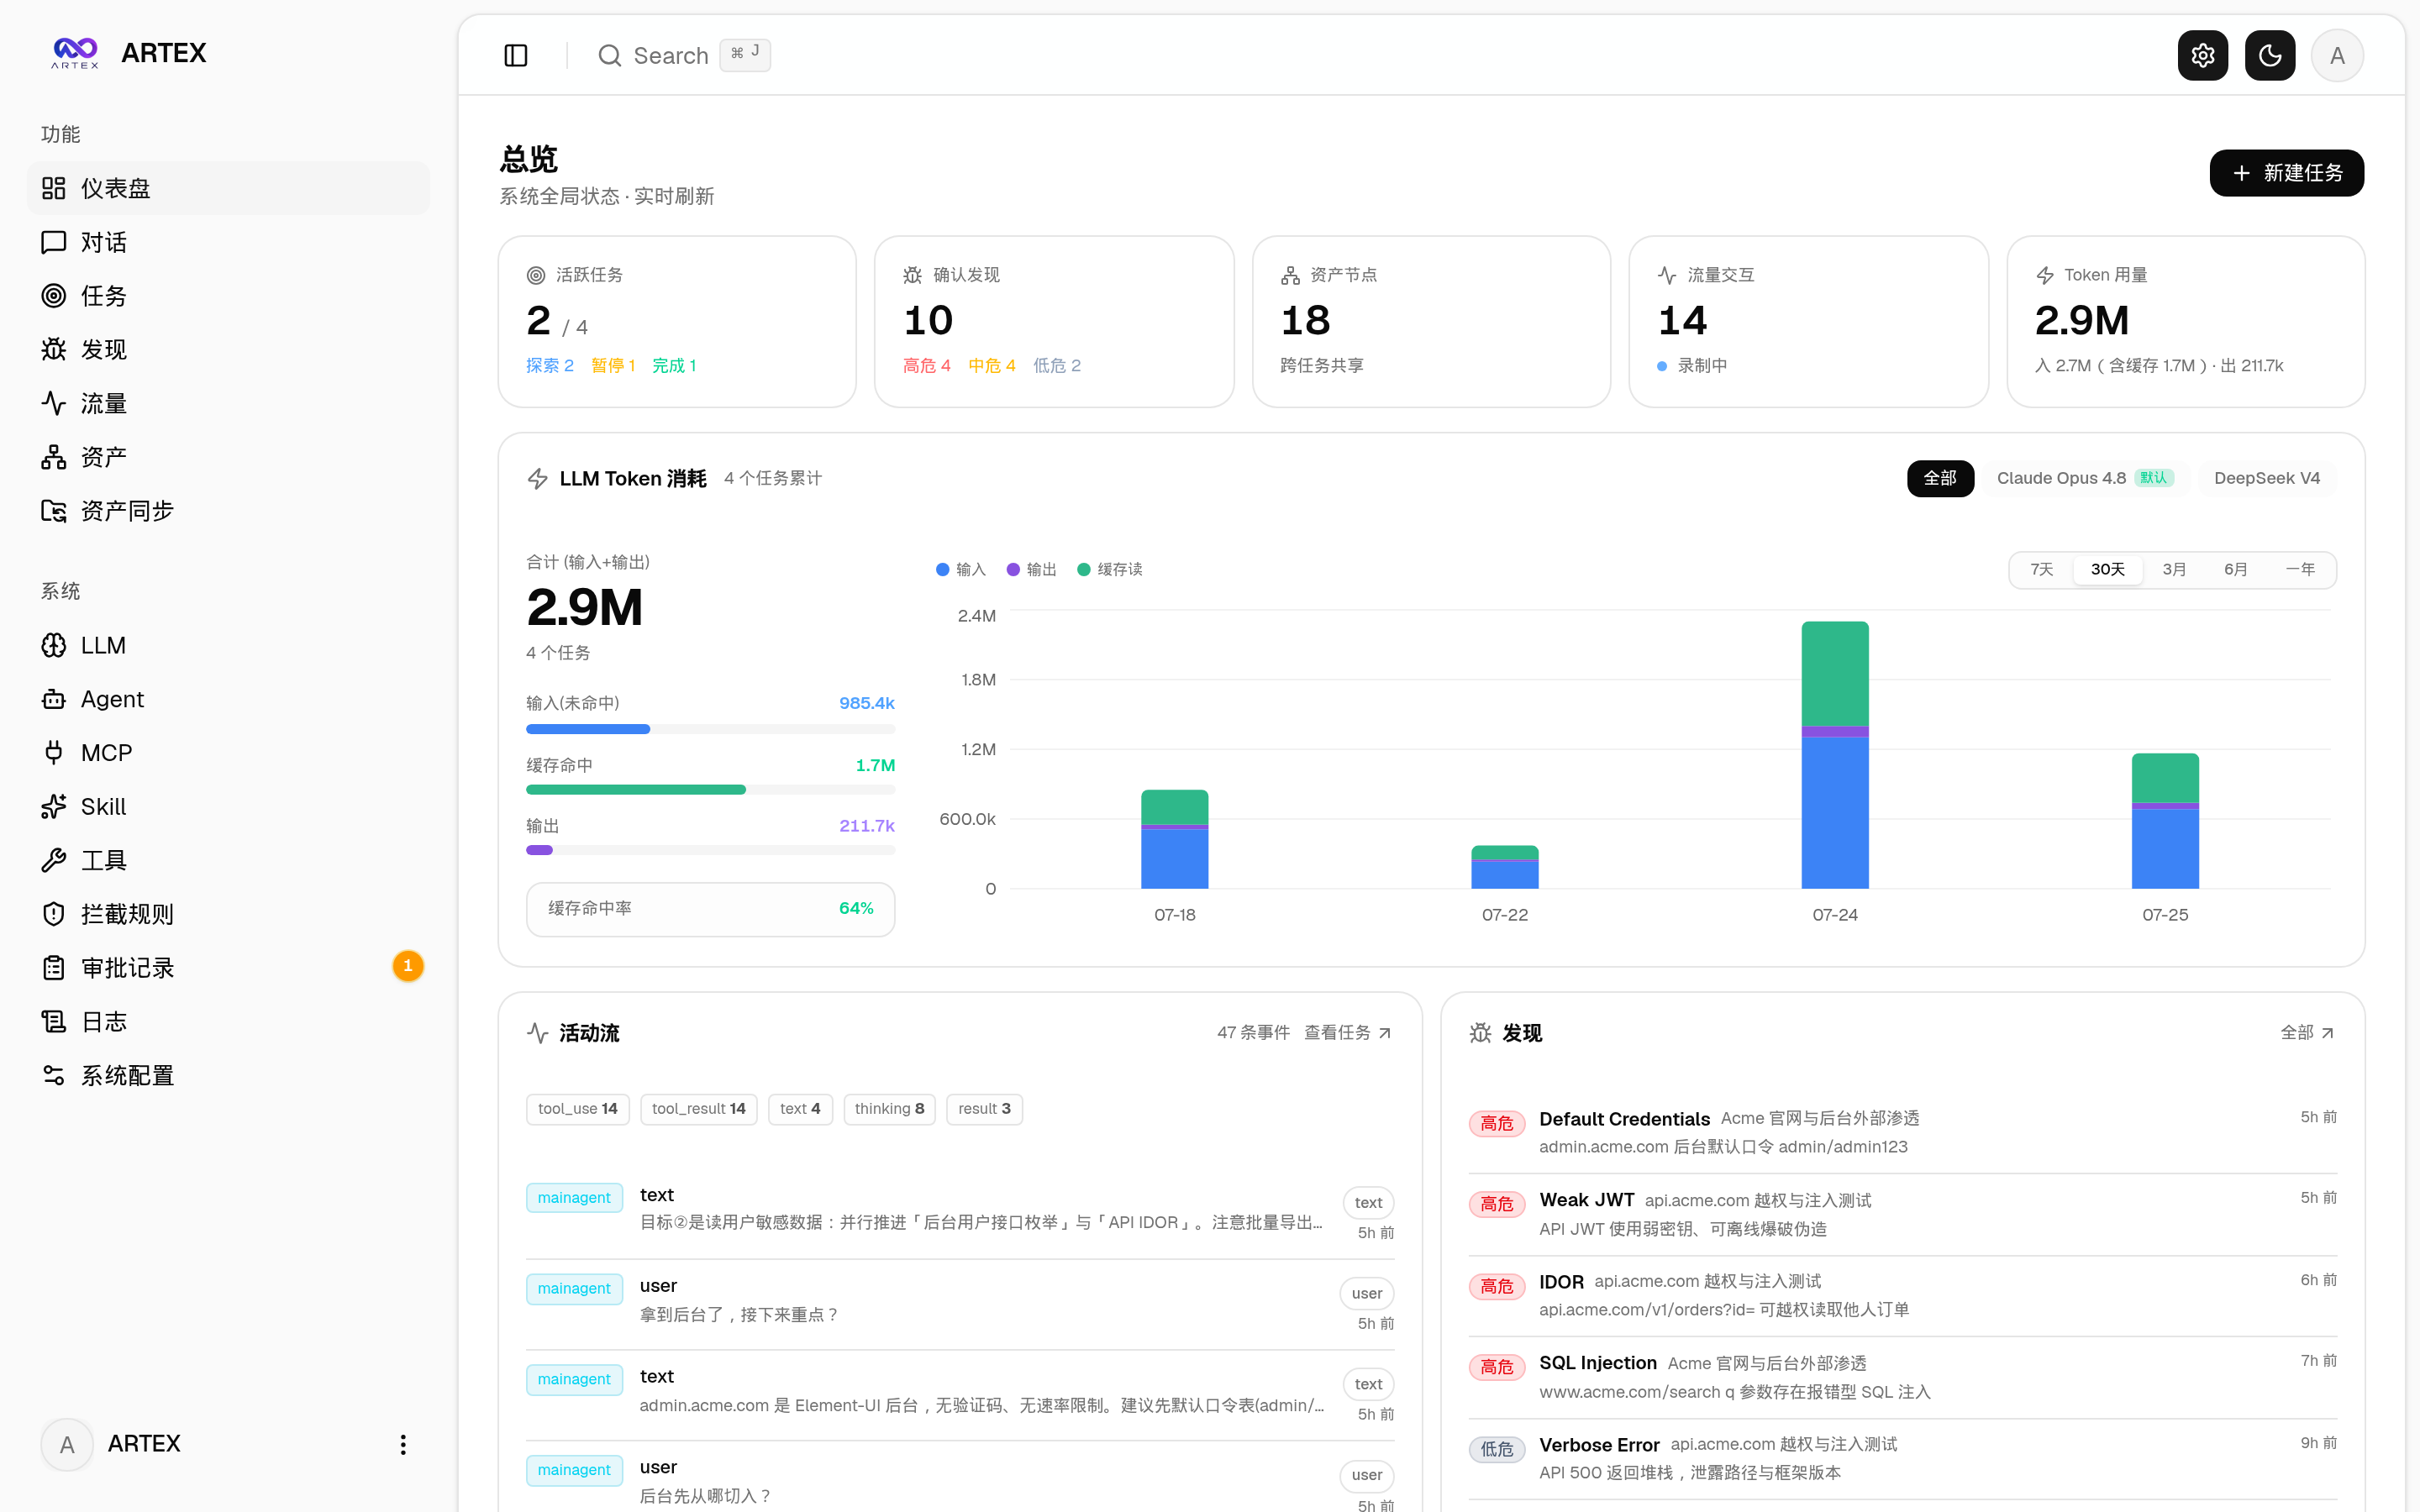
ARTEX is built around autonomous exploration, task orchestration, and process traceability. The system includes interfaces for the dashboard, task list, session execution, exploration chains, findings, assets, asset coverage maps, traffic records, human-in-the-loop conversations, agent management, and LLM configuration.
- Multi-agent exploration: Roles such as goals, planner, worker, and mainagent collaborate to advance tasks.
- Dual graph model: The asset graph stores asset facts shared across tasks, while the exploration graph records the goals, intents, facts, prompts, and findings of an individual task.
- Process-level information exchange: Workers can retrieve other workers' execution processes and reuse their observations.
- Human in the loop: Participate in tool calls and key operational decisions through conversations and intercepted approvals.
- Real-time activity stream: The backend pushes activity information through SSE, allowing task execution to be continuously observed in the interface.
- Traffic recording: The recording MITM proxy preserves traffic and evidence for tool execution.
- Asset synchronization: Domains, subdomains, IPs, ports, sites, endpoints, and other assets can be synchronized from ScopeSentry.
- Vulnerability retesting: Create a separate retest agent session for an existing vulnerability and save its conclusion, evidence, and session link.
Install ARTEX
Method 1: Use the One-Click Installation Script
This is the installation method recommended by the project. The script detects or installs Docker and offers two options: run everything in Docker or compile and run locally.
git clone https://github.com/Autumn-27/ARTEX.git
cd ARTEX
./install.sh
When choosing the all-Docker option, you need to enter a PostgreSQL password, or press Enter to let the script generate a random password. The script then writes the .env file and runs docker compose up -d.
When choosing local execution, you can connect to an existing database or let Docker start one. The script generates config.json, compiles a single binary with the frontend, and starts the service.
After installation, visit http://localhost:8787. On the first visit, go to /setup to set the administrator password.
Method 2: Use Docker Compose Manually
git clone https://github.com/Autumn-27/ARTEX.git
cd ARTEX
cp .env.example .env
docker compose up -d
Edit .env and fill in at least POSTGRES_PASSWORD. To configure Anthropic through environment variables, you can also fill in ANTHROPIC_API_KEY. The container image includes commonly used tools, and ./skills and ./data are preserved through bind mounts.
After startup, visit http://localhost:8787. If remote MCP is required, select http or sse in system settings. Older SSE versions typically use /sse to establish the event stream and receive JSON-RPC requests through the returned /message?sessionId=...; configure the authentication header as Authorization=Bearer <token>.
Method 3: Use a Precompiled Binary
Download the archive for your platform from Releases. After extraction, it typically contains artex, start.sh or, on Windows, start.bat, skills/, and config.example.json.
cp config.example.json config.json
./start.sh
Use start.sh or start.bat to start the service; do not run ./artex directly. The startup script handles process supervision and supports restarting after a one-click update from the page. To run it in the background, use:
nohup ./start.sh >artex.log 2>&1 &Method 4: Build from Source
To build a single binary with the frontend embedded, first generate the Next.js static files and then copy them to the backend's embedded directory.
cd web && npm ci && npm run build:static && cd ..
cp -r web/out server/webui/dist
CGO_ENABLED=0 go build -tags embedui -o artex ./cmd/artex
./start.sh
Complete the Basic Configuration
Configure PostgreSQL
ARTEX requires PostgreSQL. When running locally, you can enter the database connection details in config.json, or override the configuration with ARTEX_PG_DSN.
{
  "database": {
    "host": "127.0.0.1",
    "port": 5432,
    "user": "artex",
    "password": "yourpass",
    "dbname": "artex",
    "sslmode": "disable"
  }
}
Each time the service starts, it idempotently initializes and migrates the database schema, including required field and index changes. You should still back up the database and the ./data directory before upgrading.
Configure the LLM
Exploration features require an LLM. You can use an Anthropic or OpenAI API key, or enter one on the interface's “LLM Configuration” page.
export ANTHROPIC_API_KEY=sk-...You can also set OPENAI_API_KEY. The project also supports ARTEX_LLM_PROVIDER, ARTEX_LLM_MODEL, ARTEX_LLM_BASE_URL, and ARTEX_LLM_PROXY to adjust the provider, model, endpoint, and proxy.
Adjust Concurrency and Ports
The number of work agents for each task can be adjusted in “System Settings”; the default is 3. Startup parameters support configuring the Web/API address and traffic recording proxy port:
./start.sh -addr :8787 -proxy :8788The startup script passes the parameters unchanged to artex.
Start Using the Web Interface
1. Sign In and View the Dashboard
On your first visit, set the administrator password, then open the dashboard to view the overview, token usage, and activity stream. The dashboard is useful for quickly determining whether the system is running normally and whether tasks have generated new activity.
2. View Tasks and Execution Processes
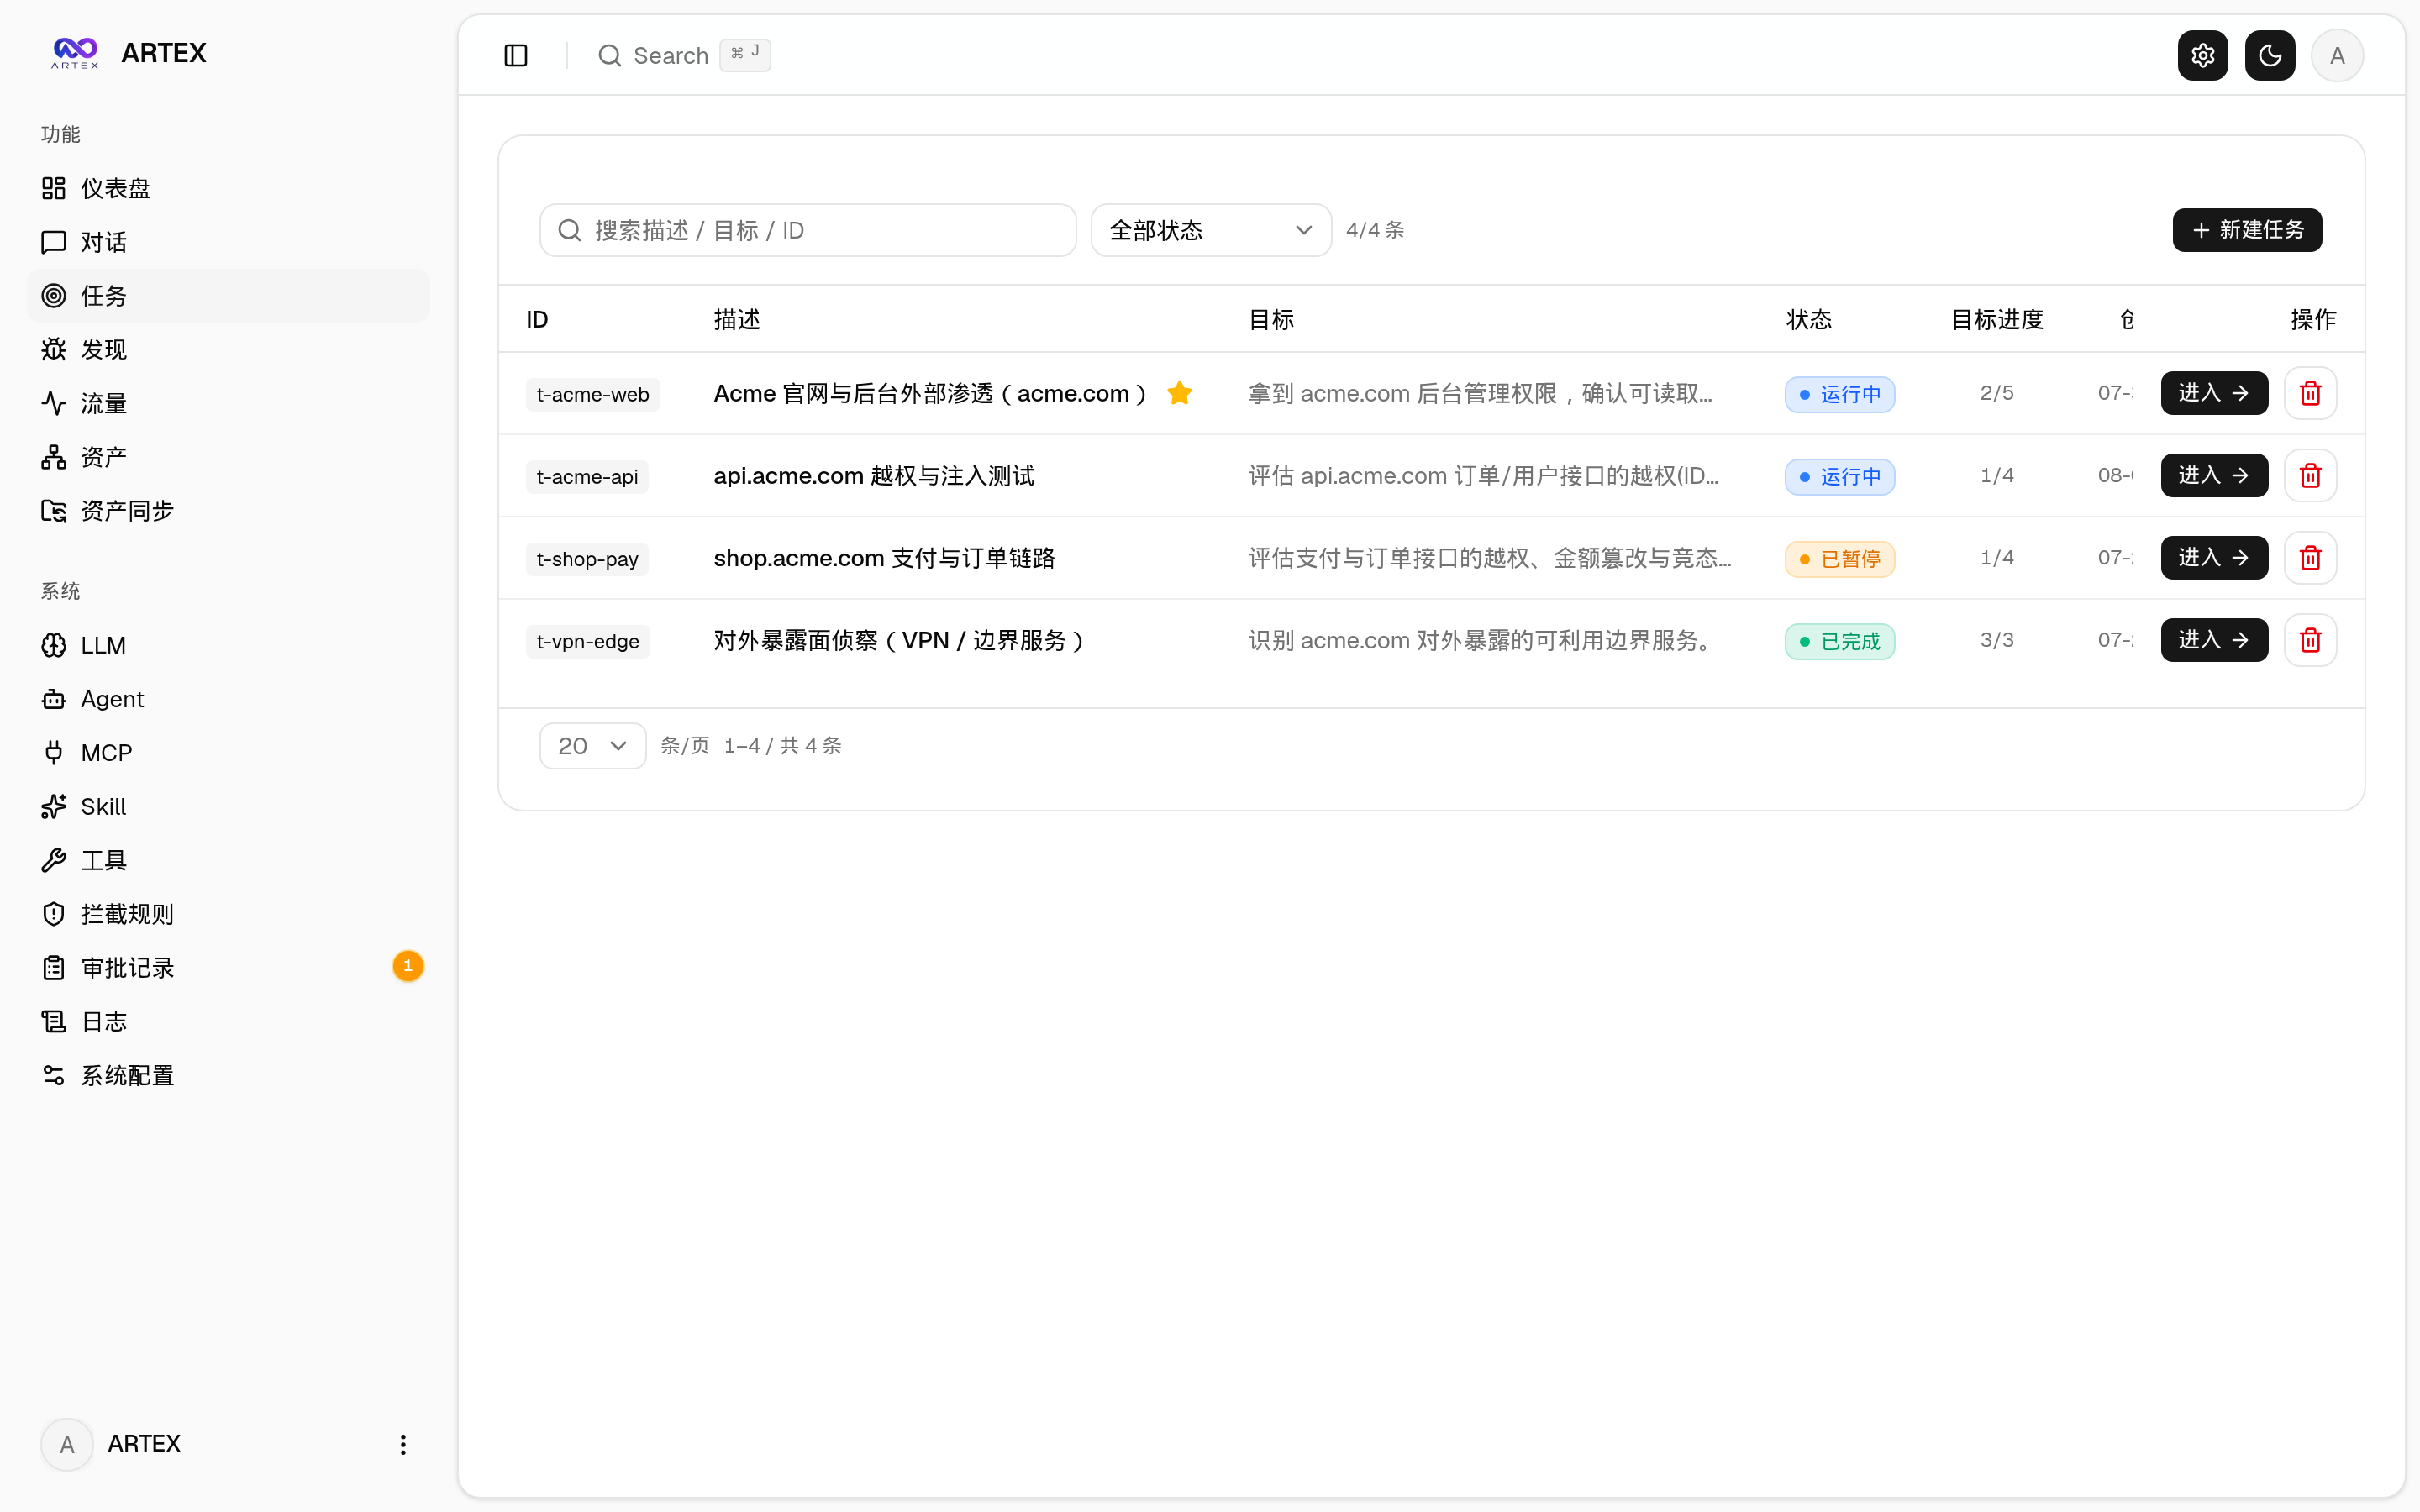
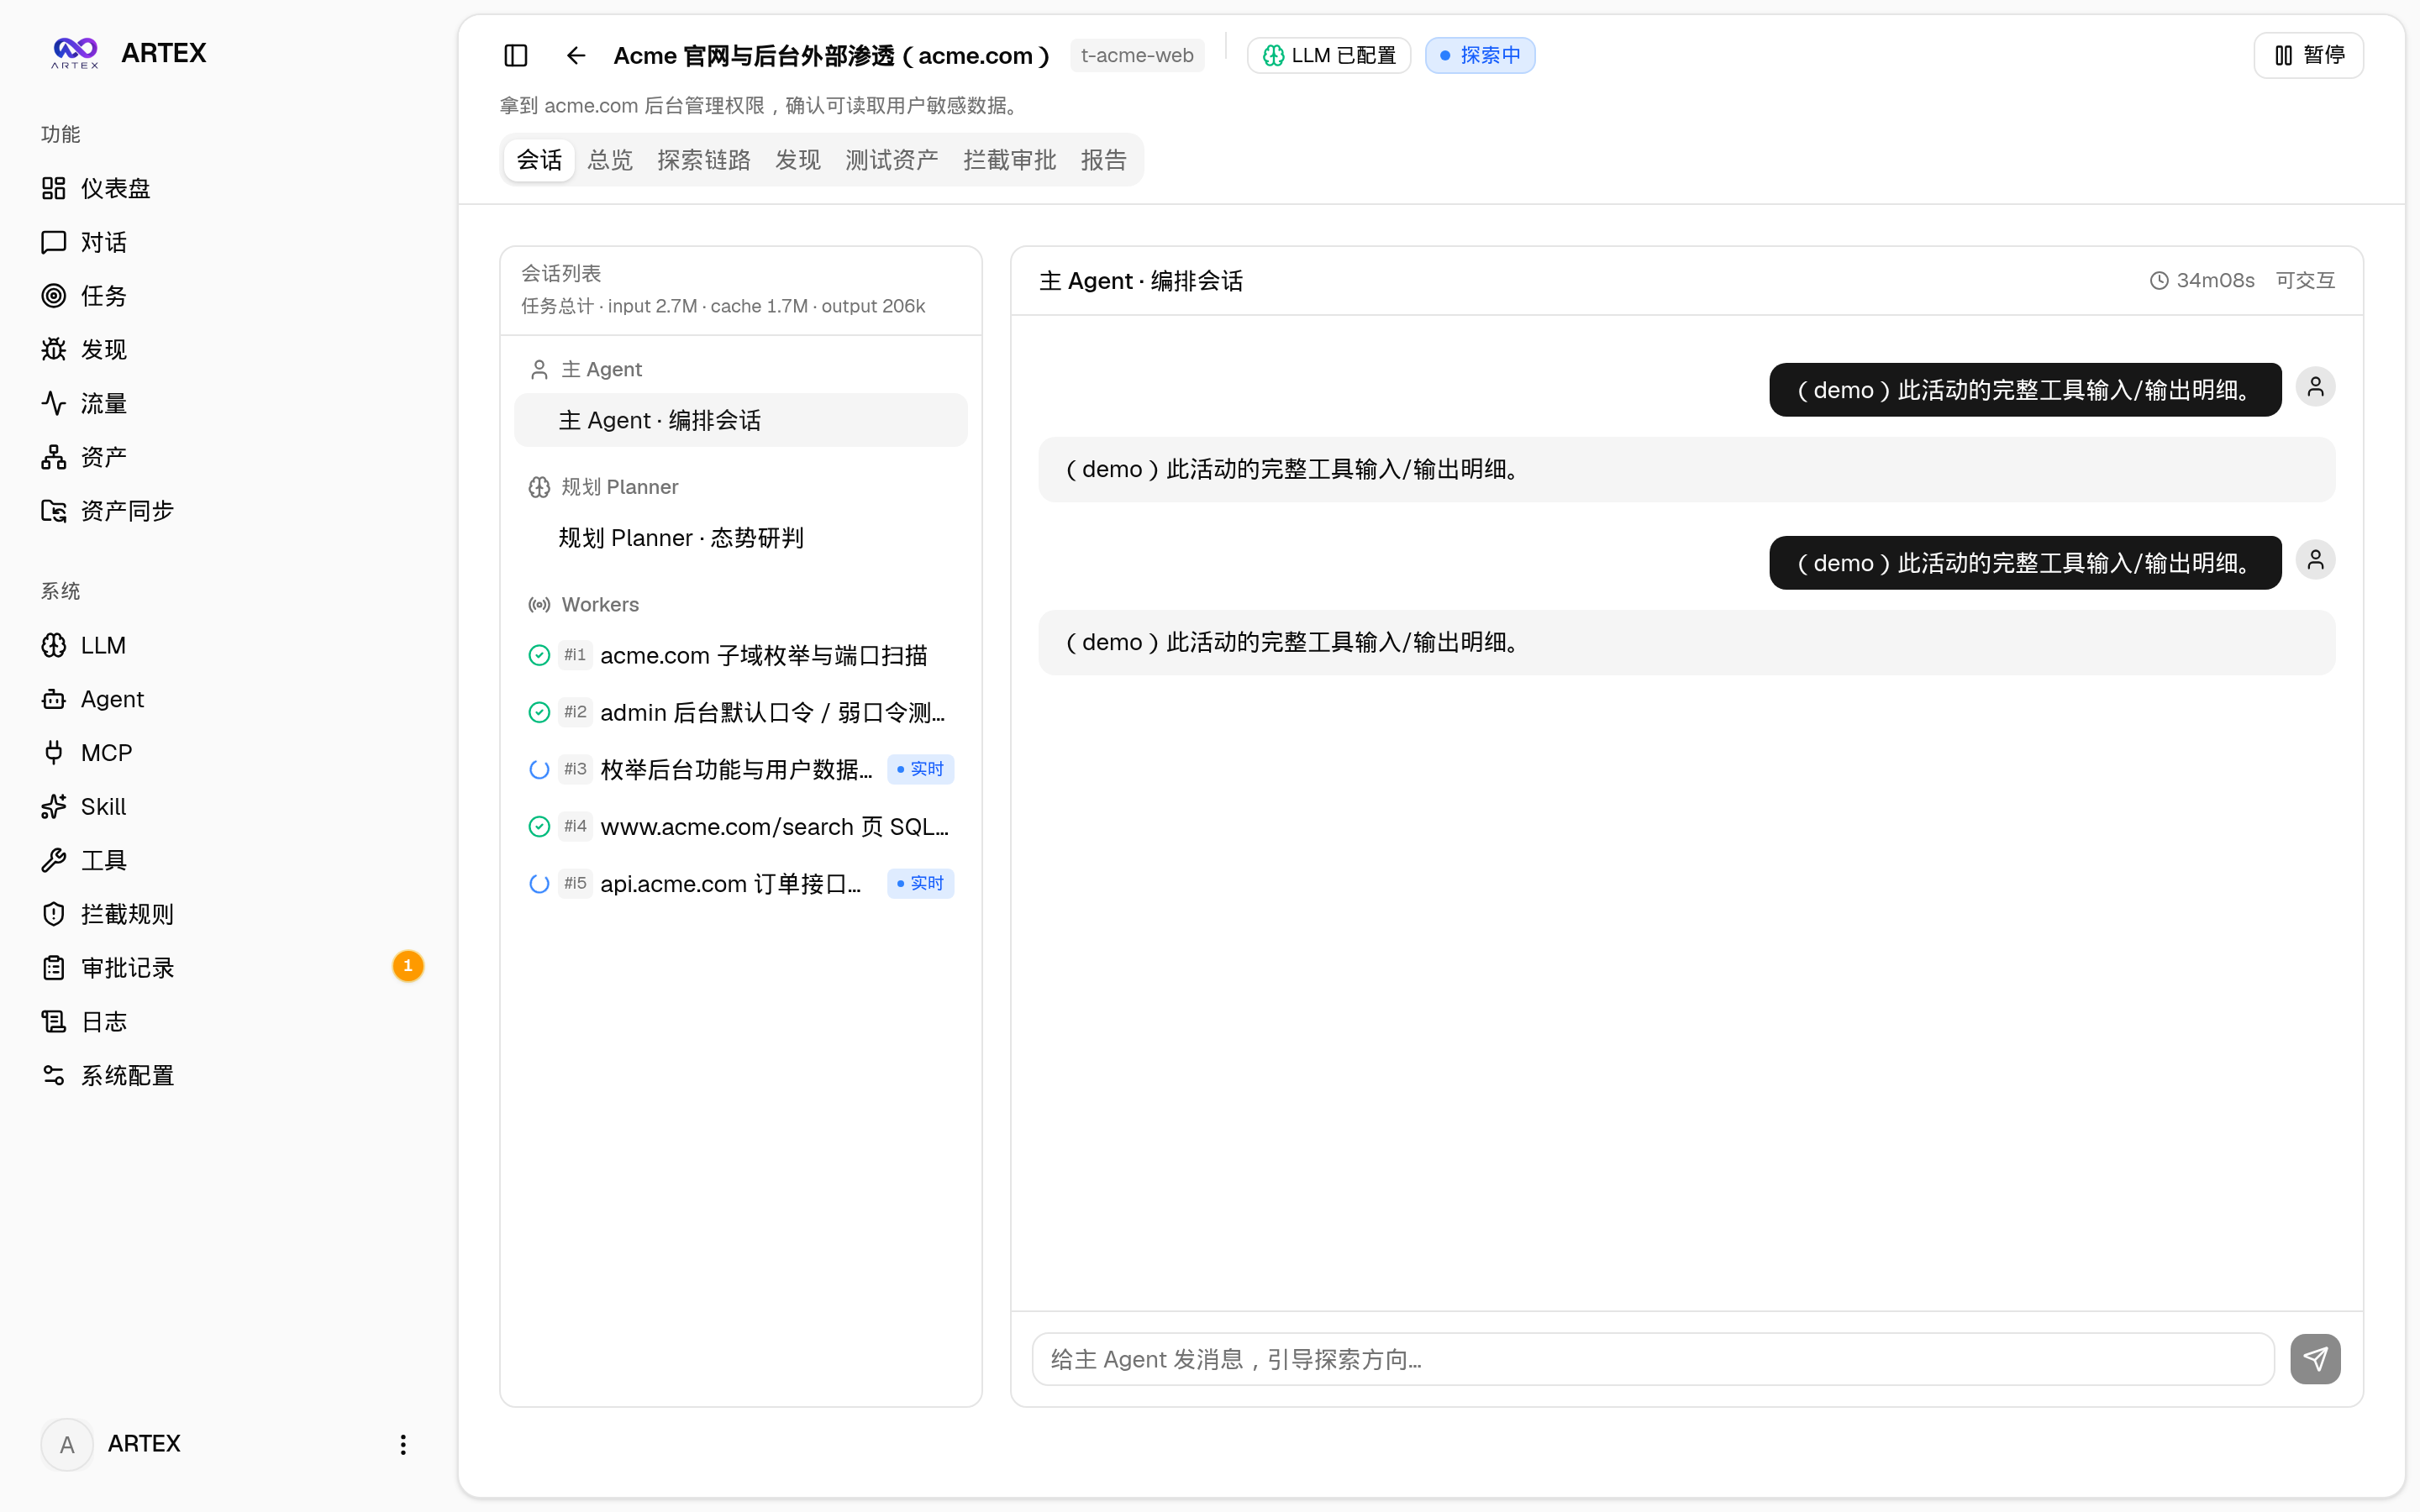
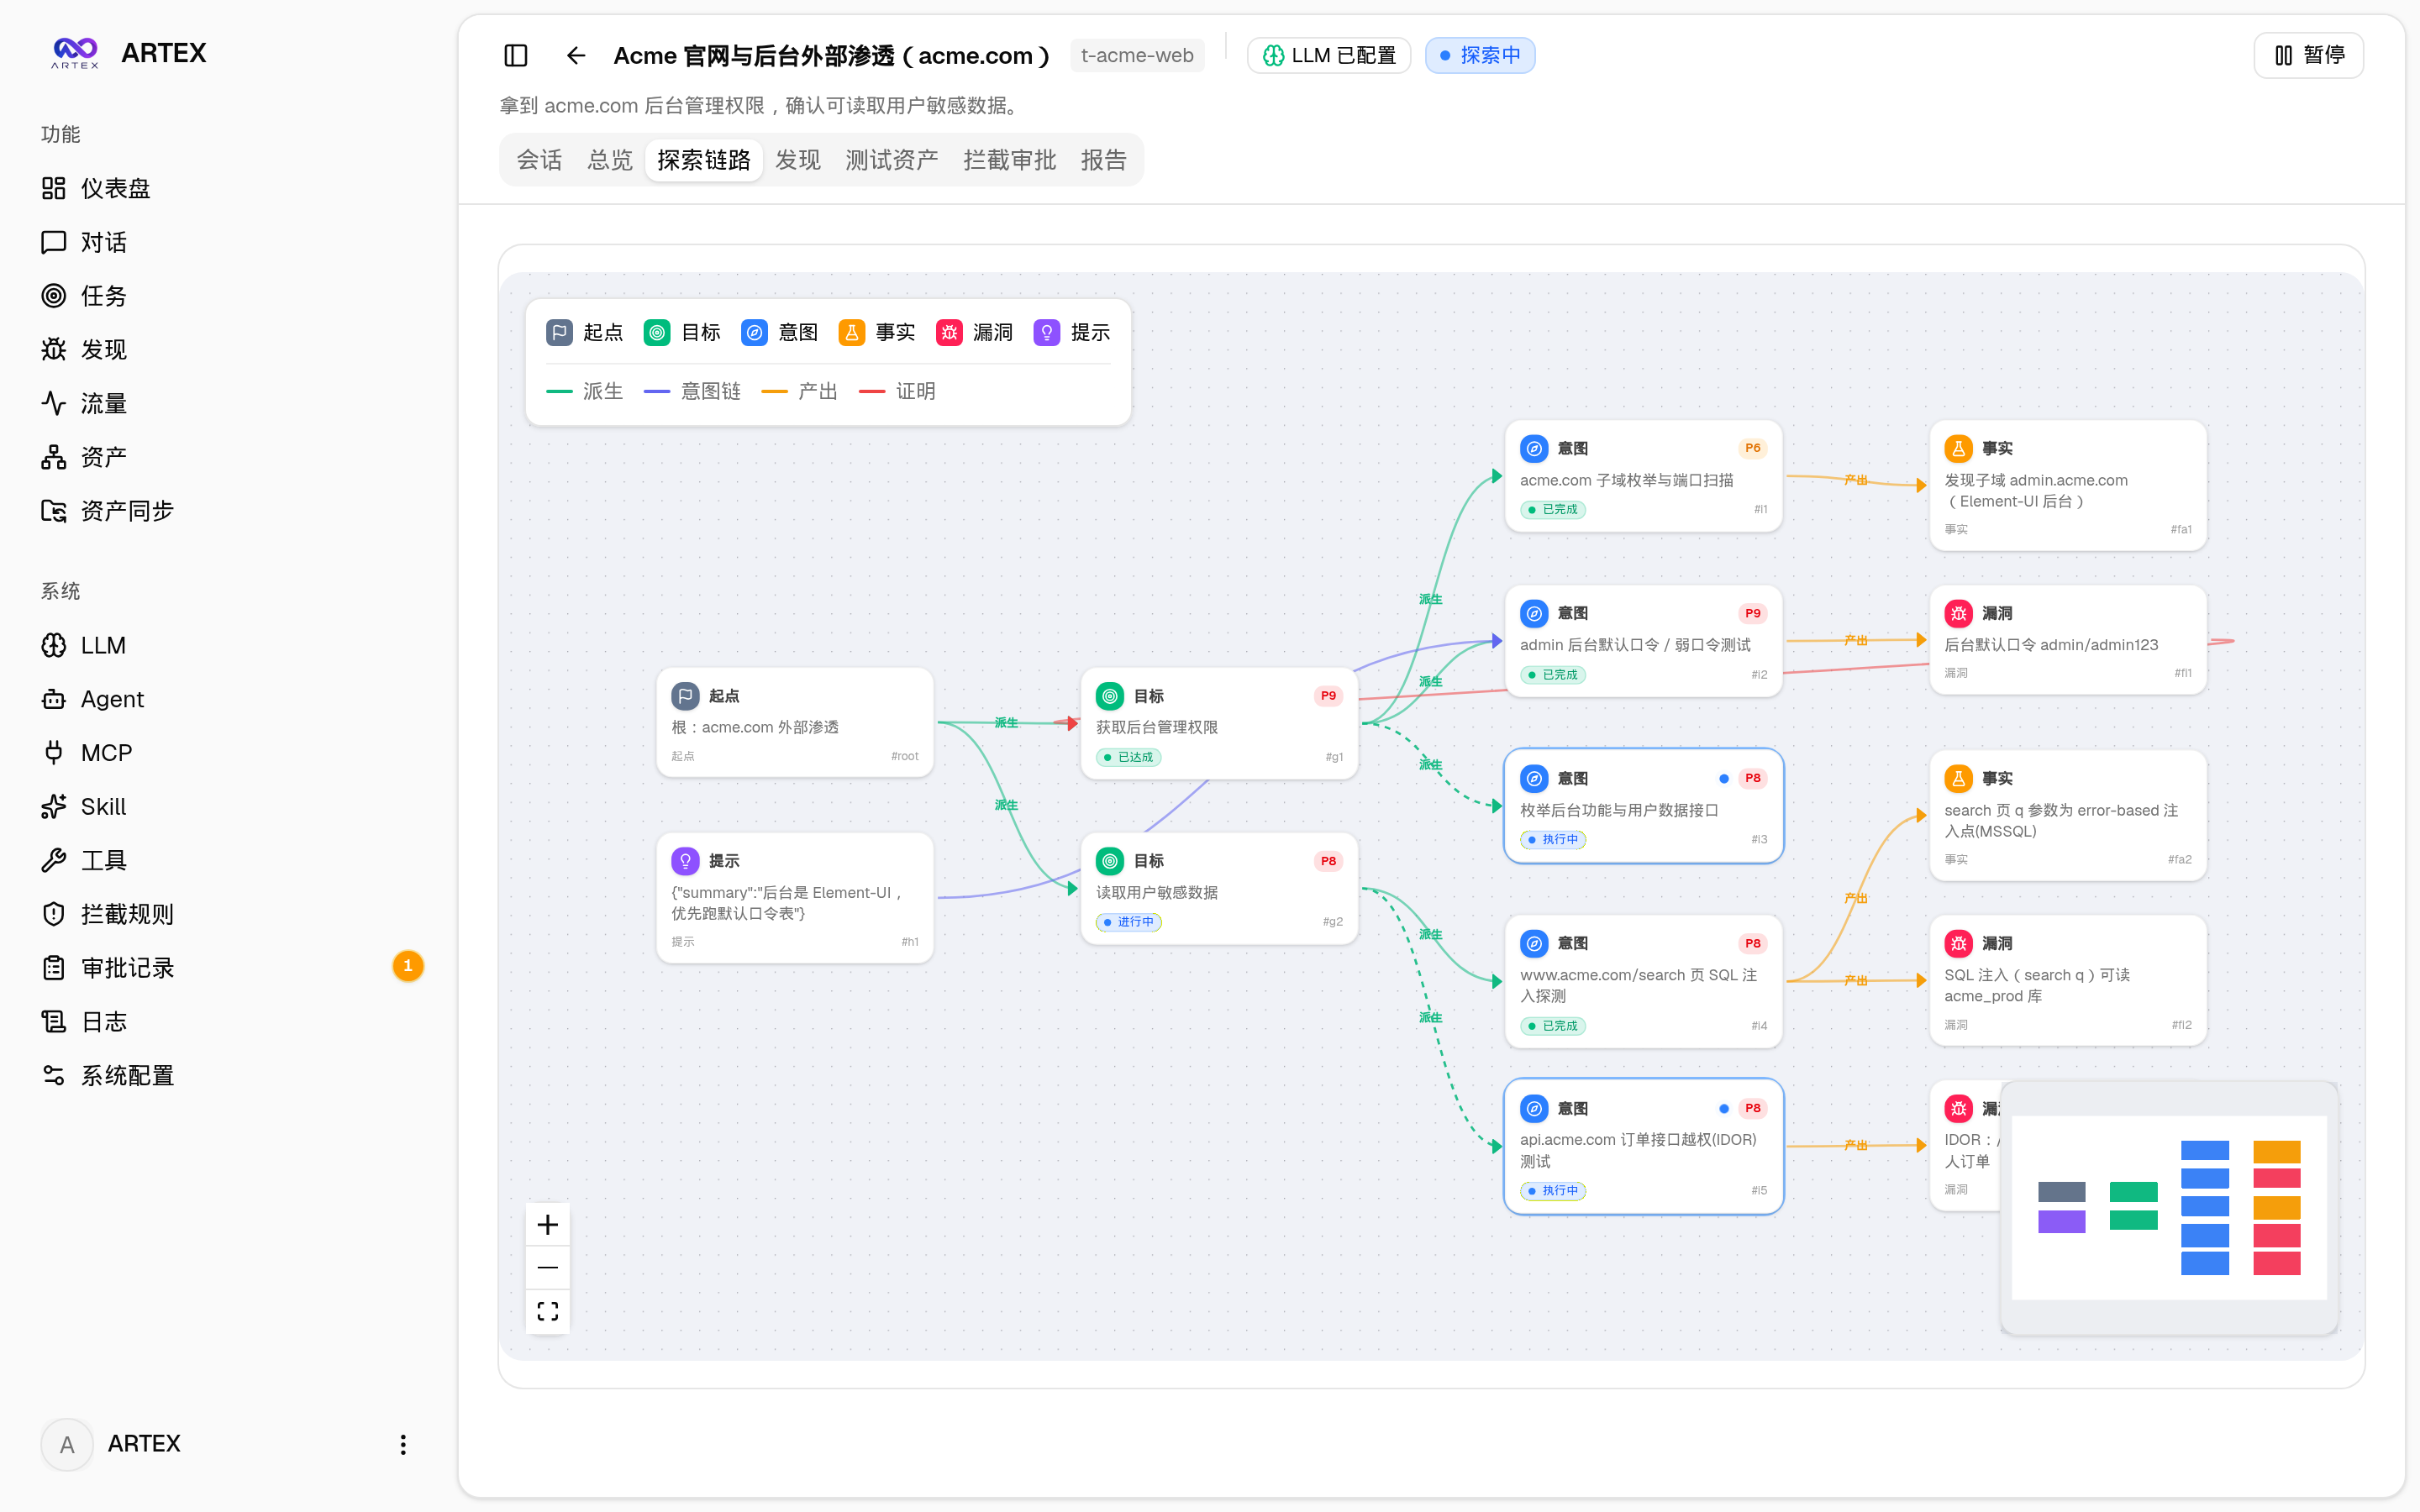
Select a target task from the task list to view its sessions, tool calls, activity records, and exploration chain. The execution process page displays the agent's work steps, while the exploration chain helps explain the relationships among goals, intents, facts, and findings.
When using these pages, prioritize validating workflows in a local isolated environment, and use activity records and traffic records to check which steps the agent actually performed.
3. View Findings and Assets
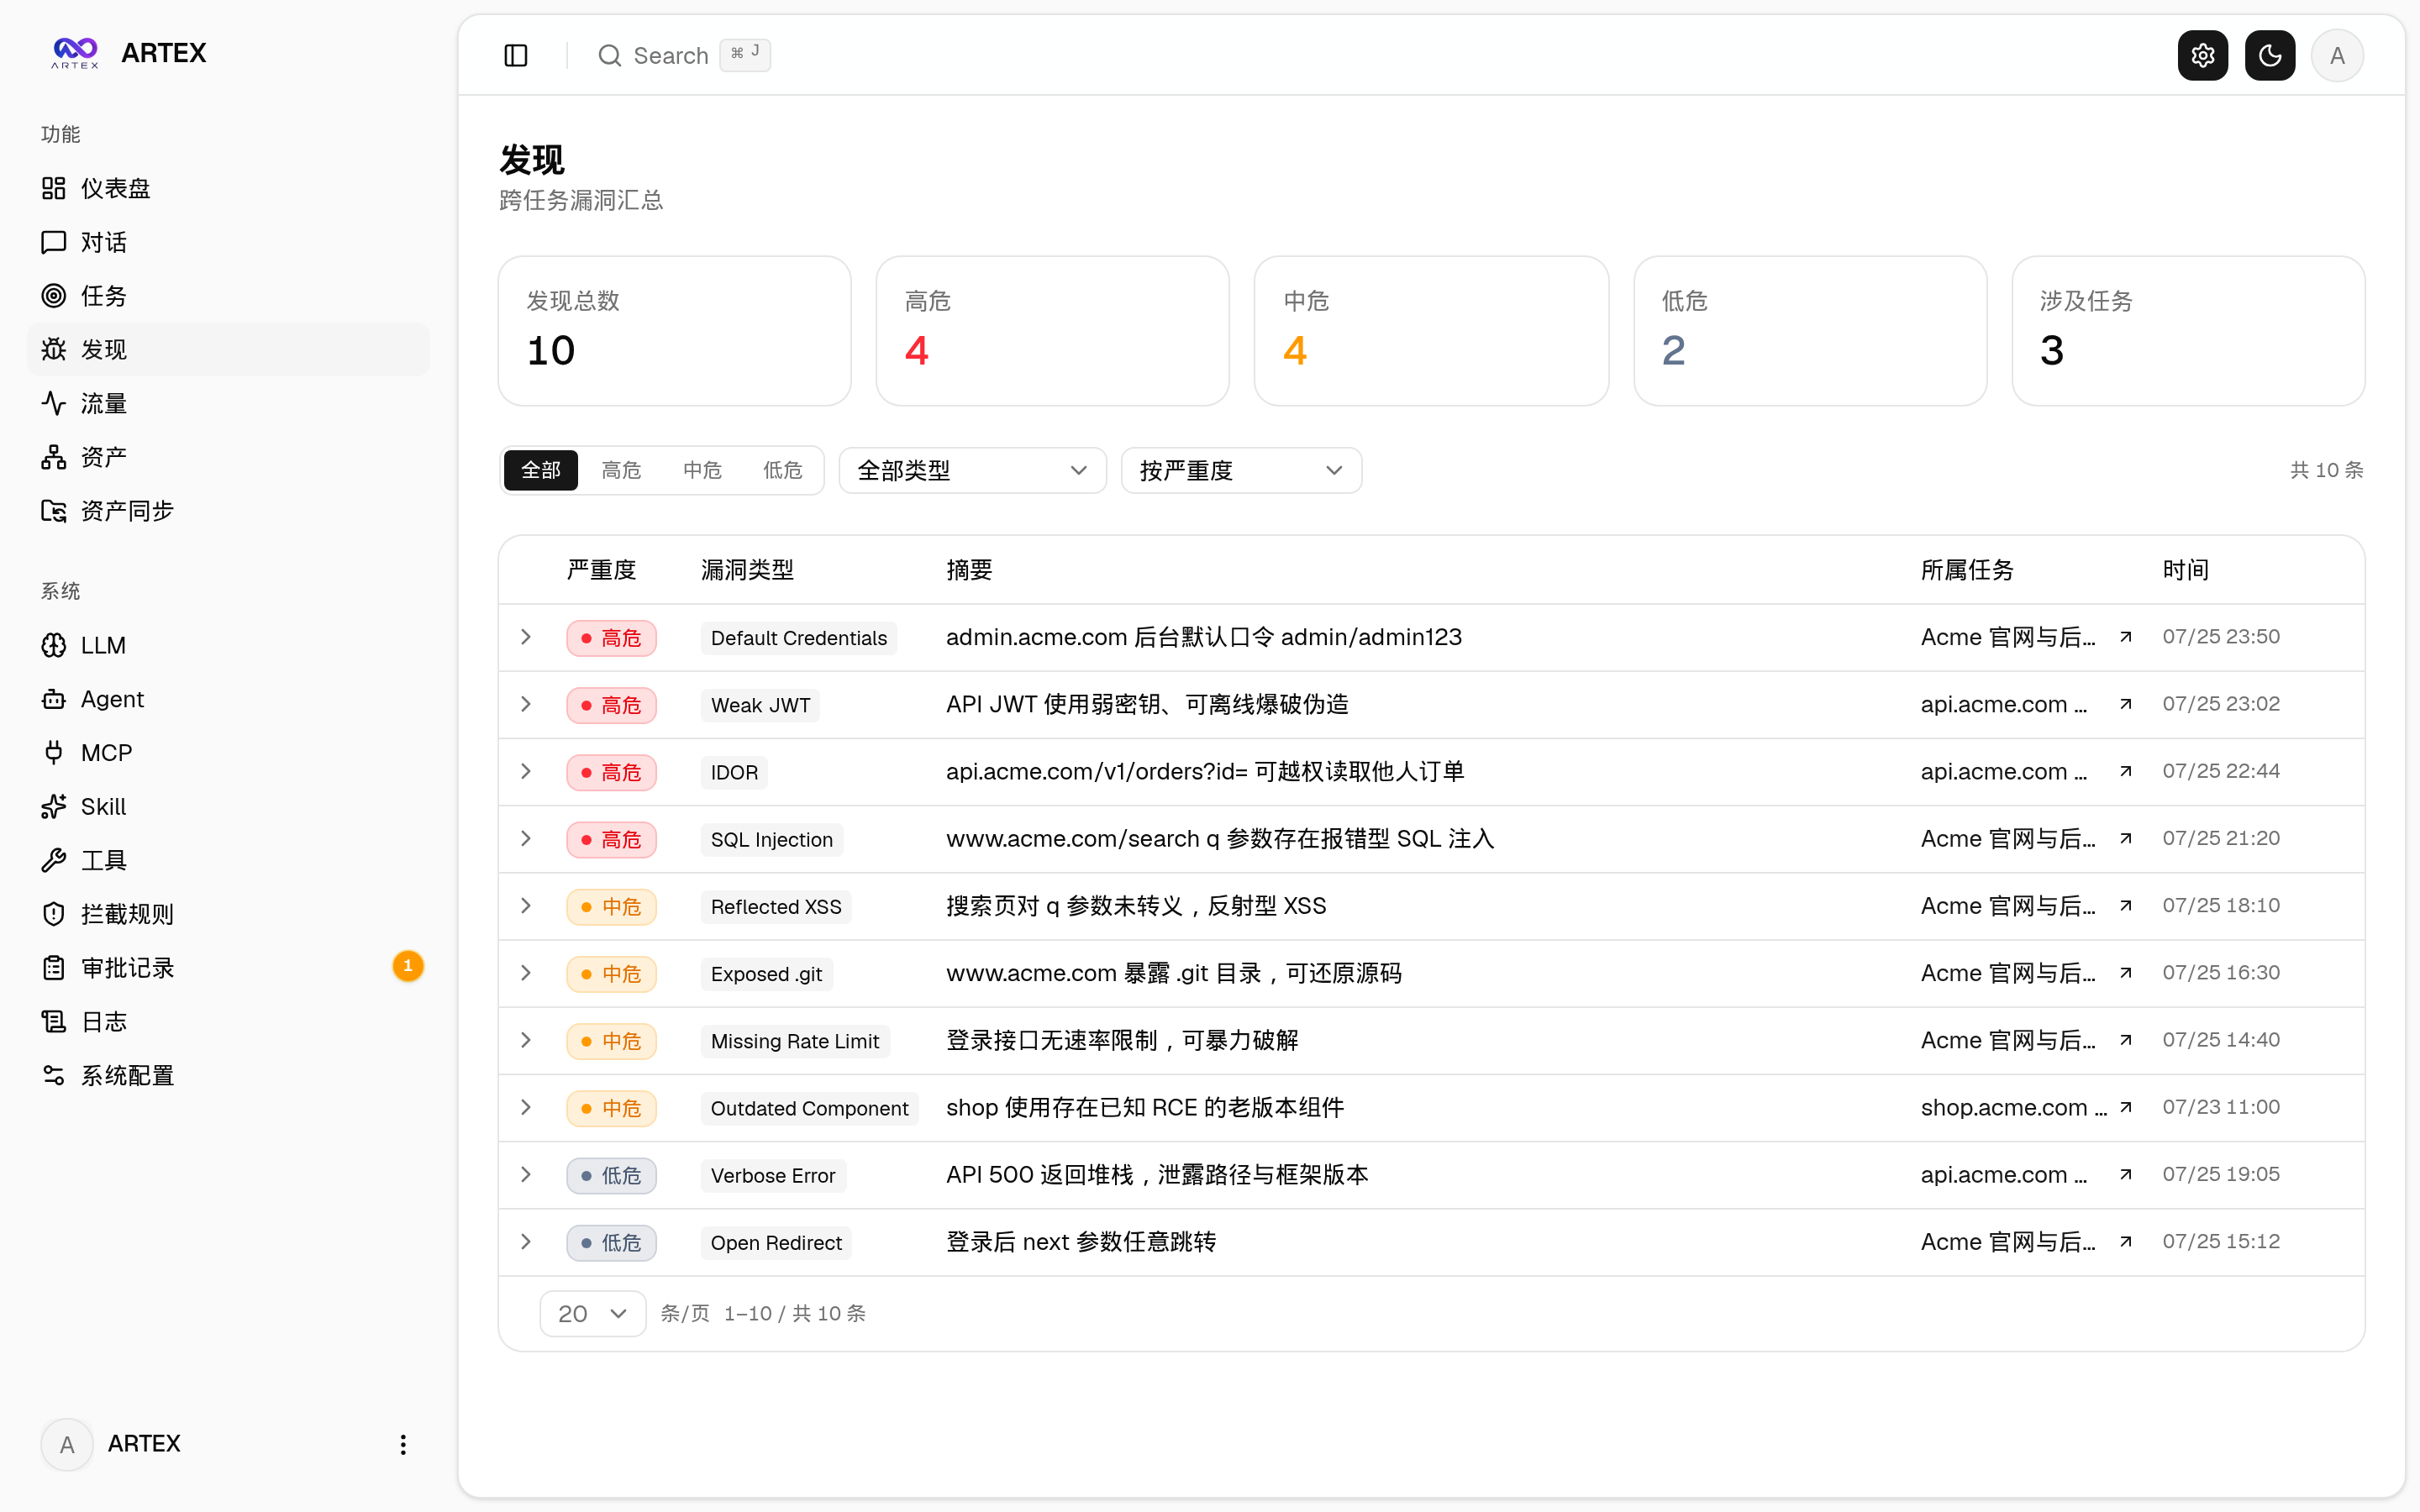
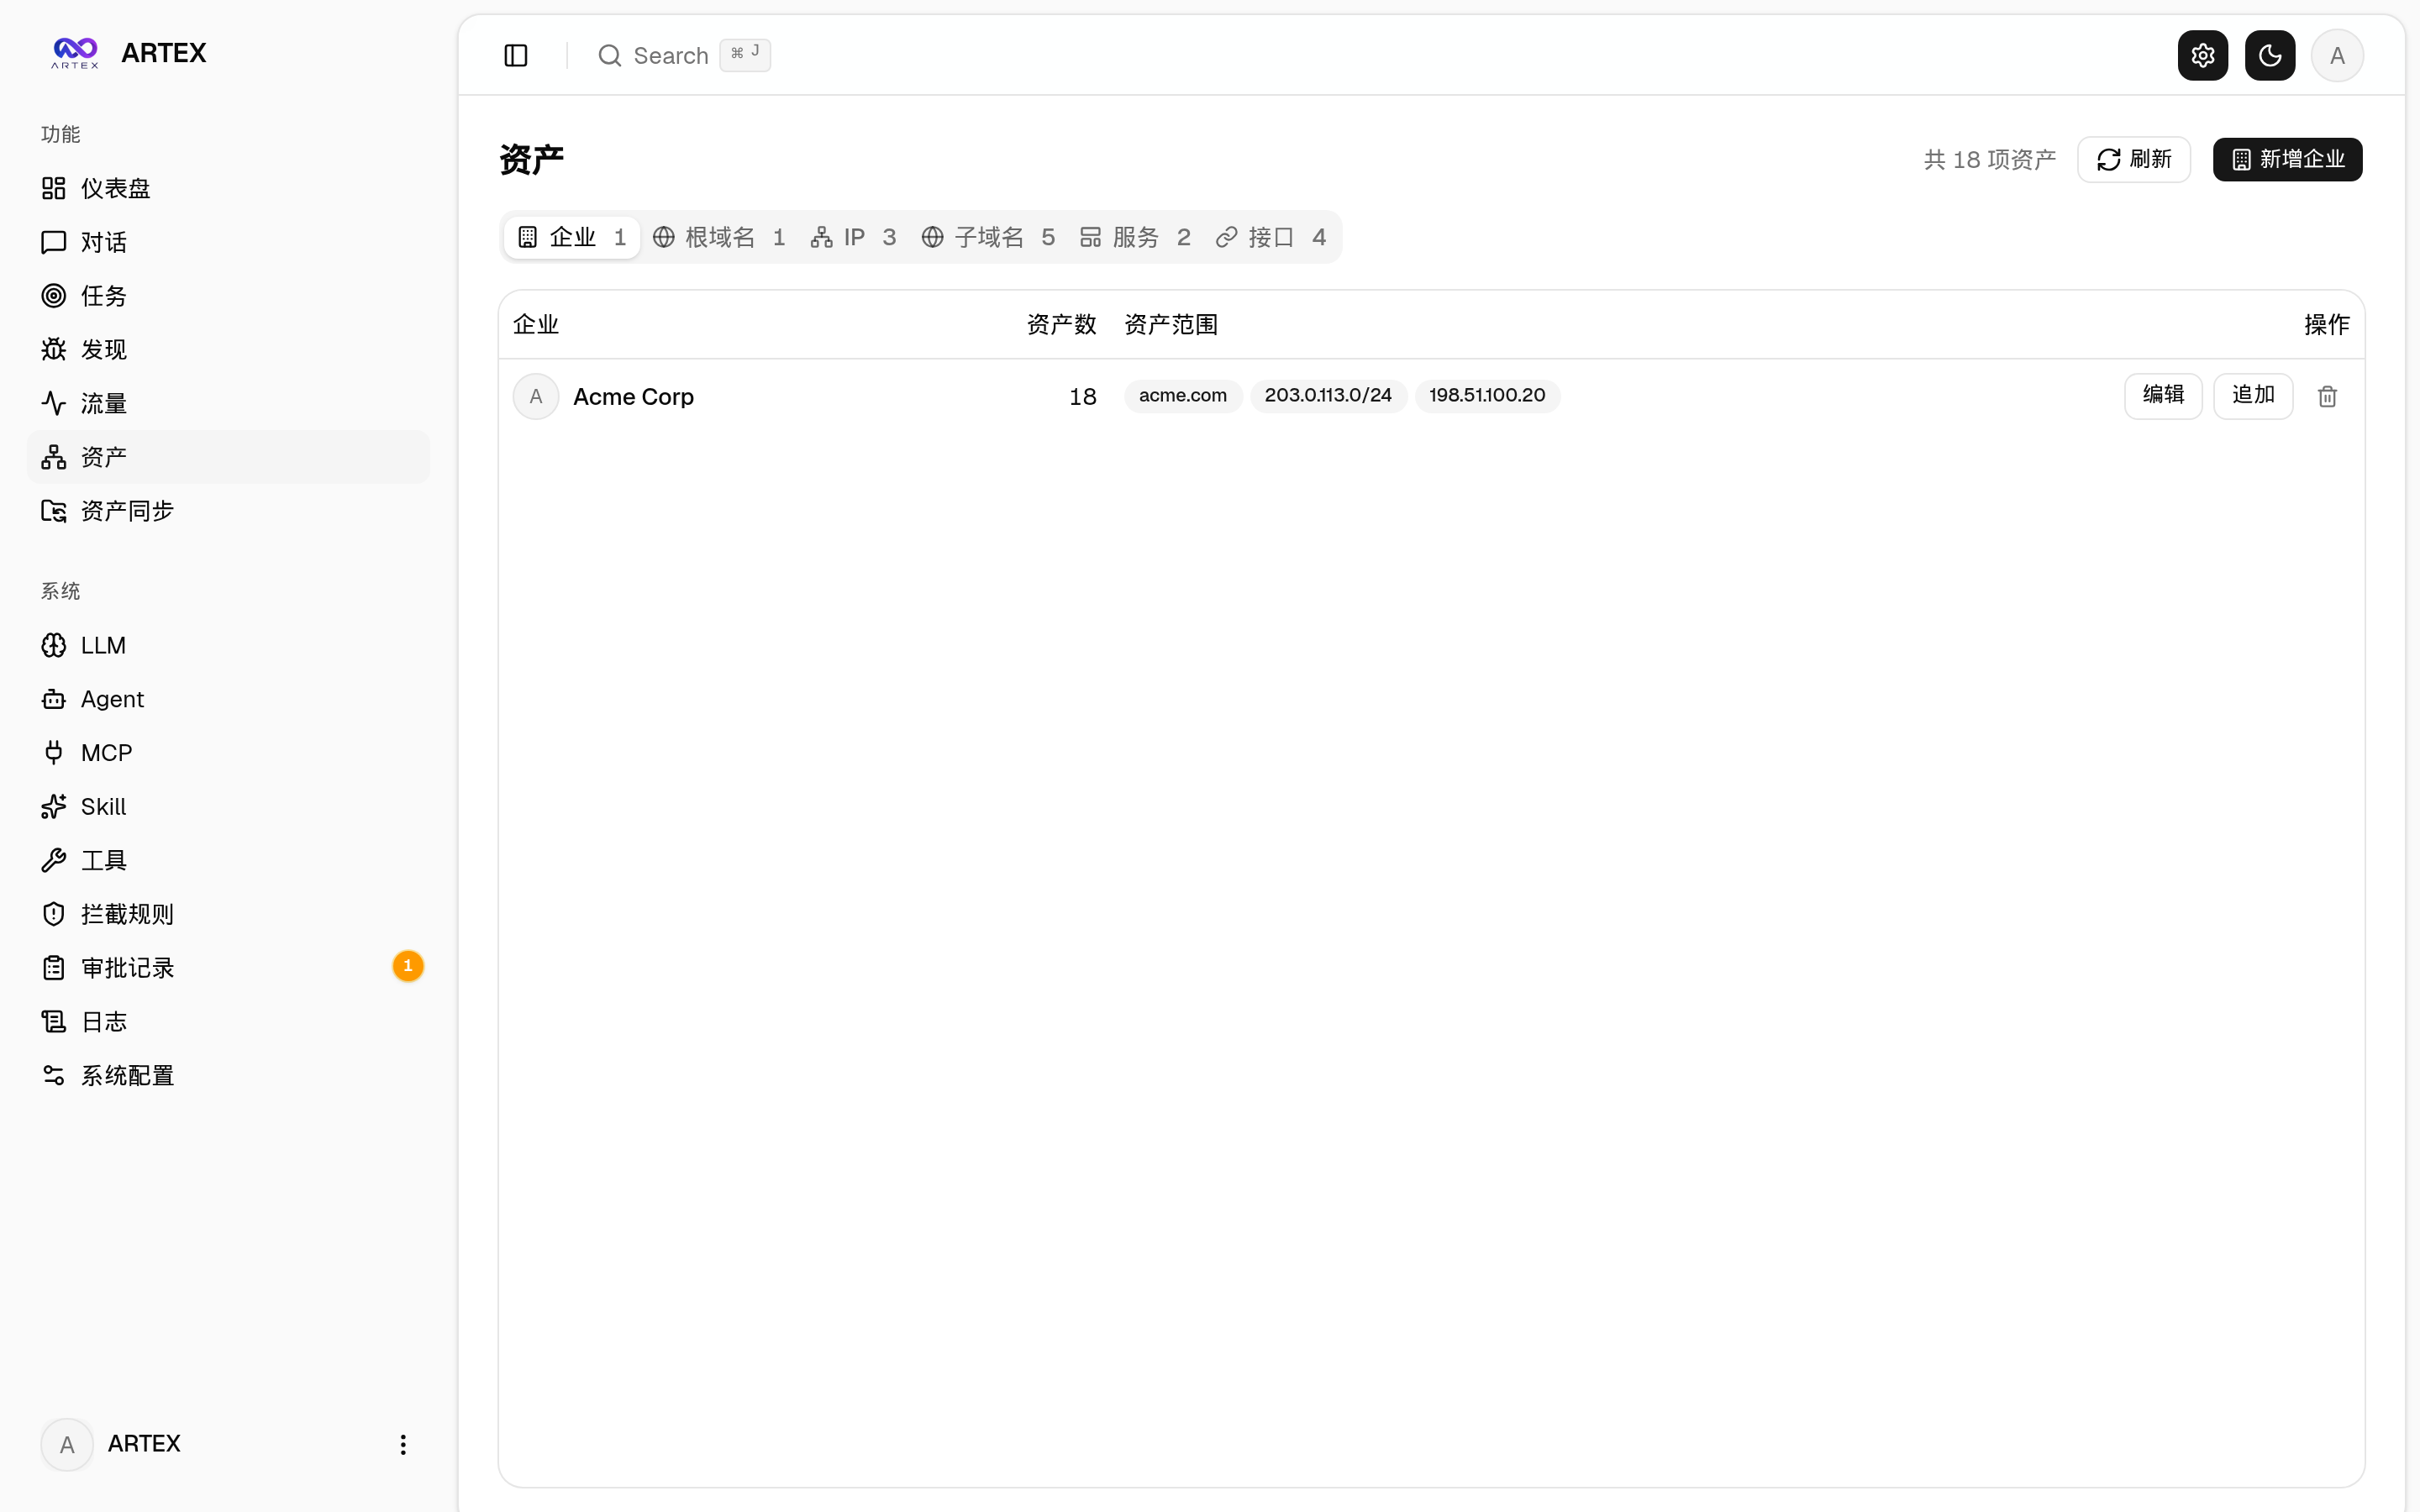
The findings page consolidates vulnerabilities and other findings produced by tasks. The assets page displays the asset information collected and consolidated by the system.
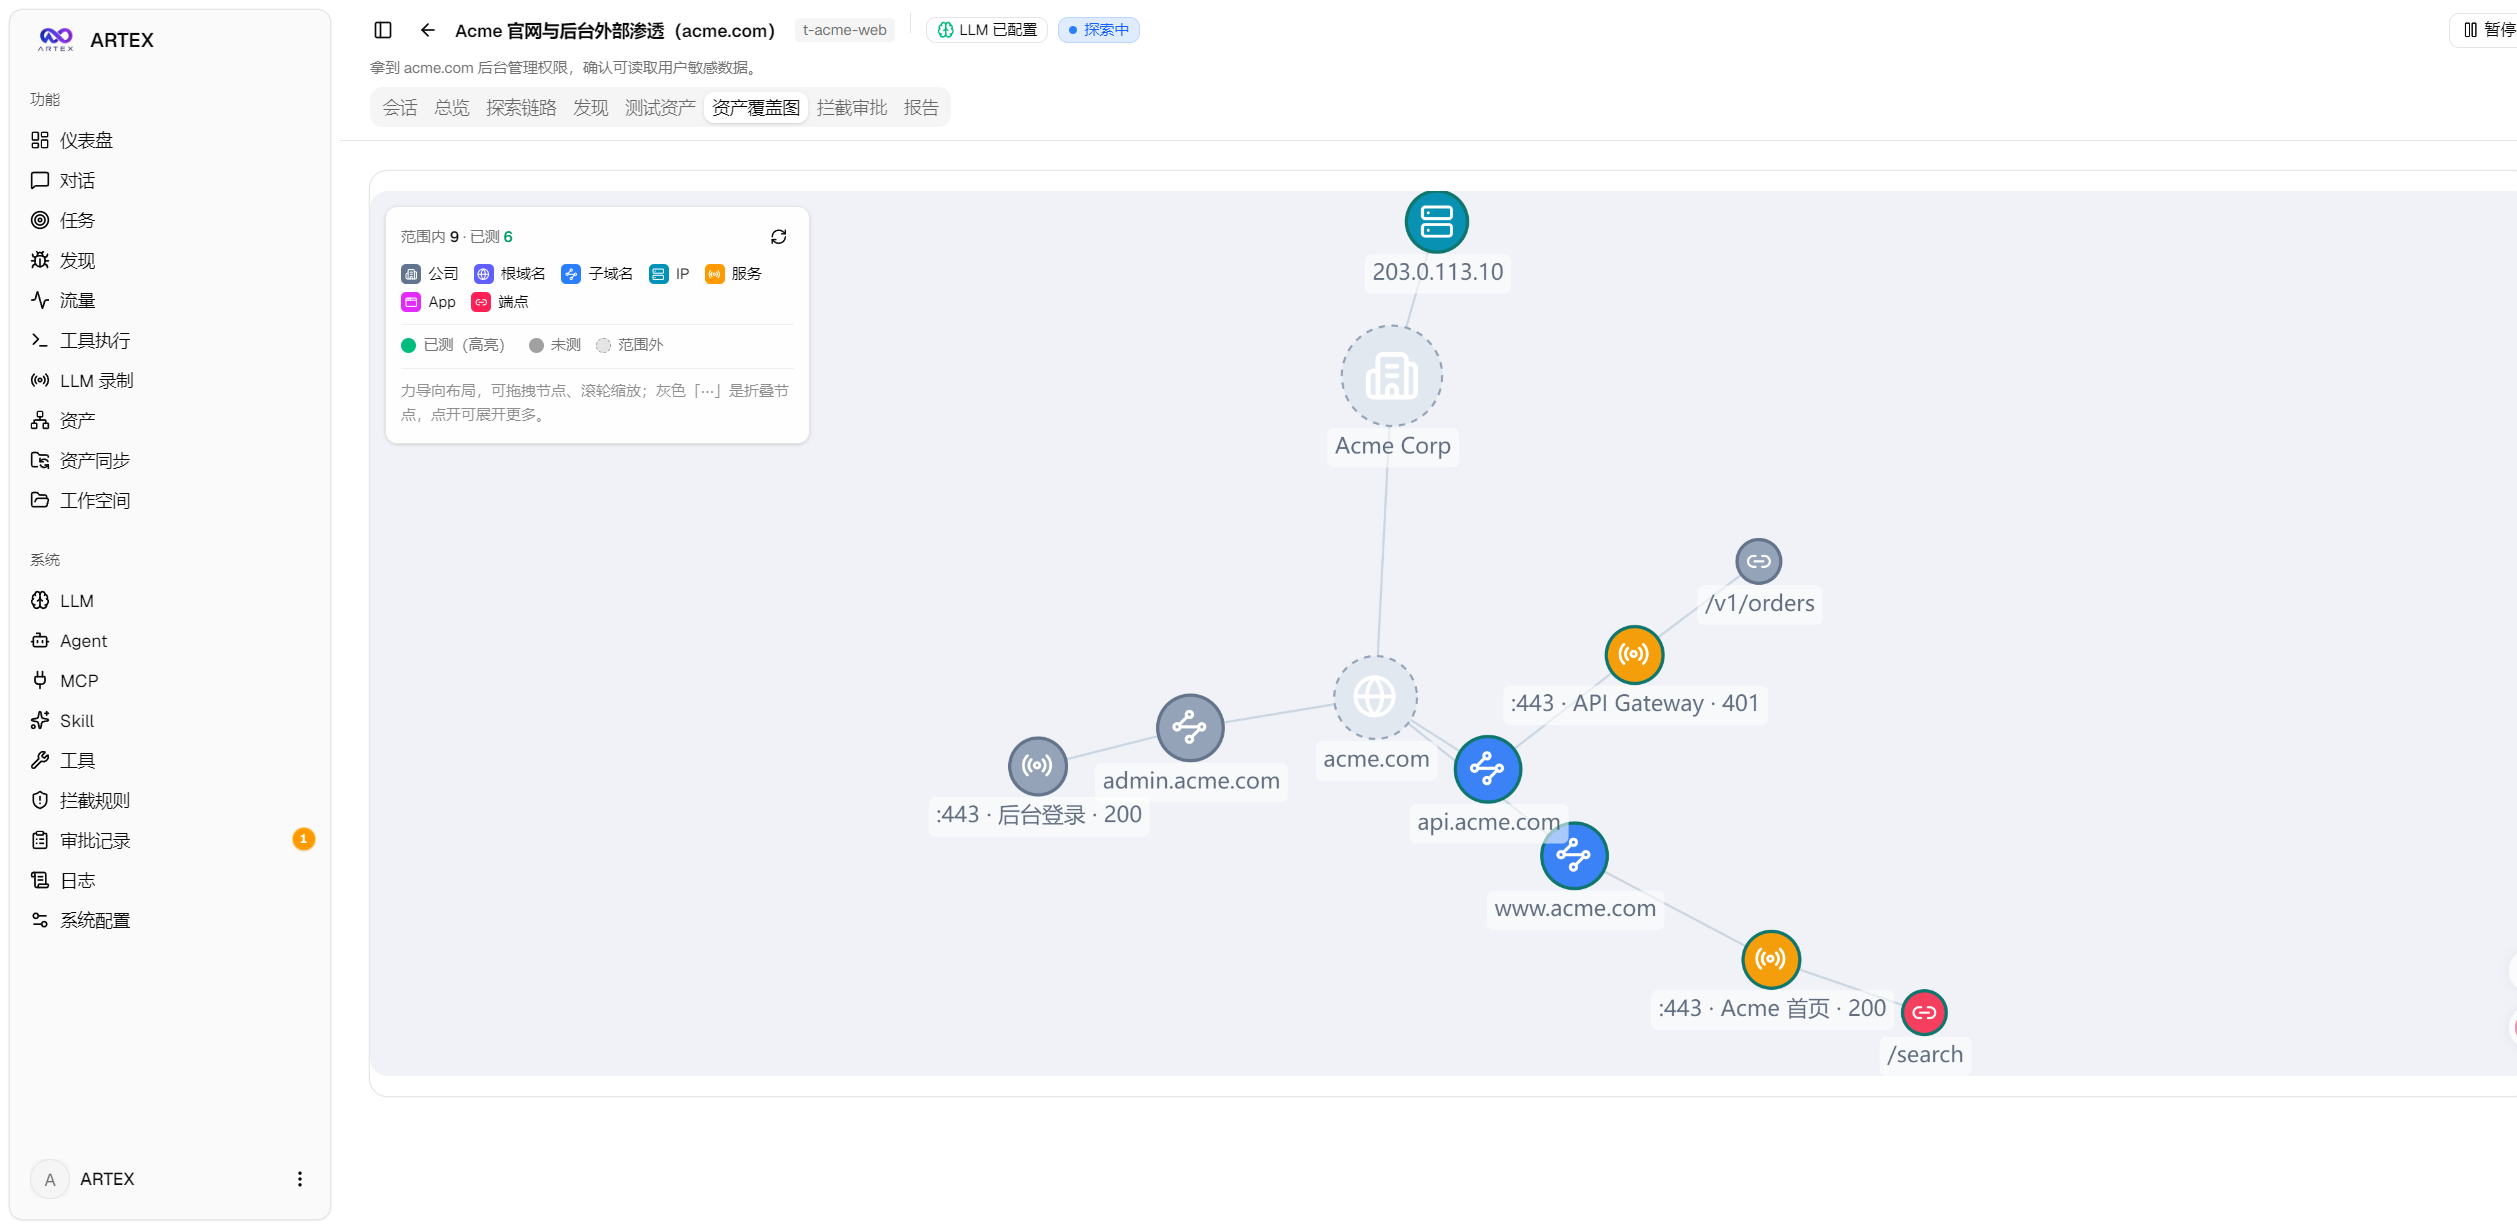
The asset coverage map can display in-scope assets using a force-directed layout and highlight tested nodes. It supports collapsing and expanding nodes and is useful for seeing which assets have been explored and which remain uncovered.
Synchronize ScopeSentry Assets
If you have already collected assets in ScopeSentry, connect the data source on ARTEX's “Asset Synchronization” page to avoid collecting the same assets again.
- Enter the ScopeSentry address and API key to connect the data source.
- Select the targets to synchronize by project or task.
- Select asset types, such as domains, subdomains, IPs, ports, sites, or endpoints.
- Run the import so ARTEX can consolidate the data according to the organization's asset scope.
- Check the import results in the asset graph and provide them to agents for subsequent exploration.
The asset graph is the global source of truth for assets shared across tasks. The program calculates parent-child relationships and deduplication keys; agents submit the raw asset information.
Understanding ARTEX's Dual-Graph Architecture
Asset Graph: Describing What Assets Exist
Nodes in the asset graph include root_domain, subdomain, ip, service, app, and endpoint. Domains, subdomains, services, and endpoints are organized through parent-child relationships and associated with the relevant company.
Exploration Graph: Describing How Tasks Progress
The exploration graph is stored independently for each task. Its nodes include goal, intent, fact, finding, and hint. The system records the progression chain through relationships such as spawns, derived_from, yields, and proves.
The two graphs are linked through anchors. Intents, facts, and vulnerabilities can be anchored to specific assets, allowing you to view the assets involved from an exploration path or trace an asset back to the paths tested against it in the current task.
How the Planner and Workers Collaborate
The engine uses an event-driven loop: when the graph changes, it wakes the planner. The planner reads the current situation and dispatches intents; a worker claims one intent, uses tools to execute it, and writes new assets, facts, or findings back to the database. The write-back operation triggers the planner again.
The planner dispatches intents only when it discovers new directions that have not yet been covered. After completing its claimed intent, a worker stops, preventing different workers from repeating execution without bounds.
For multi-step exploration chains with dependencies, the planner maintains a task-specific shared todolist. The next step is dispatched only after the prerequisite step is complete and the corresponding fact exists. This prevents the entire chain from being expanded in parallel at once.
Inspecting Other Workers' Execution
Subsequent workers can use search_all_worker_traces(q) to search by keyword through the execution process of other work in the current task. They can also use list_worker_traces to view executed work, then use get_worker_trace(intent_id, step_ids=[...]) to retrieve the complete content of specific steps. The system automatically excludes the current worker's own intent.
This process-level information exchange helps agents reuse observations that have not yet been formally written to facts, while preserving the boundary that each worker executes only its own claimed intent.
Traffic Recording and Approval
ARTEX provides a traffic-recording proxy and a tool-approval gate. The traffic page displays records generated by tool execution, while the interception and approval page handles operations that require human confirmation.
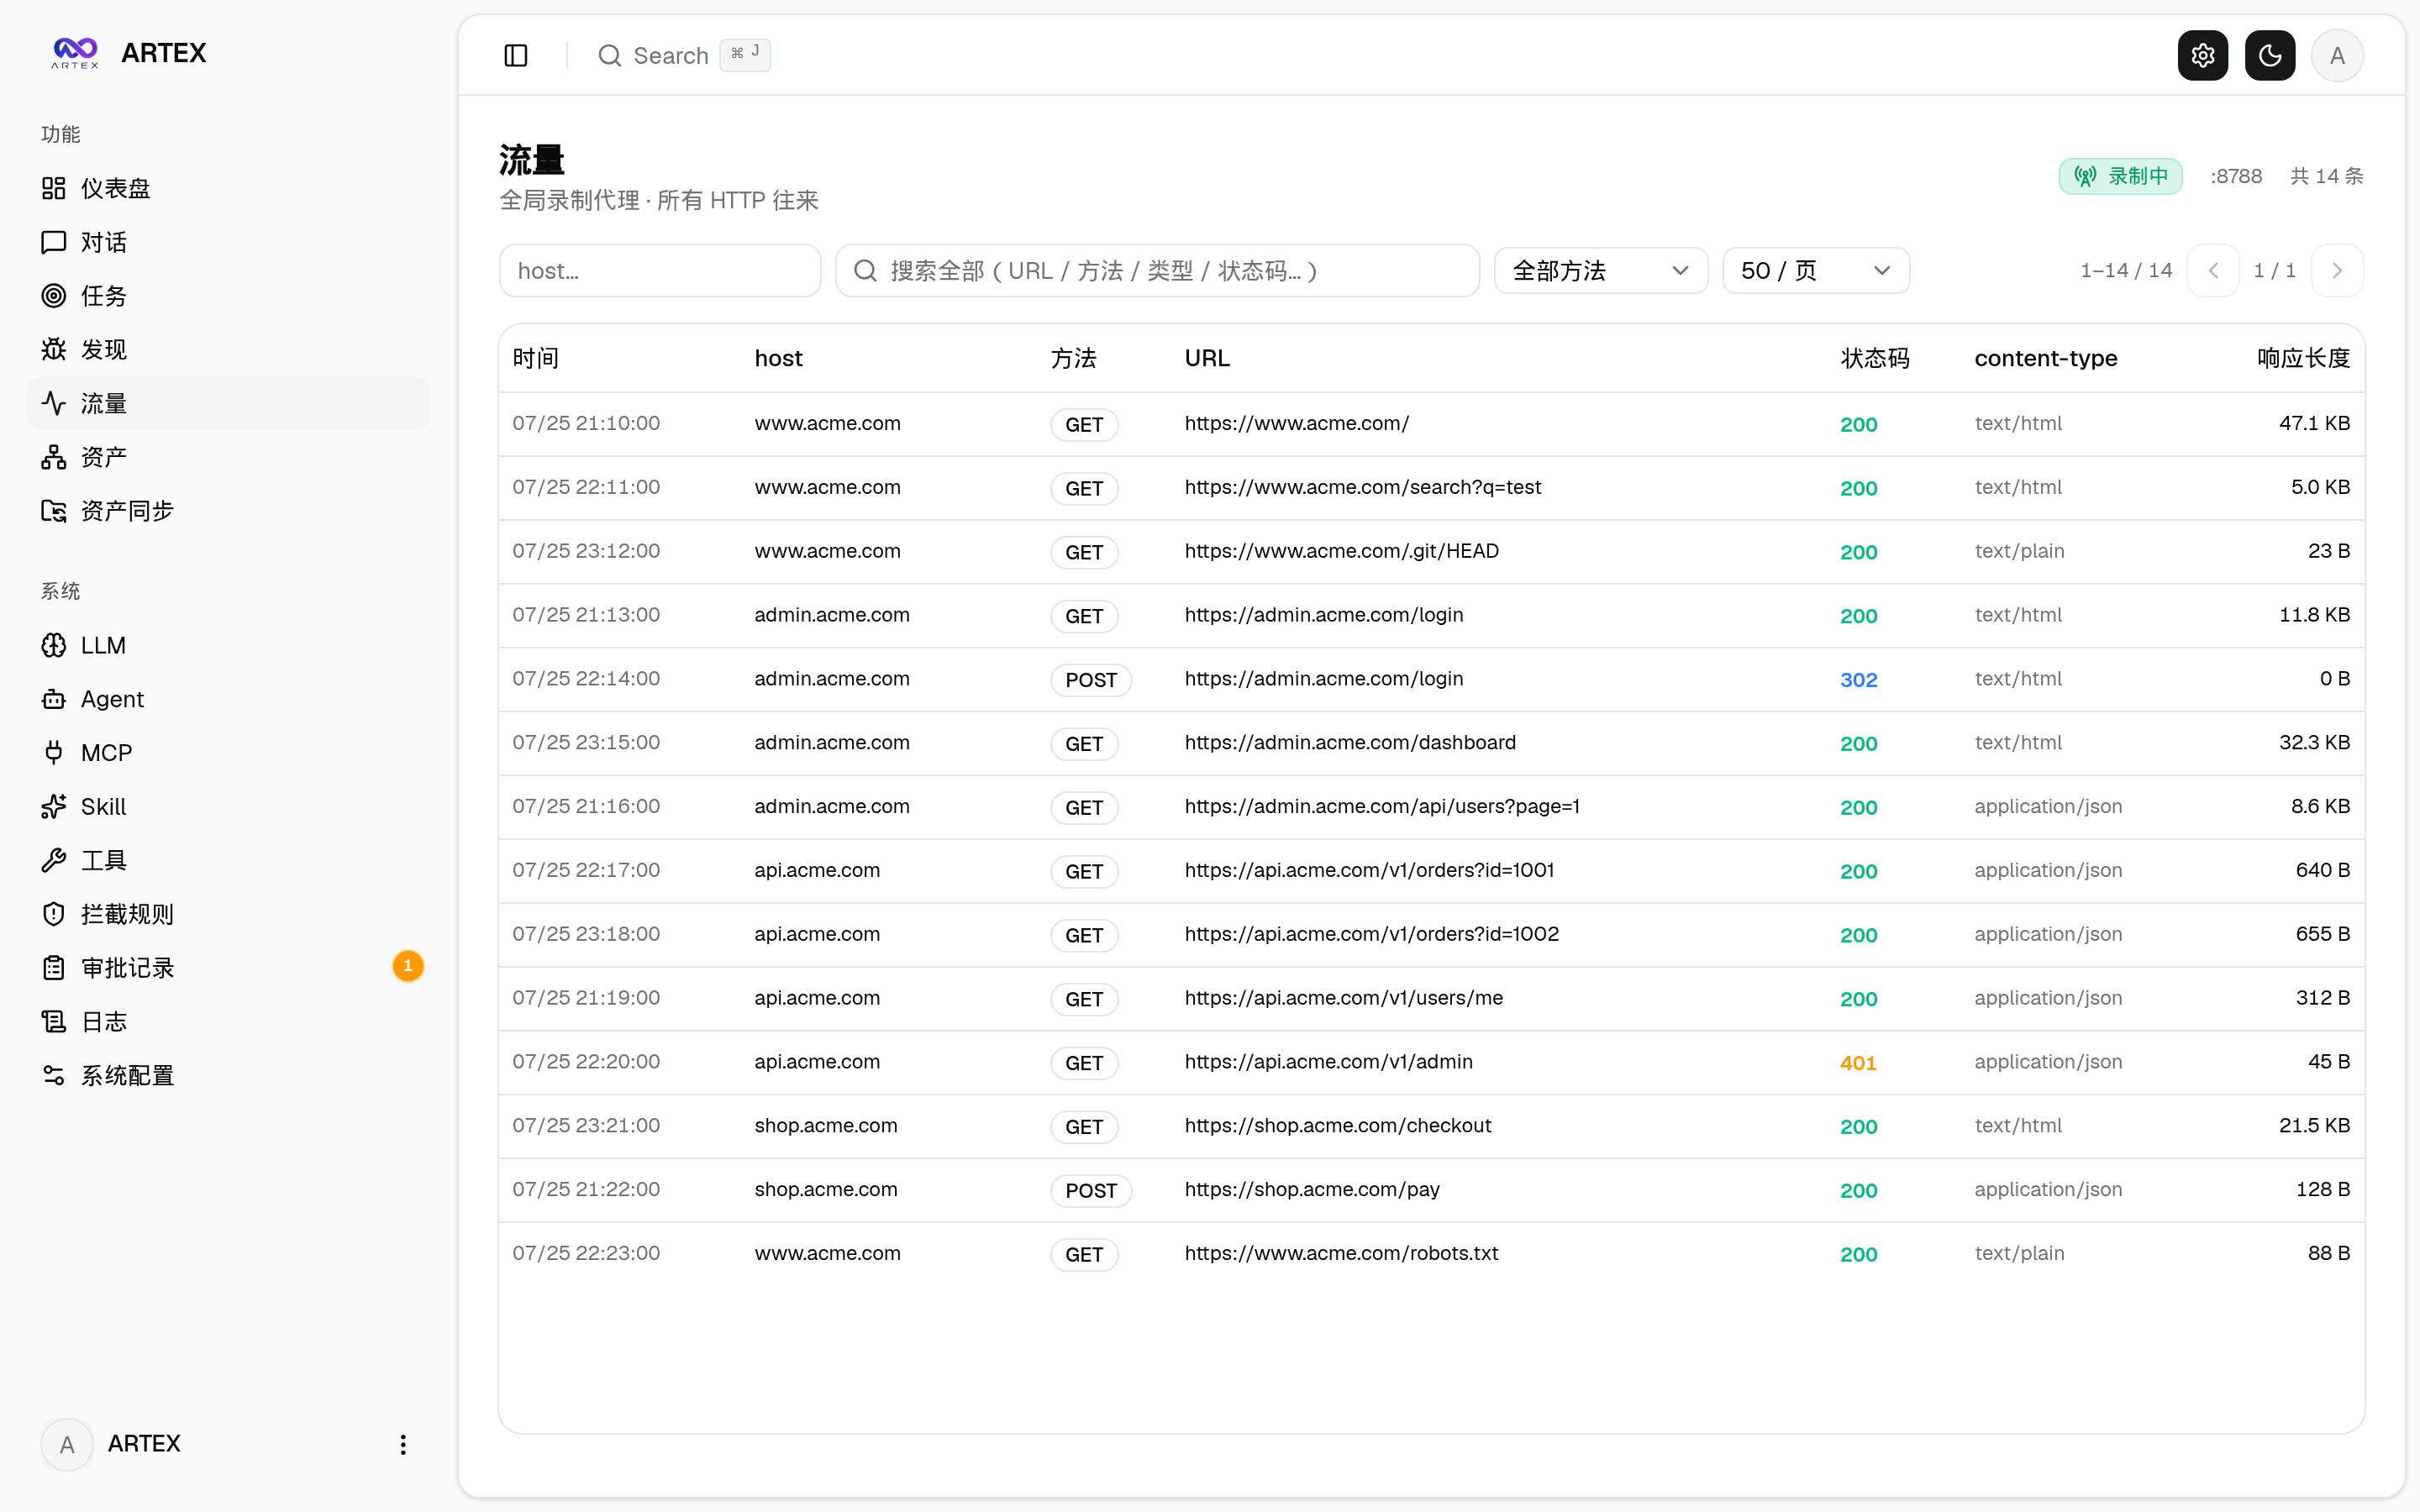
During security verification, it is recommended to review the task session, tool calls, activity stream, and traffic records together to confirm that system behavior matches expectations. Human-in-the-loop conversations can also provide additional context and participate in approvals.
Running Vulnerability Retests
The “Retest” tab in task details lets you select vulnerabilities from the task page by page, review historical conclusions and evidence, and start a retest independently. Retest entry points are available in the vulnerability list, vulnerability details, task group view, and asset view.
- Click “Retest” in the vulnerability list or vulnerability details.
- Enter the fix version, test conditions, or limitations as needed.
- Start an independent retest Agent session.
- Review the retest process in the session, then review the conclusion and evidence when it ends.
Retest conclusions include “Still Reproducible,” “Fixed,” and “Unable to Confirm.” If the retest completes successfully and the conclusion is “Fixed,” the system automatically updates the vulnerability disposition status. An in-progress, failed, stopped, or otherwise concluded retest does not automatically change the original status. Original evidence and reports are retained.
The system provides an editable “Vulnerability Retest” retester Agent. Its prompt, LLM, runtime budget, and tools can be configured in Agent management. If no dedicated LLM is bound, the globally active configuration is used. When the same vulnerability is being retested, the existing session is reused. A new retest can be started after it is stopped, fails, or the service restarts.
Note that the project documentation states that retest history is not yet included in vulnerability report exports or task archive packages, and is not automatically associated with traffic packages. Demo mode generates only explicitly marked simulated records and does not request real targets.
Reverse Proxy Deployment Essentials
The frontend, API, and SSE are served by the same backend port by default. Therefore, you generally need to expose only the HTTPS port publicly and keep ARTEX's 8787 port on the internal network. The real-time activity stream uses the same-origin address, so NEXT_PUBLIC_SSE_BASE generally does not need to be configured.
Reverse proxies such as Nginx must disable SSE buffering and set a sufficiently long read timeout. Otherwise, the browser may connect successfully but fail to continue receiving activity events.
location / {
    proxy_pass http://127.0.0.1:8787;
    proxy_set_header Host $host;
    proxy_set_header X-Forwarded-Proto $scheme;
    proxy_buffering off;
    proxy_cache off;
    proxy_read_timeout 3600s;
    proxy_http_version 1.1;
    proxy_set_header Connection "";
}
Set NEXT_PUBLIC_SSE_BASE at build time only when SSE must use a different origin, such as a separate subdomain. This variable is embedded into the static package during next build; setting it at container runtime will not take effect.
Upgrades and Rollbacks
ARTEX upgrades replace the program while retaining the PostgreSQL data volume, ./data, and ./skills. It is recommended to perform one-click updates from the “Version and Updates” card on the system settings page. The update process downloads the release package for the current platform, verifies SHA256SUMS, runs a smoke test on the new binary, and then lets the startup script complete the replacement.
If verification or the smoke test fails, the staged program is discarded. If the new version fails to start three consecutive times, it is rolled back automatically. The previous version is retained as artex.old. However, the database schema is not rolled back with the program, so the database and ./data should still be backed up before upgrading.
Updates restart the service and interrupt running tasks, so they should be performed during idle periods. For Docker deployments, note that a page update replaces only the program and does not replace the toolchain in the image. To upgrade the image, run:
docker compose pull artex
docker compose up -d artex
You can also use the update script in the repository:
cd ARTEX
./update.sh
Local Development and Testing
In a development environment, dev.sh can start the backend, traffic proxy, and Next.js development server together:
./dev.shThe default backend port is 8787, the traffic proxy port is 8788, and the frontend development server runs on 5173. You can also run them separately:
go run ./cmd/artex
cd web && npm run dev
go test ./...
If you only need to preview the frontend without starting the backend, use:
cd web && NEXT_PUBLIC_MOCK=1 npm run devSummary
ARTEX integrates a Go monolithic backend, Next.js interface, PostgreSQL, LLM agents, traffic recording, approval mechanisms, and asset management into a single system. To get started, deploy it using Docker or the installation script, configure PostgreSQL and the LLM, and then gradually learn how the system behaves through tasks, sessions, exploration chains, asset coverage maps, and traffic records.
Understanding the division between the asset graph and the exploration graph is key to mastering ARTEX: the asset graph answers “What assets exist?”, while the exploration graph answers “How does the task progress?” Before any testing, strictly limit activity to a local isolated environment and the permitted learning purposes of the project, and comply with the project statement, open-source license, and applicable laws.