
- Monthly visits
- 0
- Pricing
- Free & Paid
- Listed
- 2026-08-05
- Updated
- 2026-08-05
01What is JoyAI-Video-Edit
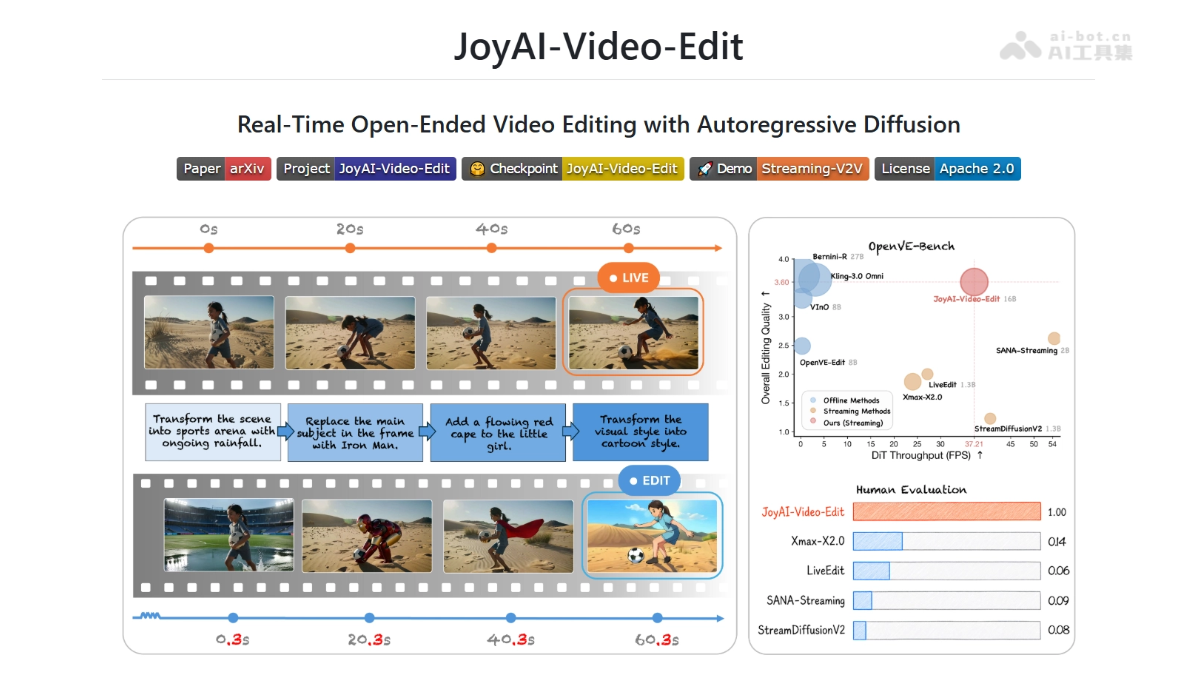
JoyAI-Video-Edit is JD.com's self-developed, open-source real-time streaming video editing model. Built on a 16B-parameter autoregressive diffusion architecture, it achieves 30 FPS inference at 720P resolution and supports stable streaming editing for videos of any duration. Users can modify people, scenes, styles, and objects in real time during video playback through natural-language instructions, without waiting for the complete video to be generated. The model surpasses all streaming editing methods on the OpenVE-Bench evaluation, leading across all metrics, while also providing a large-scale data synthesis pathway for embodied intelligence.
02Key Features of JoyAI-Video-Edit
Real-time streaming editing: Edit video frames as they arrive, without needing to know the complete sequence in advance.
Open-ended instruction control: Supports global style transfer, local object addition, removal, and modification, background replacement, action adjustment, and reference-image-guided editing.
Processing of any duration: Breaks through second- or minute-level limitations and enables stable editing continuously as the video plays.
High-throughput 720P deployment: The end-to-end pipeline reaches 30.19 FPS at a resolution of 720×1280.
Multidimensional editing capabilities: Covers tasks such as character outfit changes, scene transformations, style conversion, object replacement, and subtitle editing.
03Technical Principles of JoyAI-Video-Edit
Follow WeChat and reply “开源” to join the AI open-source project group
MLLM conditioning encoder: Uses a multimodal large language model to encode natural-language instructions as editing conditions, enabling open-ended semantic control.
Causal video VAE: Uses a variational autoencoder with a causal temporal structure to compress and reconstruct video frames, ensuring temporal consistency in streaming scenarios.
16B-parameter MMDiT backbone: Uses a 16B multimodal diffusion Transformer as its core, fusing text and visual features for autoregressive diffusion generation.
Autoregressive distribution-matching distillation: Accelerates inference through a distillation strategy that aligns autoregressive distributions, significantly reducing the distribution gap between training and inference.
Long-horizon optimization and bounded-KV inference: Introduces long-horizon stability optimization and a bounded KV-cache mechanism to suppress cumulative temporal drift while maintaining high throughput.
04How to Use JoyAI-Video-Edit
Environment setup: Create a Conda environment with python=3.10 and install the dependencies in requirements.txt.
Download the weights: Obtain the model files from Hugging Face and place the checkpoints according to the specified directory structure.
Start the service: Enter the deploy directory and run bash run_server.sh to start the local server.
Open the interface: Open http://localhost:8080 in a browser to access the interactive editing interface.
Real-time editing: Upload a video or connect a camera stream, then enter natural-language instructions to edit as the video plays.
05Core Advantages of JoyAI-Video-Edit
Real-time streaming editing: Processes frames as they arrive without waiting for the complete sequence, delivering a true “edit-as-you-watch” interactive experience.
Excellent speed and quality: End-to-end inference reaches 30.19 FPS at 720P resolution and surpasses all streaming and offline editing methods on the OpenVE-Bench evaluation.
Stable output for videos of any duration: Breaks through the traditional limitation of supporting only second- or minute-level clips, enabling continuous, drift-free editing as the video plays.
Open-ended semantic control: Based on an MLLM conditioning encoder, it supports multidimensional editing driven by natural-language instructions, including global styles, local objects, background replacement, and reference-image guidance.
Efficient inference architecture: The 16B-parameter autoregressive diffusion Transformer, combined with distribution-matching distillation and bounded KV caching, significantly reduces training-inference discrepancies and suppresses cumulative temporal errors.
06JoyAI-Video-Edit Project Links
GitHub repository: https://github.com/jd-opensource/JoyAI-Video-Edit
Hugging Face model repository: https://huggingface.co/jdopensource/JoyAI-Video-Edit
arXiv technical paper: https://arxiv.org/pdf/2608.03974
07Applications of JoyAI-Video-Edit
Short-video creation: Creators can replace characters' clothing and adjust scene styles in real time during video playback, improving content production efficiency.
Real-time livestream effects: Streamers can change backgrounds or add virtual elements while broadcasting, enabling interactive visual enhancements for livestreams.
Home furnishing and interior design: Users can replace furniture, wall materials, and lighting effects in real time while viewing room videos, assisting with renovation decisions.
Film and television post-production previews: Directors can quickly try different visual styles and scene replacements during editing, reducing the cost of trial and error.
Embodied intelligence data synthesis: Converts human-hand operation videos into robotic-arm operation materials, expanding the scale of robot training data at low cost.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0