
- Monthly visits
- 0
- Pricing
- Free & Paid
- Listed
- 2026-08-13
- Updated
- 2026-08-13
01What Is PixelRAG?
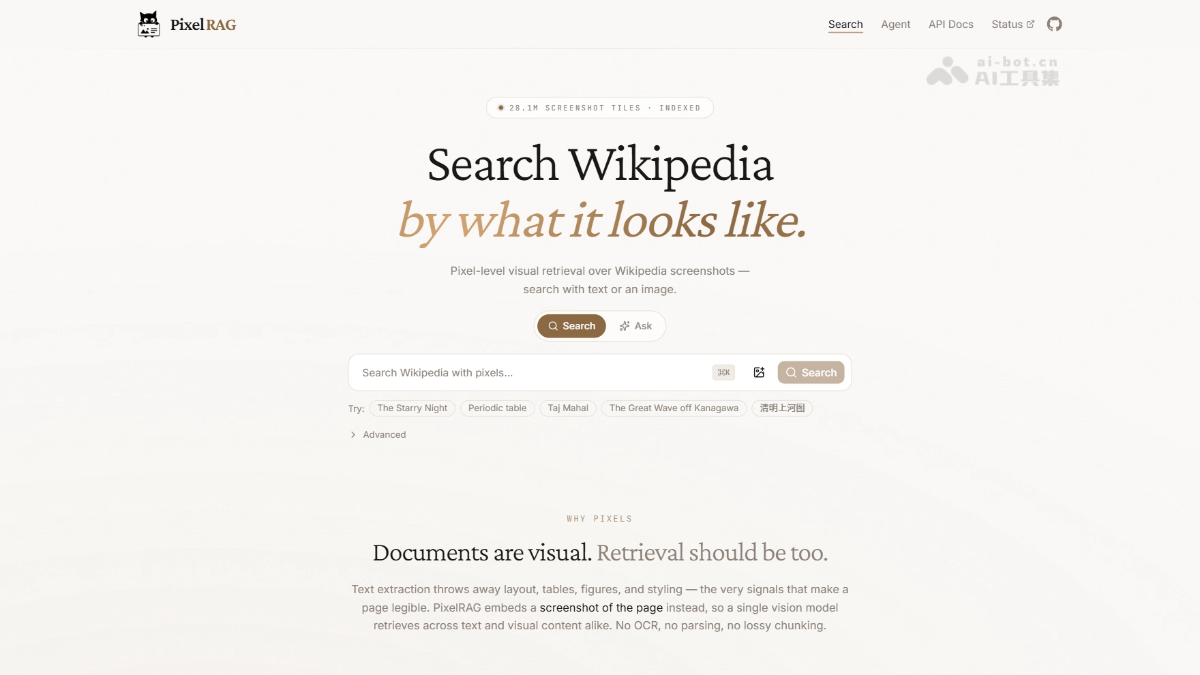
PixelRAG is a vision-native RAG framework open-sourced by Berkeley SkyLab/BAIR. It moves beyond the traditional approach of extracting webpages into plain text before retrieval, instead using a browser to render webpages and PDFs into screenshot tiles. With LoRA-fine-tuned Qwen3-VL visual vector retrieval, models can directly read tables, charts, and layouts in images, solving the common problems of lost tables and layouts in traditional RAG.
02Key Features of PixelRAG
Page rendering (pixelshot): Uses headless Chromium to render webpages and PDFs into screenshot tiles, fully preserving tables, charts, and layouts. On Windows/macOS, it automatically invokes the system Chrome and supports mixing URLs with local files.
Visual semantic retrieval: Encodes screenshots as vectors and supports text-to-image and image-to-image search. FAISS is used locally by default, with support for switching to Qdrant at scale (including quantized compression, disk storage, and multi-service sharing).
Direct pixel reading: Feeds retrieved screenshots directly into a VLM as image inputs to answer questions, with no text conversion throughout the process.
Hosted search service: Provides a keyless API and web demo, with a prebuilt index of 8.28 million Wikipedia pages for out-of-the-box search.
Self-built indexing pipeline: Offers the complete set of commands—pixelrag index / embed / build-index / serve—for building indexes from your own PDFs and websites. Small-scale workloads can run on a Mac with Apple Silicon.
Agent integration: The pixelbrowse Claude Code plugin requires no MCP dependency and lets Claude “see” webpages through screenshots instead of consuming incomplete HTML.
03How PixelRAG Works
Follow us on WeChat and reply “开源” to join the AI open-source project community.
Representation layer—documents as images: Uses headless Chromium to capture webpages as screenshots, convert PDFs into page images, and split them into tiles, preserving visual structures such as aligned table rows and columns, charts, and infographics exactly as they appear.
Retrieval layer—visual vector embeddings: Based on Qwen3-VL-Embedding-2B, it uses LoRA fine-tuning on contrastive-learning data so screenshots can be retrieved semantically. Queries match “that section of the image” rather than “that paragraph of text.” Vectors are stored locally in FAISS, with support for switching to Qdrant at scale.
Generation layer—VLM image understanding and answering: Retrieved screenshot tiles are provided directly to a vision-language model as pixel inputs. The model reads numbers and layouts directly from the images, with no intermediate text conversion.
Scale and efficiency: The first RAG pipeline to cover the entire Wikipedia corpus in screenshot form. Pixel representations also introduce a new efficiency lever—reducing screenshot resolution can cut token costs by up to 3× without reducing accuracy. In experiments, it comprehensively outperformed text RAG baselines, with gains of up to 18.1%.
04How to Use PixelRAG
Installation: Run pip install pixelrag to install the core tools (Python 3.10+ required).
Render pages: Run pixelshot https://example.com -o ./tiles to render a webpage or PDF into screenshot tiles.
Try the hosted search: With no configuration required, send a POST request directly to https://api.pixelrag.ai/search to search the index of 8.28 million Wikipedia pages, or open pixelrag.ai in a browser for an online trial.
Build your own index: Create a pixelrag.yaml configuration specifying the document paths, embedding model, and output directory. Run pixelrag index build to build the index, then start the search service with pixelrag serve --index-dir ./my_index --port 30001. Small-scale workloads can run on a Mac with Apple Silicon; the full Wikipedia index is approximately 217GB and requires GPU compute.
Connect to Claude Code: Run uv tool install pixelrag, then install the pixelbrowse plugin (claude plugin marketplace add StarTrail-org/PixelRAG and claude plugin install pixelbrowse@pixelrag-plugins) to let Claude “see” webpages through screenshots without MCP.
Advanced training: To develop your own embedding model, enter the train/ directory, which is an independent uv project, and fine-tune it according to the README. Alternatively, reuse the officially open-sourced LoRA weights and training data.
05Core Advantages of PixelRAG
Lossless information: Uses screenshots instead of text extraction, fully preserving table rows and columns, charts, and layouts, completely solving the problem of traditional RAG appearing to have the answer while losing it during text extraction.
Stronger performance: The paper shows that it comprehensively outperforms text RAG baselines and also performs better on text-only tasks such as NQ and SimpleQA. It achieves gains of up to 18.1% on multimodal and Agentic benchmarks.
Lower cost: Pixel representations provide a unique efficiency lever: reducing screenshot resolution can cut token costs by up to 3× without reducing accuracy.
Simpler pipeline: Eliminates complex HTML parsing, cleaning, and chunking. Documents can be rendered as screenshots and added to the index, significantly reducing engineering effort.
Scale validated: It is the first RAG pipeline to cover the entire Wikipedia corpus in screenshot form, and includes a keyless hosted index of 8.28 million pages for immediate testing.
06PixelRAG Project Links
Project website: https://pixelrag.ai/
GitHub repository: https://github.com/StarTrail-org/PixelRAG
arXiv technical paper: https://arxiv.org/pdf/2606.28344
07PixelRAG Use Cases
Financial report and data table question answering: Directly reads numbers from financial report pages and statistical tables, avoiding row and column misalignment caused by text parsing.
Dashboard and chart retrieval: Retrieves screenshot regions containing charts and KPI dashboards, allowing models to read and answer questions from images.
Infographics and illustrated documents: Makes content such as infographics and flowcharts searchable—content that traditional text indexing cannot cover.
Multi-column product pages: Preserves the original layout of complex product comparison pages and news pages during retrieval.
Agent webpage reading: Through Claude Code’s pixelbrowse plugin, lets agents “see” webpages through screenshots instead of consuming incomplete HTML.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0