
- Monthly visits
- 0
- Pricing
- Not set
- Listed
- —
- Updated
- 2026-09-08
01What is LLaDA-Image
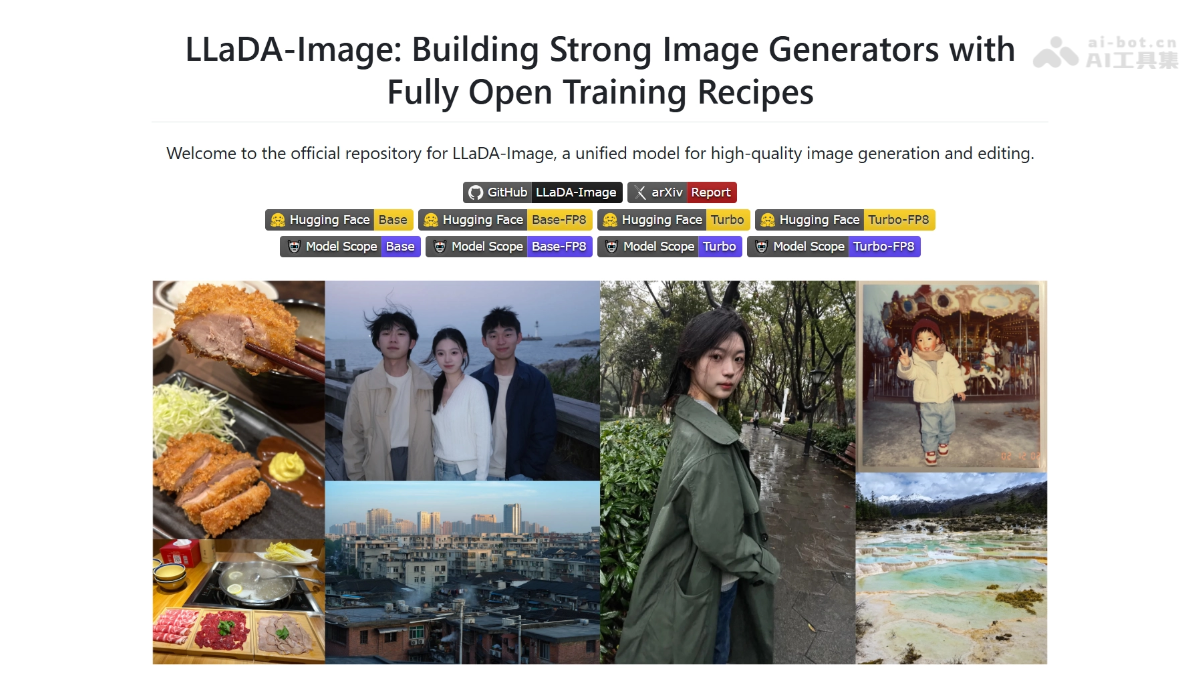
LLaDA-Image is a 6B-parameter unified image generation and editing model open-sourced by Ant Group's inclusionAI. It follows an innovative training approach of pure-image pretraining followed by language alignment, using a fully diffusion-based architecture (LLaDA2.0-mini for understanding + 6B DiT for generation) to support text-to-image generation, instruction-based editing, and Chinese and English text rendering. The Turbo version generates images in just 2–4 steps and ranks first among open-source models in both the Chinese and English tracks of Qwen-Image-Bench.
02Key Features of LLaDA-Image
Text-to-image generation: Generate high-fidelity, detail-rich, photorealistic images from natural language descriptions.
Instruction-based image editing: Upload a reference image and enter a natural language instruction to precisely modify specified areas while keeping the rest unchanged.
Chinese and English text rendering: Accurately render Chinese and English text in generated images, supporting poster creation, layout design, and artistic typography.
VQ-conditioned generation: Use visual quantization (VQ) tokens as conditional inputs for controllable image generation.
Reference image editing: Use uploaded images as references for operations such as style transfer and content modification.
Turbo fast inference: The distilled model generates high-quality 1024×1024 images with only 2–4 sampling steps.
03Technical Principles of LLaDA-Image
Follow us on WeChat and reply “开源” to join the AI open-source project community group.
Unified full-diffusion architecture: The model consists of the understanding module LLaDA2.0-mini, a MoE-based diffusion language model, and the 6B DiT generation module. Both backends are diffusion models connected through a Connector, decoupling semantic understanding from pixel generation.
Staged training strategy: Following a “learn to draw first, then learn to follow instructions” approach, the model first undergoes pure-image pretraining and mid-training to establish strong visual generation priors, then introduces paired language supervision for text-vision alignment.
High-quality data construction: Approximately 220 million samples were used for generation training, of which 98% are real images. During language alignment, image descriptions were generated and verified by Qwen-series large models to ensure accurate instruction following.
Efficient training optimization: RMSNorm, which is parameter-independent, is used throughout the pipeline in place of LayerNorm, together with the Muon optimizer to improve the stability and efficiency of large-scale training.
Twin-DMD fast distillation: The Turbo version compresses the Base model using Twin-DMD distillation. It generates high-quality 1024×1024 images in 2–4 sampling steps, balancing speed and quality.
04How to Use LLaDA-Image
Environment setup: Install Python 3.11, PyTorch 2.8, Diffusers 0.39.0, FlashAttention 2.8.3, and other dependencies to build a local inference environment.
Obtain model weights: Download the model files for LLaDA-Image (high-fidelity version) or LLaDA-Image-Turbo (fast version) from Hugging Face or ModelScope.
Text-to-image generation: After loading the model, enter a text description. Set the Base version to 50 steps with a guidance scale of 5.0, or the Turbo version to 2–4 steps with a guidance scale of 1.0, to generate 1024×1024 images.
Instruction-based image editing: Upload a reference image and enter a natural language editing instruction, such as “replace the background with a seaside scene.” The model automatically keeps unedited areas unchanged.
Mind the size requirements: Input dimensions for text-to-image and VQ-conditioned generation must be multiples of 16; editing tasks require multiples of 32.
05Core Advantages of LLaDA-Image
Leading open-source performance: Ranks first among open-source models in both the Chinese and English tracks of Qwen-Image-Bench, with an overall score exceeding mainstream open-source models such as FLUX.2 Max.
Unified generation and editing: A single model supports both high-quality text-to-image generation and precise instruction-based image editing, eliminating the need to switch between models.
Fast inference: The Turbo distilled version generates high-fidelity 1024×1024 images in only 2–4 sampling steps, significantly reducing wait times.
Chinese and English text rendering: Delivers excellent Chinese and English text generation, making it suitable for design tasks such as posters, layouts, and artistic typography.
Photorealism: Pretrained on data consisting of 98% real images, it produces results with natural lighting, rich details, and a high degree of realism.
06LLaDA-Image Project Links
GitHub repository: https://github.com/inclusionAI/LLaDA-Image
Hugging Face model collection: https://huggingface.co/collections/inclusionAI/llada-image
arXiv technical paper: https://arxiv.org/pdf/2609.03796
07LLaDA-Image Use Cases
E-commerce visual design: Generate product hero images from product descriptions in one click, or quickly replace backgrounds and adjust lighting through instructions, reducing photography and post-production costs.
Marketing poster creation: Leverage its strong Chinese and English text rendering to directly generate commercial posters and social media visuals containing brand slogans and campaign information.
Social media content creation: Provide bloggers and creators with photorealistic portraits, landscapes, and lifestyle images, supporting stylized editing and rapid generation.
Game and film concept design: Quickly produce character and scene concept images from text, then iteratively modify details through instructions to accelerate the early creative process.
Personal photo retouching: Upload a photo and use natural language instructions to remove unwanted objects, replace the sky, adjust colors, and more while keeping unedited areas unchanged, replacing complex photo-editing software.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0