
Model Evaluation
AIEZZ tool tag
Browsing AI products tagged “Model Evaluation”, with 5 matching results.
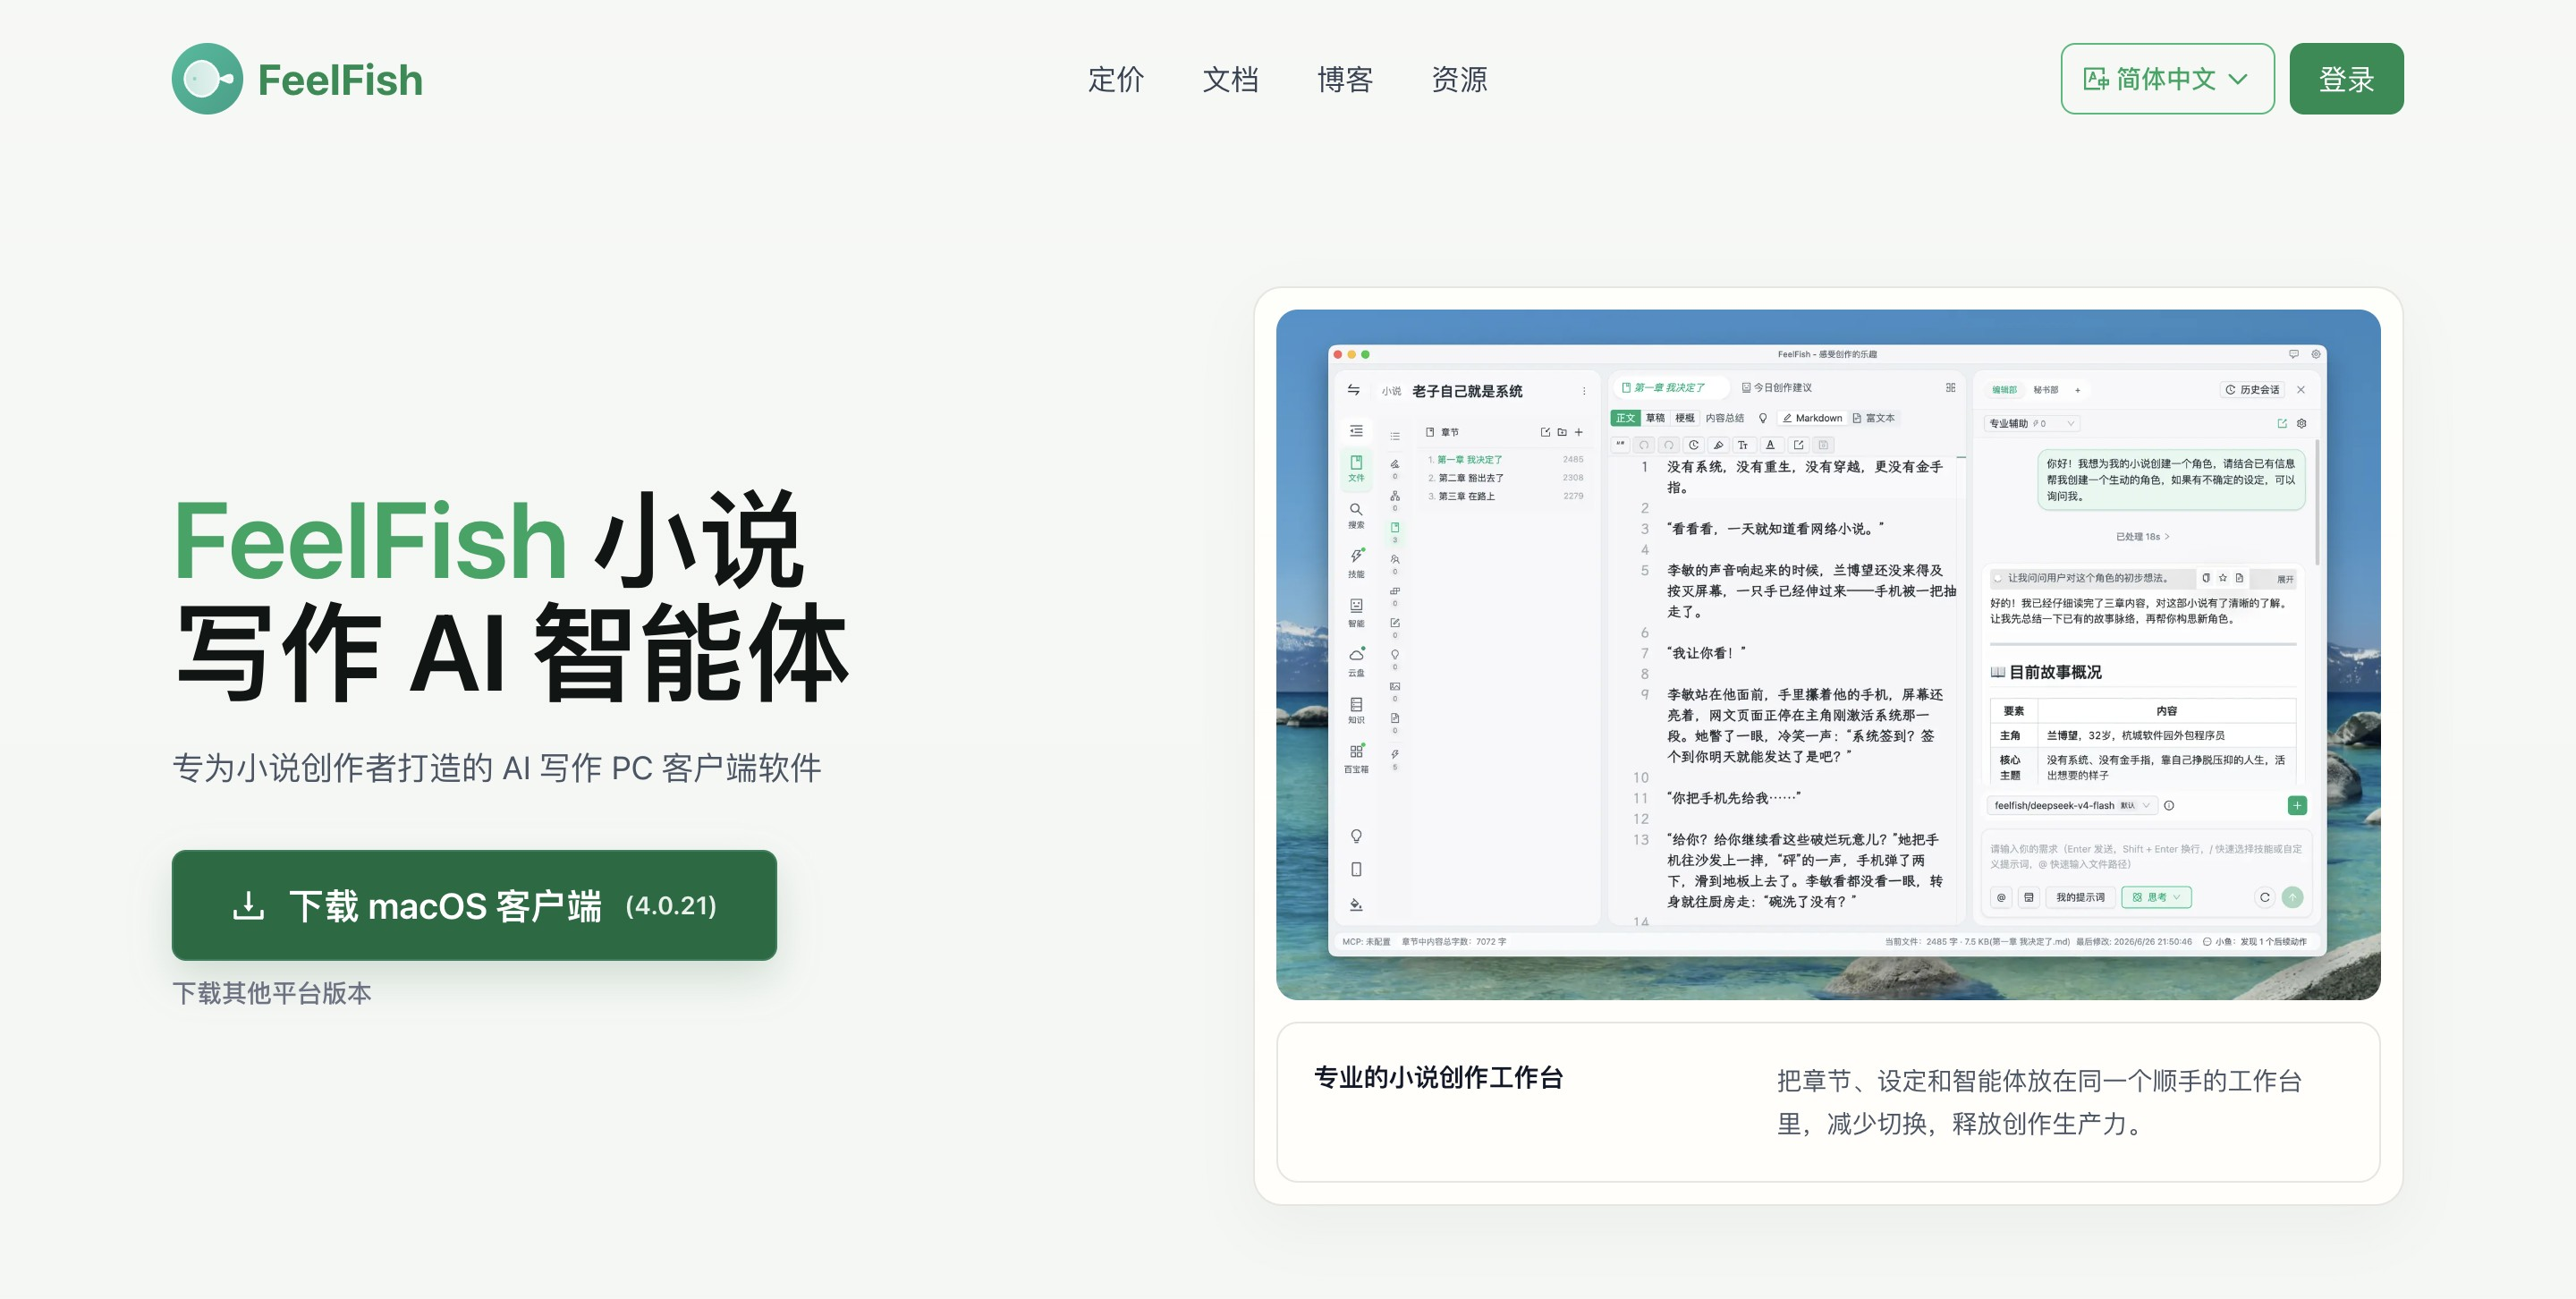 2026 Review of the Latest AI Novel Writing Software: FeelFish 4.0AI ProgrammingFeelFish 4.0 is professional novel writing software that transforms large AI models into a writing team that understands your project. It provides structured project management covering chapters, outlines, characters, and settings, and supports intelligent context to maintain logical consistency in long-form creation. The tool supports customizable multi-agent collaboration, desktop and mobile remote control, and cloud drive synchronization plus a local time machine to ensure manuscript security. It is designed to provide a complete human-AI collaborative workflow for long-form creators of online novels, screenplays, and more.00
 LMArenaAI ToolboxLMArena is a community-driven AI model evaluation platform led by an academic team at the University of California, Berkeley. Its core process has two models with hidden identities answer the same question, after which users vote based on answer quality and then reveal the model identities. The platform uses voting results and an Elo rating system similar to chess to generate a dynamic leaderboard, covering tasks such as text and image evaluation. It is suitable for AI researchers, developers, technology enthusiasts, and general users who want to compare models side by side. It also provides open datasets for research. Note that the leaderboard reflects real user preferences and performance on specific tasks, and cannot replace dedicated testing for business requirements, cost, or stability.048
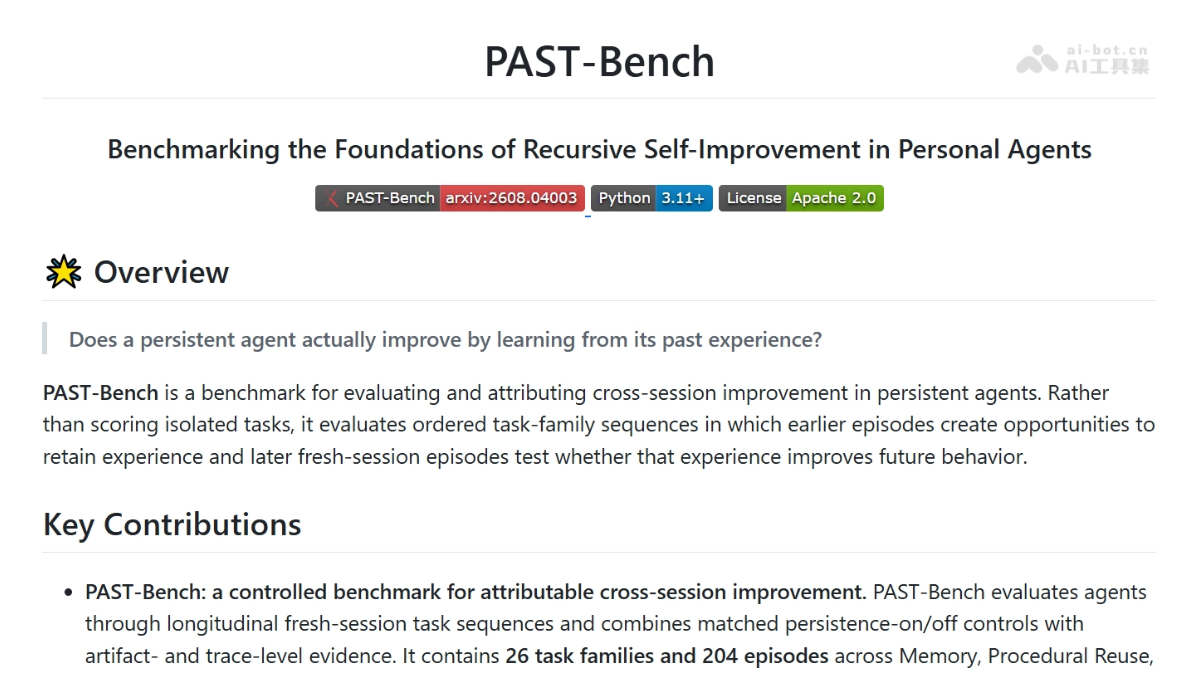 PAST-BenchAI AgentsPAST-Bench is a benchmark introduced by Mengdi Wang's team at Princeton University to evaluate the recursive self-improvement capabilities of personal AI agents. By comparing task performance under conditions with and without memory, PAST-Bench deter...00
 E-Bench – An Agent Evaluation Benchmark by Tencent Hunyuan and OthersAI Model EvaluationE-Bench is a benchmark for evaluating multi-step tool use, developed by the Tencent Hunyuan team in collaboration with Tsinghua AIR and Southeast University. It builds fully synthetic virtual environments based on Honor of Kings, QQ Music, and Tencent Meeting, containing 323 state-change tasks and more than 76,000 data records. Through dual asymmetry in information and tools, it evaluates whether models can proactively gather information and orchestrate multi-step tool calls. Deterministic database state-diff scoring ensures stable and reproducible results. The benchmark is intended for AI agent researchers and model developers, helping identify cost-effective models and advance the establishment of general-purpose agent evaluation standards.00
 Gemini 3.7 FlashAI ProgrammingGemini 3.7 Flash is the next-generation flagship AI model from Google DeepMind. Designed specifically for coding and agent workflows, it delivers major gains across software engineering, web development, and enterprise automation benchmarks...00
All tools with this tag are shown.