
All AI tools
AI Audio Tools
You are browsing popular AI products in the AI audio tools category, tailored through optimized matching to provide outstanding solutions for the industry.
 MAI-Transcribe-2AI Speech RecognitionMAI-Transcribe-2 is Microsoft's most powerful AI speech-to-text model, leading across accuracy, speed, and cost. It supports 60 languages and achieves an average word error rate of just 5.2% on the FLEURS test set.00
 YinjianAI Audio ToolsYinjian is an all-in-one AI audio creation platform provided by Ximalaya for podcast hosts, audiobook producers, and other audio creators. It supports recording, editing, article-to-speech conversion, audiobook production, and livestream assistance, with tools such as noise reduction, music arrangement, and subtitle generation for audio content creation.018.2
 AiSoundsAI Audio ToolsAiSounds is an AI audio tool for content creators, covering short videos, games, podcasts, social media, and content teams. Users can upload videos to generate background music matched to the visuals, enter Chinese descriptions to generate sound effects and music, or convert scripts into narration, voiceovers, and character voices. The platform also provides subtitle output, online audio editing, and delivery to editing software, making it easier to connect audio assets with post-production workflows. It is suitable for people who regularly produce videos, courses, podcasts, and social media content, helping reduce the need to switch between tools for finding assets and processing audio. Generated content still requires manual review and adjustment based on the visuals, script, and final production.098
 iFlytek Smart CreationAI Audio ToolsiFlytek Smart Creation is an AI audio and video creation platform launched by iFlytek, serving short-form video creators, corporate communications teams, educators, and media professionals. Users can enter text or upload recordings, select a virtual presenter, and generate narrated videos. The platform also offers text-to-speech, PPT-to-video conversion, and other AIGC creative tools. It supports Chinese and English voice-overs, along with settings such as speaking rate and intonation. The product uses a combined free and paid model. Generated results still depend on the choice of script, voice, and avatar, so pronunciation, visuals, and content accuracy should be checked before publication.038.6
 NoizAI Audio ToolsNoiz is an AI audio tool primarily used for voice cloning, speech generation, and cross-language dubbing. Users can upload an audio sample to generate a corresponding voice model, then convert text to speech. It can also be used for singing voice synthesis, emotional expression, and video lip-syncing. It is suitable for video creators, global content teams, audiobook producers, and indie game developers creating narration, multilingual versions, character dialogue, and other content. The platform offers free and paid plans, and the available features may vary. Results depend on the quality of the audio sample, the text context, and the emotion settings. Manual review of the voice, translation, and audio-visual synchronization is still recommended before publishing.087.7
 Audo StudioAI Audio ToolsAudo Studio is a browser-based AI audio processing tool designed to improve background noise, echo, and volume fluctuations in recordings. Users do not need to install software or adjust complex settings. After uploading audio, they can automatically reduce noise, remove echo, and balance volume, then use the result to create podcasts, videos, online courses, and other content. It is suitable for podcast creators, video bloggers, online course instructors, and individuals who occasionally need to clean up meeting recordings or voice memos. The product offers free and paid plans; specific quotas and pricing should be confirmed on the official website. Because its workflow emphasizes automation, it may be less suitable for situations that require detailed control over processing parameters.048.2
 DevoiceAI Audio ToolsDevoice is an AI tool for audio and video processing, offering audio transcription, background noise reduction, and lyric generation. Users can upload MP3, WAV, M4A, or video files without registering, convert content to TXT, DOCX, SRT, and other formats, process background noise in recordings, or generate hip-hop lyrics based on a theme and emotion. It is suitable for students organizing class recordings, professionals processing meeting and interview materials, and content creators, streamers, and musicians producing content. The tool supports multilingual recognition, and files are automatically deleted after processing, so it is not suitable for workflows that require long-term online storage or repeated access to original files.017.4
 SpeechifyAI Audio ToolsSpeechify is a voice-first reading and productivity tool that converts text from PDFs, documents, webpages, and other sources into speech. It also supports voice input, content Q&A, summarization, and podcast generation. Available on the web, as a browser extension, and through Windows, macOS, iOS, and Android apps, Speechify helps users handle reading, writing, and information comprehension tasks through listening and speaking.017.9
 DupDubAI Audio ToolsDupDub is an AI audio tool for content creators, primarily used to convert text into speech and assist with voice cloning, AI avatar narration, video translation, and subtitle editing. Users can enter or organize scripts on the platform, select voices and characters, adjust speech rate, pitch, pauses, and emotions, then export audio or create related video content. It is suitable for video creators, podcast and audiobook producers, marketers, educators and trainers, and companies expanding into international markets. The platform provides multi-character dubbing, multilingual support, and audio editing capabilities, but voice emotions, translation content, and AI avatar lip-sync results should still be manually reviewed before publication.017.8
 Supertone PlayAI Audio ToolsSupertone Play is an AI audio tool for voice creation, offering voice cloning, text-to-speech, and a character voice library for content creators, game and anime producers, advertising and marketing professionals, and musicians. Users can record about 10 seconds of their voice to generate a voice model, then enter text to convert it into speech while adjusting parameters such as pitch, speed, and emotion. The platform supports English, Korean, and Japanese, with both free and paid plans available. In practice, voice quality is affected by recording quality, text content, and parameter settings. Multilingual output should also be auditioned and proofread individually.038.2
 Fish AudioAI Audio ToolsFish Audio is an AI audio tool primarily used for text-to-speech and voice cloning. Users can submit a short audio sample to create a digital voice model, then convert text into speech. The platform also provides a real-time speech synthesis API, a community voice library, and controls for emotion, speaking rate, pitch, and volume. It is suitable for content creators producing narration, spoken content, and video voiceovers, as well as businesses, developers, and educators building voice applications or creating course audio. The platform offers both free and paid plans. Actual generation quality depends on sample clarity, text expression, and the use case; before using someone else’s voice, users should also confirm the applicable authorization.038.6
 Mubert AIAI Audio ToolsMubert AI is an AI audio tool primarily used to generate background music based on text prompts, moods, styles, scenes, or durations. Content creators can use it for videos, podcasts, and other projects, while developers and brands can explore dynamic soundtracks through the API. Musicians can upload music materials to Mubert Studio. The platform also provides plugins for software such as Adobe Premiere Pro and Adobe After Effects to support certain creative workflows. When using it, prompts and durations should be adjusted to meet project requirements; the specific licensing scope should be confirmed based on the selected plan and publication context.038.1
 Copilot LabsAI Audio ToolsCopilot Labs is Microsoft's AI experimental platform. Its Audio Expression project is designed for creators and professionals who produce voice content, using models such as MAI-Voice-1 to turn text into natural-sounding speech. After entering text, users can choose between Emotion, Story, and Script modes, then generate audio with different voice styles. Emotion and Story modes allow AI to refine, restructure, or perform the content, while Script mode focuses on reading the original text more faithfully. Generated audio can be downloaded as an MP3, and current materials indicate that no login is required for downloads. Note that creative modes may alter the wording of the original text, so the content and tone should be reviewed against the script requirements before publication.028.2
 ElevenLabsAI Audio ToolsElevenLabs is an AI audio tool primarily used to convert text to speech. It also provides voice cloning, video and audio dubbing and translation, voice design, and AI voice agents. Users can enter text, upload audio samples, or process existing media on the platform, then export voice content or connect its voice capabilities to their own applications through an API. It is suitable for video creators, podcasters and audiobook producers, game and animation teams, educators and trainers, and developers and businesses that need voice interaction features. The platform offers both free and paid plans. When using voice cloning or dubbing features, confirm the permissions for the audio samples, a person's voice, and related content beforehand, and manually review the generated results.048.2
 SongSens.aiAI Audio ToolsSongSens.ai is an AI audio tool designed around learning through foreign-language songs. It primarily serves language learners, while also supporting music reviewers, cultural researchers, and cover artists. Users can start with a song or its lyrics to view contextual analysis, word-by-word explanations, pronunciation guidance, and memory quizzes, while listening to and understanding the lyrics through an integrated player. By using songs as language input, it helps users encounter vocabulary, expressions, and cultural information in context. Existing information mentions connections with players such as Apple Music, but does not specify the full range of supported players, the number of languages, or detailed pricing rules. Metaphors, dialects, and cultural references in lyrics may still require users to verify the interpretation against the original text and other sources.047.8
 Yinshu AIAI Audio ToolsYinshu AI is an AI music creation and sharing platform for Chinese users, covering the workflow from written inspiration and lyric generation to song output and community publishing. Users can define a theme and style through text descriptions, then select a vocal style and generate a complete song with melody, arrangement, and vocals. When further production is needed, they can export Stem tracks for mixing. The product serves music creators, short-video and podcast music producers, brands, and audio enthusiasts. It is also suitable for people without music theory training who want to express their emotions. The platform offers both free and paid usage options. Note that the actual effect of generated results, usage rights, and copyright registration should remain subject to the platform’s rules and the specific use case.068.4
 WhisperAI Audio ToolsWhisper is an automatic speech recognition system developed by OpenAI for audio transcription, speech translation, and content organization. Users can provide audio as input to obtain a corresponding transcript and view timestamps by word or sentence; some non-English speech can also be translated directly into English text. It was trained on 680,000 hours of supervised data covering multiple languages and tasks. The model and code are openly available, making it suitable for developer integration and research testing, as well as for organizing interviews, podcasts, meetings, lessons, and video content. Its recognition results should still be reviewed manually in light of recording quality, accents, and specialized terminology.028.4
 FineVoiceAI Audio ToolsFineVoice is an AI audio creation platform that brings together text-to-speech, voice cloning, real-time voice conversion, speech-to-text, and AI sound effect generation. Users can start with text or audio materials, select or design a voice, adjust parameters such as speed and emotion, and then use the results in videos, podcasts, courses, games, and marketing content. Platform materials indicate support for multiple languages and accents, along with free and paid plans. It is suitable for individual creators, education teams, game and animation developers, and businesses that need voiceovers, transcription, or sound effect assets. Actual results may be affected by the wording of the text, language support, and the quality of the input audio. Relevant authorization should also be confirmed before cloning a voice.198.4
 Yin ChongAI Audio ToolsYin Chong is a Chinese AI audio tool for users in China, designed to lower the barrier to getting started with music production and arrangement. Users can work with built-in virtual instruments and effects, enter a melody and use AI to generate accompaniment, or expand their production capabilities through VST and VST3 plugins. Its fully Chinese interface suits music beginners, enthusiasts, teachers and students, and home recording users for classroom practice, music assignments, cover recordings, or simple demo production. It also retains plugin expansion options for more advanced users, though AI-generated accompaniment may still require manual adjustment, and the actual results depend on the input melody and subsequent arrangement.067.7
 BeepThatOutAI Audio ToolsBeepThatOut is an AI audio tool for content creators that scans audio and video for profanity or other words that need to be blocked, then applies muting effects based on user settings. After uploading a file, users can locate words through an interactive transcript, select the masking range and sound effect, and export the processed result. The tool also supports generating SRT subtitles and exporting projects for Adobe Premiere Pro, Final Cut Pro, and DaVinci Resolve. It is suitable for YouTube creators, podcasters, editors, marketing teams, and educators. Automatically detected results should still be reviewed manually, especially for proper nouns, context, and borderline expressions.038.1
 Sounder AIAI Audio ToolsSounder AI is an intelligent analytics platform for long-form audio content such as podcasts. Combining machine learning and natural language processing, it converts audio into structured text and identifies topics and context. Users can first import or process audio, then use transcription, content analysis, brand safety verification, and audience data for content management or ad targeting. It is designed for podcast creators, advertising agencies, audio publishers, and brands, supporting episode organization, advertising environment assessment, and monetization discovery. The platform offers free and paid plans. Audio transcription and sensitive-content detection results should still be reviewed by humans and cannot replace a complete content review process.067.8
 Transync AIAI Audio ToolsTransync AI is an AI audio tool for meetings and in-person conversations. It primarily uses real-time speech recognition and translation to present conversations as side-by-side bilingual subtitles. During use, the product can listen directly to meeting speakers, identify different speakers and languages, and output translated results simultaneously. It can also assist communication through voice playback, and generate meeting minutes and summaries afterward. It is suitable for international sales, global teams, cross-border freelancers, and users who need communication support for studying abroad or business travel. The product supports 60 languages and can be used in meeting scenarios with Zoom, Microsoft Teams, Google Meet, and other platforms. Note that the Premium plan provides 10 hours of side-by-side real-time translation per month; the exact usage limits and payment terms should be confirmed before use.077.6
 PlaudAI Audio ToolsPlaud is an audio tool that combines recording hardware with AI processing, primarily for organizing meetings, interviews, calls, and voice notes. Users can record audio with card-style or clip-style hardware, and add text and images in the app. After recordings are uploaded, the system can generate transcripts, summaries, key points, and mind maps, and supports questions about the recording content. It suits professionals, salespeople, educators, journalists, and content creators who regularly process spoken information. The product offers free and paid plans. Note that transcription and summary results may still be affected by recording quality, environmental noise, and simultaneous speech by multiple people. Important content should be checked against the original recording before use.038.1
 WellSaidAI Audio ToolsWellSaid is an AI audio tool for enterprise teams, primarily used to convert written scripts into voiceovers. The product offers more than 120 AI voices, with voice models created from licensed recordings by professional voice actors. It suits content production workflows for training, marketing, advertising, and product development. Users can select voices, adjust pronunciation, and use a pronunciation library to manage brand names, terminology, and abbreviations. Teams can also manage projects and voice resources in shared workspaces. WellSaid also provides an API and supports use in software such as Adobe Premiere Pro. In practice, complex terminology, tone, and context still require human listening and review.038.1
 SpotScribeAI Audio ToolsSpotScribe is an audio-to-text tool centered on podcast transcription. It supports links from Spotify, Apple Podcasts, YouTube, and TikTok, as well as local audio and video uploads. After pasting a link or uploading media, users can obtain a complete transcript, an AI-generated summary, and answers to questions about the episode. Results can be copied or exported as PDF, DOCX, SRT, or TXT files for use in notes, subtitles, editing, articles, and archives. It is suitable for content creators, podcast operators, researchers, and learners working with interviews, courses, shows, and short-form videos. AI summaries, answers, and transcripts should still be checked against the original audio before formal publication or research citation.077.8
 CleanvoiceAI Audio ToolsCleanvoice is an AI audio cleanup tool for podcasters and audio creators. It is primarily used to remove filler words, background noise, excessive pauses, mouth sounds, and breathing from recordings. After uploading a recording, users can complete an initial cleanup through an automated workflow and process separate tracks from multiple guests. The product also supports generating podcast summaries, chapter notes, and social media promotional copy. It is suitable for podcasts, audiobooks, videos, courses, and meeting recordings, and can also serve as a rough-cut tool for audio engineers. Automatic detection and removal may alter tone, pauses, or the expression of content, so manual review is still required before publication.038.6
 Amadeus CodeAI Audio ToolsAmadeus Code is an AI composition tool for music creators, designed primarily to generate melodic ideas and song drafts. Users can choose a style, rhythm, mood, or chord progression and have the system generate new top-line melodies, then repeatedly review and compare different options. Generated content can be exported as MIDI files for further arranging and editing in a digital audio workstation (DAW). It is suitable for songwriters, independent musicians, video content creators, and music enthusiasts interested in experimenting with AI composition. Use cases include overcoming creative blocks, building song frameworks, and recording initial ideas. It is best understood as a melody-assistance and draft-generation tool rather than a one-click solution for completing an entire song; further manual editing and production are still required.038.5
 Musicfy AIAI Audio ToolsMusicfy AI is an AI audio tool for music creation and audio content production. Users can upload voice samples to create a personal AI voice model for voice conversion and song covers. They can also generate music with melodies and accompaniment from text or emotional descriptions, and convert vocal humming into instrumental sounds. The platform also offers AI singers and music asset libraries, making it suitable for music producers, content creators, social media users, and anyone interested in exploring music creation. It can simplify the process from inspiration to an audio draft, but users should independently confirm the relevant permissions and platform rules before using another person’s voice or publishing generated content.018.4
 JoyCastAI Audio ToolsJoyCast is an AI audio enhancement tool for MacBook, primarily designed to improve voice pickup from the built-in microphone. When used, it works as a system-level audio input: it first applies noise reduction to the microphone audio, which can then be used by video conferencing, livestreaming, or recording software. The materials list use cases including Zoom, Google Meet, Slack, and OBS, making it suitable for entrepreneurs, content creators, and online educators who communicate remotely on a regular basis. The product description states that audio processing is performed locally and that Apple Silicon chips are supported. Note that the available materials focus mainly on the MacBook's built-in microphone and do not specify compatibility with Windows, external microphones, or other devices. Actual noise reduction performance will also depend on the environment and recording conditions.017.3
 MurfAI Audio ToolsMurf is an AI audio creation platform primarily used to convert written scripts into speech and create voiceovers for videos, presentations, and other content. Users can select voices, adjust speaking speed and pauses, then combine synchronized audio and video with background music to complete their projects. The platform also offers voice cloning, voice changing, translation dubbing, and API capabilities. It is suitable for business marketing and training teams, content creators, educators, and developers who need voice interaction features. Murf offers free and paid plans, but specific quotas, voice quality, and feature access depend on the current plan. Human review of generated content is still recommended.038.5
 AI-songAI Audio ToolsAI-song is an AI audio tool designed to turn short descriptions, lyrics, or instrumental ideas into songs. After entering text or lyrics, users can choose styles such as pop, rock, classical, or electronic to generate complete audio lasting up to approximately three minutes and export it in MP3 format. It is suitable for short-video creators, indie game developers, podcast producers, and music enthusiasts without music theory or arranging experience, for creating background music, intros and outros, or personal works. Generation speed and output quality depend on the input and style settings. Before using the results in formal projects, users should listen to and adjust them, and confirm the current licensing terms.047.4
 MusicLMAI Audio ToolsMusicLM is an artificial intelligence model for music generation. It primarily creates music matching a described scene, mood, and style, and also supports stylistic reinterpretation based on melodies that users hum, whistle, or play. Users can enter a music theme, arrangement approach, or timing changes, then receive an audio draft for creative ideation, preliminary scoring, and research testing. Its public materials also describe story mode, long-form generation, and the MusicCaps dataset. In practice, the details, structure, and usability of generated results still require human review, and material licensing and commercial use rights should be confirmed separately.028
 SpotiguessAI Audio ToolsSpotiguess is a personalized Spotify-based song-guessing quiz platform for users who want to test their music memory, organize music-based activities, or take challenges focused on specific artists. Players can choose an artist, playlist, or saved songs as the quiz source, or use AI mode to generate content by theme, then select automatic or manual answering. The platform also offers multiplayer competition. It is suitable for individual Spotify users as well as friend gatherings and review activities in music learning. The actual experience depends on available Spotify data and personal listening history, so how well the questions match a user's tastes varies by account.087.6
 Exemplary AIAI Audio ToolsExemplary AI is an AI audio tool for content creators that also supports video processing. After uploading audio or video, users can generate transcripts and subtitles, then create summaries, blog posts, chapter content, and social media posts from the text, as well as extract short video clips from long-form videos. The tool also supports subtitle translation in more than 120 languages, text-based video editing, and AI conversations about transcript content. It is suitable for podcasters and video creators, journalists, marketers, and educational and training organizations looking to reduce repetitive work between recording and creating publishable content. Transcription, translation, and automatically generated results still require human review, especially for technical terms, proper nouns, and contextual expressions.138.9
 Xingzhe AIAI Audio ToolsXingzhe AI is an AI audio tool for the gaming and entertainment industries, with broader capabilities related to content production. Users can create lyrics, compose music, synthesize vocals, and produce background music, while combining the platform's image generation, AI agent, and content safety capabilities to support parts of gaming and entertainment content workflows. The product is suitable for game development teams, music educators, independent creators, and entertainment operations staff, covering scenarios such as music production, teaching assistance, and promotional asset preparation. The platform offers both free and paid plans, and specific features may vary by version or service scope. AI-generated content still requires human review, along with compliance and copyright checks based on actual publishing requirements.087.8
 boomyAI Audio Toolsboomy is an AI music generation tool with free and paid plans, designed for everyday users without music theory experience, content creators, independent musicians, and game developers. Users can first choose a music style, have the system generate a song, and then adjust the drums, bass, melody, rhythm, and structure. They can also add recorded or uploaded vocals. Once completed, works can be distributed through the platform to streaming services such as Spotify and Apple Music. It is suitable for quickly producing background music, inspiration drafts, or personal singles, but generated results still require human listening and editing. Specific distribution eligibility, licensing scope, and revenue rules should be determined by the applicable platforms and service terms.027.4
 VideoSDKAI Audio ToolsVideoSDK is real-time audio, video, and AI voice communication infrastructure for developers. It provides cross-platform SDKs and REST APIs to help teams integrate video calling, audio calling, interactive live streaming, real-time transcription, recording, and AI voice agents into websites, mobile apps, or other software products. It supports development environments including JavaScript, React, React Native, Android, iOS, Flutter, Unity, and Python, and can connect to SIP phone systems. The product is suitable for online education, telehealth, video identity verification, live commerce, virtual events, and voice customer service. Users need development expertise, and implementing the features still requires handling business workflows, permissions, and end-user experiences.047.9
 Mix AudioAI Audio ToolsMix Audio is an AI audio tool for music creators, podcasters, audio beginners, and educators. It combines automatic mixing, audio editing, and music generation capabilities. Users can import or provide text, images, audio, and other materials, use AI to adjust volume, equalization, dynamic compression, and effects, or generate background music and remixes before applying presets for further processing. The tool also supports online collaboration for multiple users, making it suitable for personal creation, content production, and audio education. Both free and paid plans are available, but automated results should still be auditioned and adjusted based on the specific source material.038.5
 DeepBeatAI Audio ToolsDeepBeat is an AI audio tool for rap creation, originating from an academic project by Finnish researchers. It primarily uses machine learning to generate lyrics and provide rhyming suggestions. Users can enter keywords to generate complete verses with one click, or choose to receive the next line or a rhyming line suggestion one line at a time. When available, users can enable deep learning mode to try to improve the logic and storytelling of the lyrics. It is suitable for rap enthusiasts, creators, music producers, and writers seeking rhyming inspiration. The tool is currently available for free, but generated content still requires manual editing based on the theme, rhythm, and personal expression, and should not be treated directly as final lyrics.028.5
 ecrett musicAI Audio Toolsecrett music is an AI audio tool for content creators, designed to generate background music for videos, games, podcasts, advertisements, and independent film projects. Users first select a scene, mood, and music genre, after which the system generates a melody. They can then adjust instruments and musical structure, upload a video to preview how the music fits the visuals, and finally download the audio in WAV format. It is suitable for individual creators and small teams without composition skills who need to produce an initial soundtrack quickly. Favorites and creation history also help organize materials. The product offers free and paid plans. Product materials describe the generated music as royalty-free, but the actual scope of commercial use, licensing terms, and download restrictions should be confirmed under the current service rules.018.2
 Cartesia AIAI Audio ToolsCartesia AI is an AI audio tool designed for real-time voice interaction. Its core capability is converting text into speech with expressive elements such as emotional variation, breathiness, and laughter. Users can test generated results in the Playground or integrate voice capabilities into agents, customer service, games, and other applications through an API or SDK. The platform supports more than 42 languages and offers voice cloning options ranging from instant cloning to professional-grade fine-tuning. It is suitable for developers, enterprises, and content production teams that need low-latency voice feedback. Actual results are still affected by the text, language, emotional settings, and audio sample quality, so testing in the target scenario is recommended before integration.088
 TTS - Text to SpeechAI Audio ToolsTTS - Text to Speech is an online AI audio tool that converts input text into exportable audio files. Powered by Microsoft Azure Speech synthesis technology, it supports Mandarin Chinese, selected dialects, and multiple foreign languages, while offering settings for voice roles, emotional styles, pauses, and polyphonic characters. Users can enter or organize text on the web, adjust voice parameters as needed, and generate MP3 or WAV audio. It is suitable for film and TV narration, short-video voiceovers, foreign-language learning, and long-text reading. When working with dialects, proper nouns, or complex emotional expressions, the generated result still requires listening review and manual proofreading.087.3
 CurseCutAI Audio ToolsCurseCut is an AI tool for reviewing audio and video content. It automatically detects inappropriate speech in media and, according to user settings, mutes it, inserts a beep, or replaces it with a custom sound effect. Users can create a filter word list, choose a processing method, and import one or more files for processing, then review the results using a timestamped transcript. The tool supports more than 30 languages and is suitable for content creators, parents and educators, businesses, and media teams working with videos, podcasts, livestream recordings, and training materials. Processing is completed on the local device, and files are not uploaded to the cloud. However, users must define the filtering criteria themselves, and automated results should still be checked before publication or use.038.5
 Azure AI SpeechAI Audio ToolsAzure AI Speech is a cloud AI speech service provided by Microsoft Azure for development teams and enterprise users who need to integrate speech capabilities into applications or business processes. Through APIs or SDKs, users can process audio, convert speech to text, translate content, or synthesize text into speech. The service can also be combined with speaker recognition, pronunciation assessment, and customized models for more specialized tasks. It supports real-time and batch transcription, making it suitable for call centers, media content processing, language learning, and financial, healthcare, and other scenarios. Its capabilities cover a broad range of use cases, but integration still requires API development, model configuration, and performance testing. Available quotas and pricing should be confirmed according to Azure’s current service policies.018.5
 MelodyStudioAI Audio ToolsMelodyStudio is an AI audio tool focused on melody creation, primarily helping users explore singable melodies from lyrics. After users enter or paste lyrics, the tool analyzes the syllable count of each lyric line and generates multiple melodic phrases line by line. Users can then audition and filter the results with chord suggestions, adjust notes and rhythms in a visual editing interface, and finally export the melody and chords as MIDI files. It is suitable for songwriters, producers, singers, and music beginners who want to overcome creative blocks or organize songwriting materials. The generated results still require human judgment and editing, and further arrangement typically requires music production software.038.5
 ResembleAI Audio ToolsResemble is an AI audio tool for enterprises and development teams, covering voice generation, voice cloning, voice conversion, and deepfake detection. Users can provide audio samples to create voice models, then generate content through text-to-speech or speech-to-speech. The platform also supports real-time voice conversion and AI audio editing for recordings. Additional capabilities include multilingual localization and AI watermarking, making it suitable for gaming and entertainment, intelligent customer service, app development, advertising, and marketing. Results may vary depending on the quality of the audio samples, the target language, and the specific use case. When using another person’s voice, users must also confirm authorization and compliance requirements.037.3
 SoundfulAI Audio ToolsSoundful is an AI audio tool that combines music generation with a music library to provide background music assets. Users can first choose a genre, tempo, mood, or theme, then generate tracks and download or continue editing them as needed. The platform also includes AI music shared by music creators. Its content covers styles such as EDM, Deep House, and Hip Hop, making it suitable for content creators, music producers, brands and businesses, and individual enthusiasts for videos, podcasts, livestreams, advertisements, games, or personal projects. Some plans support audio downloads in formats such as MP3 and WAV, as well as further production capabilities including STEM stems and MIDI files. The platform offers free and paid plans, and specific download rights and available features may vary by plan. The applicable licensing terms should be checked before official commercial use.058
 DubbingX Zhisheng YunpeiAI Audio ToolsDubbingX Zhisheng Yunpei is an AI audio tool primarily designed for text-to-speech voiceovers, voice cloning, and speech or singing voice conversion. Users can enter text, select voices and emotions, and further adjust parameters such as speech rate, intonation, polyphonic character pronunciation, and pauses through the web app, desktop client, Mac app, or WeChat mini program. Businesses can also access these capabilities through an API. The product is designed for game, animation, film and television, short-form drama, audiobook, podcast, virtual human, smart hardware, and advertising content production scenarios. The platform offers free and paid plans. According to the official description, its official voices have been licensed for commercial use; when cloning voices from self-uploaded audio, users must still verify the sample source and obtain the necessary permissions.048.5
 MuseNetAI Audio ToolsMuseNet is an AI music generation model developed by OpenAI. Based on the Transformer architecture, it learns from a large collection of MIDI files to generate compositions with variations in harmony, rhythm, and style. Users can listen to pre-generated combinations in Simple mode or start with a single note in Advanced mode and gradually guide the model to complete a musical passage. The tool supports the imitation and fusion of various classical, pop, and other common genres, and allows users to specify ensembles of up to 10 instruments. It is suitable for music creators, composers for visual media, educators, researchers, and music enthusiasts for exploring ideas, assisting with arrangement, teaching demonstrations, and drafting background music. Generated content still requires human selection and refinement and cannot replace the complete composition, arrangement, and production workflow.048.1
 NeverCapAI Audio ToolsNeverCap is an AI audio tool primarily used to convert audio or video into text and translate transcripts into multiple languages. Users can upload files such as MP3 and MP4, process up to 50 files at a time, and handle individual files up to 10 hours long or 5GB in size. Results can be exported as PDF, Word, or SRT files. The tool supports recognition of more than 100 languages and can translate content into 249 written languages. It also provides speaker identification, punctuation, and paragraph formatting. It is suitable for podcast production, video subtitling, interview transcription, academic research, and course recording. Actual results may still be affected by accents, noise, overlapping speech, and specialized terminology, so important content should be proofread before export.087.5
 DiffRhythmAI Audio ToolsDiffRhythm is an AI song generation model developed by the ASLP Lab at Northwestern Polytechnical University. It uses a latent diffusion model and is designed for creators and developers who need to quickly produce music demos, background music, or conduct model research. After users provide lyrics and style prompts, the tool can generate complete songs with vocals and accompaniment, with a maximum generation length of approximately 4 minutes and 45 seconds per run. It supports songs in Chinese and English. The project provides open-source models and inference code, making it suitable for experimentation, research, and further development. Generated results may still require manual selection, editing, or post-production, and the actual output is also affected by the lyrics and style prompts.018.5
 SAM AudioAI Audio ToolsSAM Audio is an AI audio separation tool from Meta for extracting specified sound sources from mixed recordings or video audio. Users can enter a natural-language description of the target sound, click the relevant object in a video, or mark the time range to process, then obtain the corresponding separated result. It is suited to video creators, music producers, podcasters and other audio-content creators, as well as researchers working on audio understanding, for extracting vocals, instruments, ambient sounds, and other specific sounds. The product is currently listed as free and operational. Actual results are affected by the recording environment, the degree of overlap between sound sources, and the accuracy of the prompt description. Complex material still requires manual review and post-processing.038.4
 Wanxiang AudioAI Audio ToolsWanxiang Audio is an AI-powered audio tool for audio content creators, covering script editing, voice recording, audio editing, dialogue synchronization, and final audio review. Users can organize long-form text into chapters, extract characters and generate character profiles, then complete audio production with the recording and editing workstation before using the review feature to check consistency between the audio and manuscript. The platform is suitable for audio production studios, podcast and self-media creators, MCN agencies, and radio drama enthusiasts. It supports both machine-generated production and workflows involving human participation. Some content still requires manual review, especially character delivery, emotional expression, pronunciation of uncommon characters, and the overall quality of the final product.058.1
 TopMediaiAI Audio ToolsTopMediai is an AI audio tool primarily used for text-to-speech conversion, music generation, voice cloning, and AI song covers. It also offers video generation capabilities. Users can start with text, lyrics, or creative descriptions, choose voice or music effects, and generate voiceovers, songs, and other multimedia assets. The platform is designed for video creators, game developers, marketers, podcast producers, educators, and more. Available information indicates that it supports both free and paid use and is currently operational. Final outputs still require human review for pronunciation, emotion, and content suitability. When using voice cloning, song covers, or publishing generated content, users should confirm the relevant permissions.028
 Online AudioAI Audio ToolsOnline Audio is a browser-based online audio conversion tool for individuals, content creators, and office users who need to process audio and video files. After uploading files, users can select an output format, adjust parameters such as bitrate, sample rate, and channels, and download the converted results. Multiple files can be processed at once and packaged as a ZIP. The tool supports more than 300 file formats, can extract audio tracks from videos, and also provides tag editing and some audio effects. It is suitable for handling format incompatibility, organizing media, and performing simple audio processing tasks. Because files must be uploaded for web-based processing, users should plan their workflow according to their network conditions and file sizes.027.3
 Lyria2AI Audio ToolsLyria2 is an AI music generation model from Google DeepMind for music producers, composers, developers, content creators, and music enthusiasts. Users can provide lyrics or text prompts and set parameters such as tempo, key, instruments, mood, and structural elements including intros and outros to generate songs with instrumentation and vocals. Developers can also use the Lyria RealTime API to generate continuous music streams. Generated audio is 48 kHz stereo and includes a built-in SynthID watermark. It is suitable for exploring ideas, creating song demos, scoring videos, and prototyping applications, but outputs still require human review and post-production, especially for lyrical expression, arrangement details, and vocal effects.047.7
 NarakeetAI Audio ToolsNarakeet is an online AI audio tool that converts text, documents, or slides into narrated videos and audio. Users can enter a script directly or upload files such as PowerPoint and Google Slides presentations; the system extracts the content and generates narrated videos, reducing the need for recording and manual synchronization. The product supports 100 languages and more than 900 AI voices, serving educators, trainers, marketers, content creators, and development teams. It can also be integrated into automated workflows through an API. Available information indicates that both free and paid plans are offered; in actual use, pronunciation, tone, timing, and the final output should still be reviewed.057.8
 Dou Ge VoiceoverAI Audio ToolsDou Ge Voiceover is an AI audio tool for short-form video creators. It primarily converts written scripts into voiceovers and assists with multi-character dialogue, voice separation, and script extraction. Users can enter or extract script text, select voices, adjust speaking rate, pitch, and emotion, then preview and revise the generated audio. The tool covers scenarios such as story commentary, emotional quotes, advertising voiceovers, online education, and audio content. It also suits individual creators and small teams that need dialects, child voices, or different character voices. The platform offers both free and paid options. In practice, manual listening and proofreading are still recommended for complex contexts, polyphonic characters, and emotional expression.067.6PersonaTalkAI Audio ToolsPersonaTalk is an AI visual dubbing framework designed for video lip synchronization. Users provide a video of a person and target audio, and the system generates a video in which the lip movements match the new audio while attempting to preserve the original person's facial style and speaking characteristics. Its dual-attention facial rendering mechanism processes the lips and other facial regions separately, helping retain visual details such as skin texture and makeup while reducing teeth flicker. The tool is suitable for film and television localization, advertising localization, online education, and digital human development. The available materials do not specify deployment methods, hardware requirements, or output limitations, so the source materials and operating conditions should be evaluated against the project documentation before formal use.038.2
 ListenHubAI Audio ToolsListenHub is an AI audio tool that organizes written content from webpage links, PDFs, Word documents, TXT files, and user-entered ideas into structured podcast scripts, then generates audio in solo narration or two-person dialogue formats. The platform also offers video storybook generation, making it suitable for knowledge creators, independent media producers, professionals, students, auditory learners, and corporate training and marketing teams. Users typically start by submitting source material, then proceed through content analysis, script generation, and voice performance to create content that can be listened to or shared. It supports both free and paid plans, but generated results should still be manually reviewed and adjusted for source accuracy, wording, and intended use.038.6
 MusicFXAI Audio ToolsMusicFX is an experimental AI audio tool from Google AI Labs. Built on MusicLM, it converts users' text descriptions of styles, moods, or scenes into music clips. Users enter prompts to generate results, or use DJ mode to add multiple prompts and adjust the mixing weight of each description in real time. The tool supports durations of up to 70 seconds and looping, making it suitable for content creators, music enthusiasts, DJs, and developers exploring ideas, drafting background music, and validating concepts. It is primarily designed for clip generation, however, and its short output duration and experimental positioning mean it cannot directly replace complete arranging, production, and post-production workflows. Generated content should still be reviewed according to its intended use.038.5
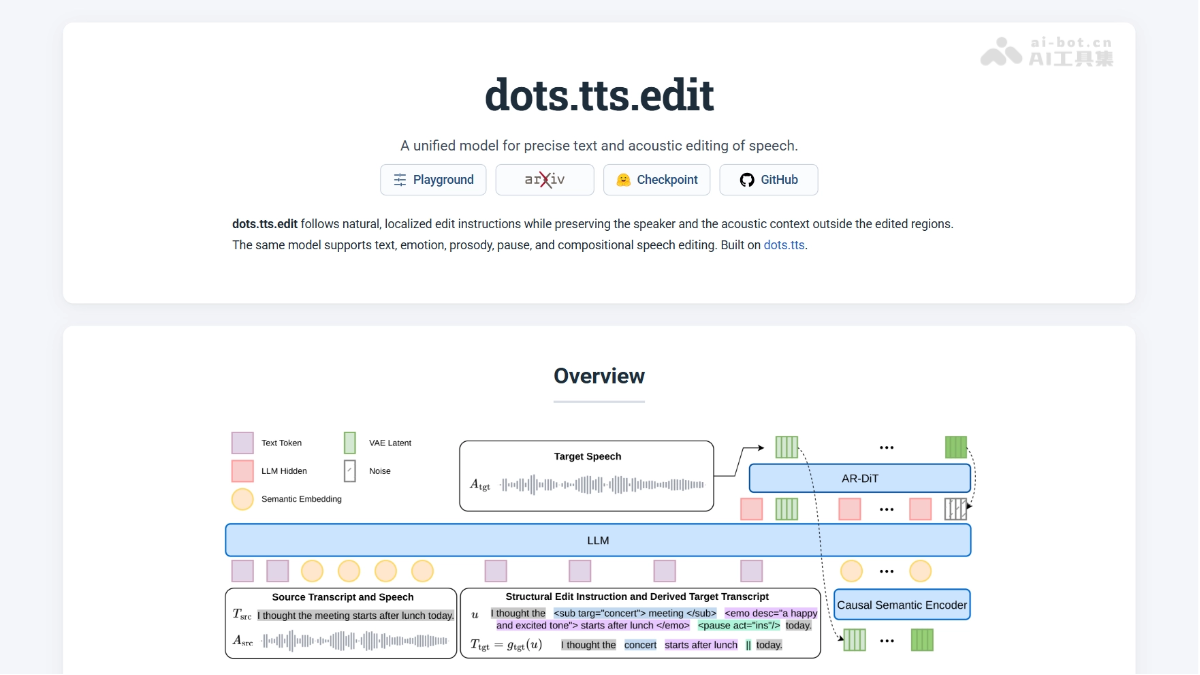 dots.ttsAI Voice Synthesisdots.tts is a 2-billion-parameter fully continuous autoregressive speech synthesis foundation model jointly open-sourced by the Xiaohongshu dots team and the X-LANCE Lab at Shanghai Jiao Tong University. The model directly generates 48kHz audio chunk by chunk in a continuous latent space, achieving SOTA voice similarity and content accuracy on benchmarks such as Seed-TTS-Eval, while supporting zero-shot cloning, streaming output, and low-latency duplex dialogue. ...00
 Hy ASR 3.0 preview – Tencent Hunyuan's Next-Generation Speech Recognition ModelAI Speech RecognitionHy ASR 3.0 preview – Tencent Hunyuan's next-generation speech recognition model is a new-generation speech recognition system based on the Hy3 large language model, combining high-precision speech recognition with deep semantic understanding. It supports Chinese, English, Cantonese, and 10 major dialect regions, with contextual intelligent correction, hotword injection, and robust performance in complex scenarios such as high noise and whispering. WER is kept at around 3% on open-source evaluation sets, while it comprehensively outperforms competitors on in-house evaluation sets. The model is suitable for scenarios including intelligent customer service, content creation, voice search, office collaboration, and smart devices. It can be accessed through the Tencent Cloud API or experienced for free in Tencent Yuanbao.00
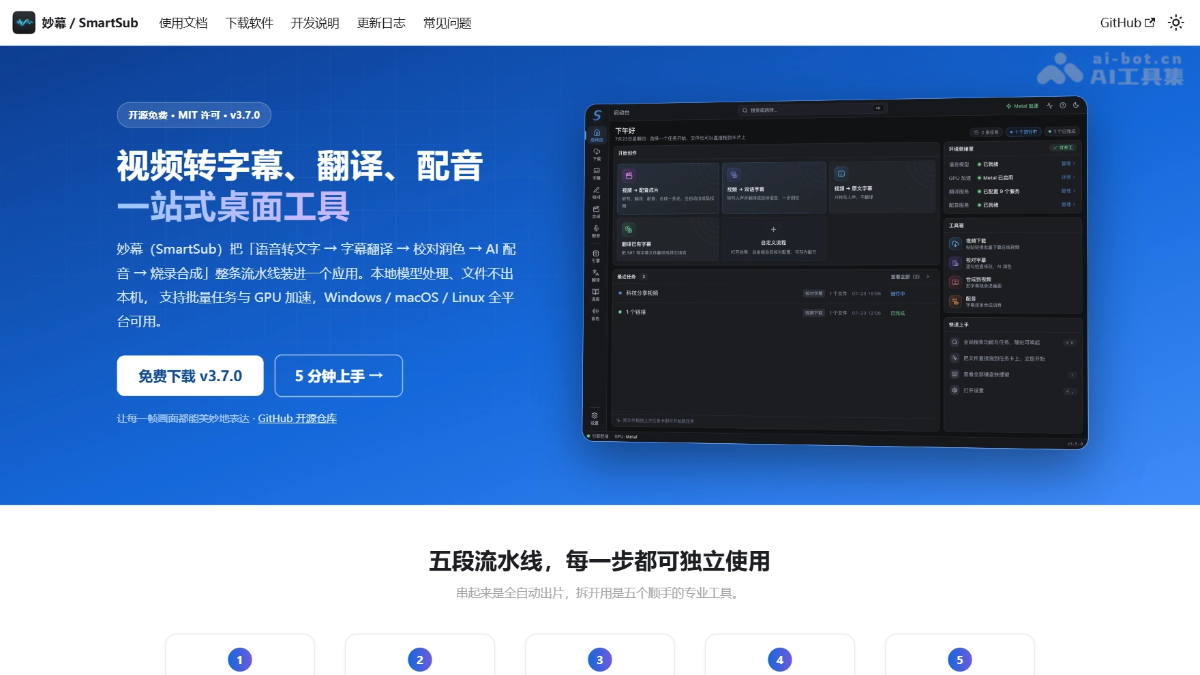 SmartSub – Open-Source All-in-One Desktop Tool for Audio and Video Subtitle ProcessingAI Speech RecognitionSmartSub (妙幕) is an open-source, all-in-one desktop tool for audio and video subtitle processing. It integrates the entire workflow into a single application, using local models such as Whisper, FunASR, and Qwen3-ASR for offline speech-to-text, supporting over 20 translation services and multi-role AI dubbing. It includes a built-in online video downloader compatible with platforms such as Bilibili and YouTube, supports hardware acceleration including NVIDIA CUDA and Apple Core ML, and runs locally across Windows, macOS, and Linux.00
 IndexTTS-2.5AI Voice SynthesisIndexTTS-2.5 is an industrial-grade zero-shot voice cloning model open-sourced by Bilibili. With only 0.8B parameters, it supports cross-lingual transfer across Chinese, English, Japanese, Spanish, and Arabic.00
All tools in this category are shown.