
- Monthly visits
- 0
- Pricing
- Free & Paid
- Listed
- 2026-07-27
- Updated
- 2026-08-25
01Introduction to FLUX 3
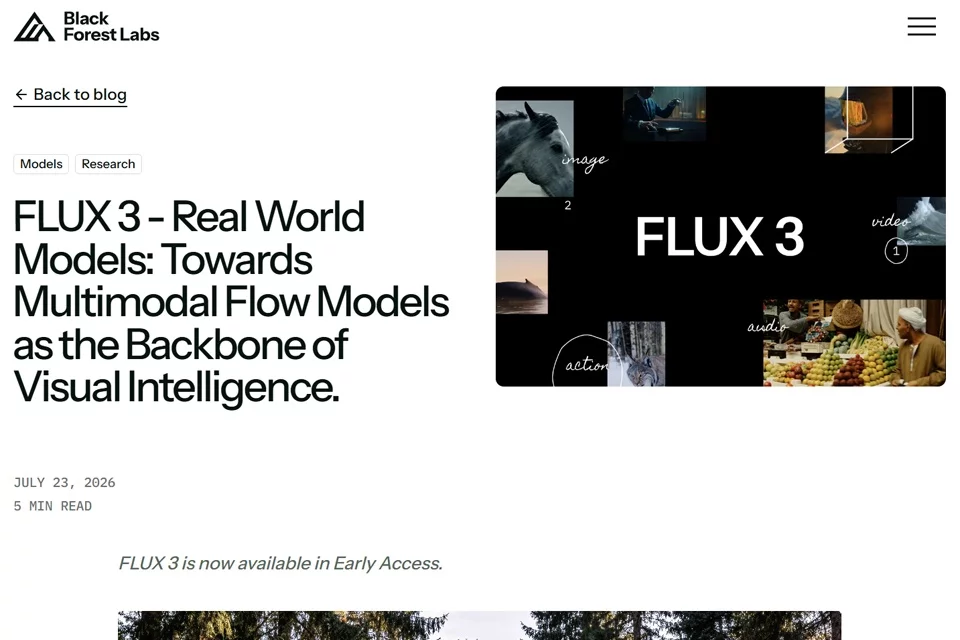
FLUX 3 is not just an image generation tool, but a unified multimodal model that processes images, video, and audio together. It can generate content from text or reference images and videos, and also supports video generation with audio, video editing, and action prediction. The product is currently in Early Access, with video, image, and related model capabilities being gradually opened by the company.
02Who FLUX 3 Is For
Video content creators
Generate videos with native audio from text, image, or video references, and control content changes through keyframes, extensions, and video-to-video transformation.
Image design and editing users
Use the model for image synthesis and editing, handling complex prompts, diverse visual styles, aspect ratios, and multilingual text content.
AI product development teams
Integrate image, video, and audio generation and editing capabilities into content creation or visual intelligence products through the official API.
Selected robotics research and commercial partners
Within the official partnership program, use action prediction and fine-tuning capabilities based on the video backbone model to explore dexterous manipulation and production deployment scenarios.
03Key Features of FLUX 3
Text-to-video generation
Generate videos of up to approximately 20 seconds with native audio from text prompts, suitable for quickly creating dynamic content in different styles and aspect ratios.
Reference image-to-video generation
Generate video from an opening frame or visual reference image, useful for animating images, extending scenes, or preserving the subject's visual characteristics.
Video-to-video
Upload a reference video and carry its core elements into a new setting or context, making it suitable for content reconstruction and style transformation.
Video and audio continuation
Continue generating content from input video and audio so that visual development and sound information extend together.
Keyframe-to-video
Provide multiple defined moments and generate video connecting different states, enabling more controlled scene changes and transitions.
Image synthesis and editing
Generate and modify images from text prompts or reference content, with support for multiple styles, aspect ratios, resolutions, and multilingual text rendering.
Multilingual dialogue generation
Process multilingual dialogue during video generation, combining character expression, visual content, and audio generation in a single video result.
Action prediction
Predict actions based on the model's understanding of the world and dynamic patterns, while supporting exploration of robotic dexterous manipulation tasks through specialized models.
04What Makes FLUX 3 Stand Out
Unified multimodal architecture
The model jointly learns images, video, and audio within one architecture, treating information from different sensors as complementary evidence of the same reality.
Native audio generation for video
Generated videos include native audio, connecting sounds with physical events in the scene rather than producing silent visuals alone.
Bridging content and action capabilities
The same multimodal backbone supports both content creation and action prediction, providing a shared foundation for video understanding, dynamic modeling, and physical intelligence research.
Continuous multi-shot creation
According to the official introduction, intelligent agents can connect independent clips into longer multi-shot sequences, while visual references help maintain character consistency.
05Sources
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0