
- Monthly visits
- 0
- Pricing
- Free
- Listed
- 2026-04-17
- Updated
- 2026-08-25
01Product Positioning
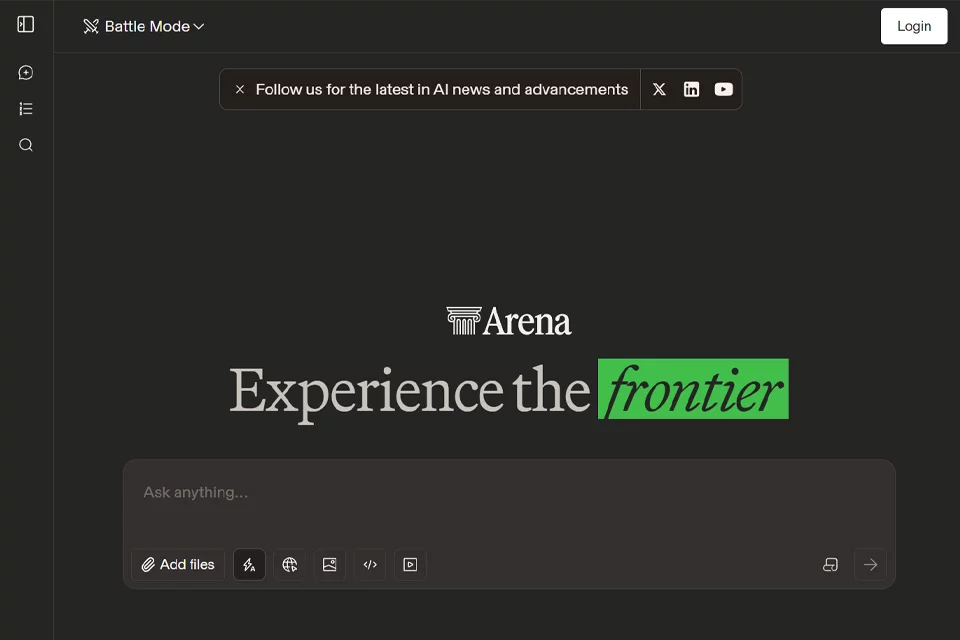
Arena AI combines large language model chat, anonymous evaluation, and model rankings on a single platform. Users observe how different models respond to real questions and provide feedback on their preferences through voting.
It is better suited as an entry point for cross-model comparison and exploration than as a universal benchmark covering every task type. The platform currently uses a primarily free-access pricing model.
02Key Features
The platform offers anonymous blind-test battles: two models answer a question simultaneously, and users vote before viewing the models' identities. Users can also select two models for a side-by-side comparison, making it easy to observe differences in their responses to the same prompt.
Arena AI also supports single-model chat. The platform uses Elo ratings to update model rankings based on conversation votes. The leaderboard reflects relative performance within the platform.
03Use Cases
Algorithm researchers can use anonymous battle results as a reference for observing model preferences and evaluating models. Prompt engineers can compare how different instructions affect model responses. Technology content creators can test multiple models with the same question and produce comparative content.
For general users and technology enthusiasts, the platform is also a convenient way to experience differences in the response styles and capabilities of various models without having to find separate entry points for each one.
04Important Considerations
Model rankings depend on user votes and the question samples used on the platform. Results may change based on topics, language, participant composition, and time. A high leaderboard position does not mean a model is more suitable for every professional task.
For formal model selection, users should still conduct separate tests with data, prompts, and evaluation criteria that match their actual business needs, while considering response accuracy, consistency, and the model's specific areas of applicability.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0