
- Monthly visits
- 0
- Pricing
- Not set
- Listed
- —
- Updated
- 2026-09-15
01What Is HiDream-O1-Video-1.0
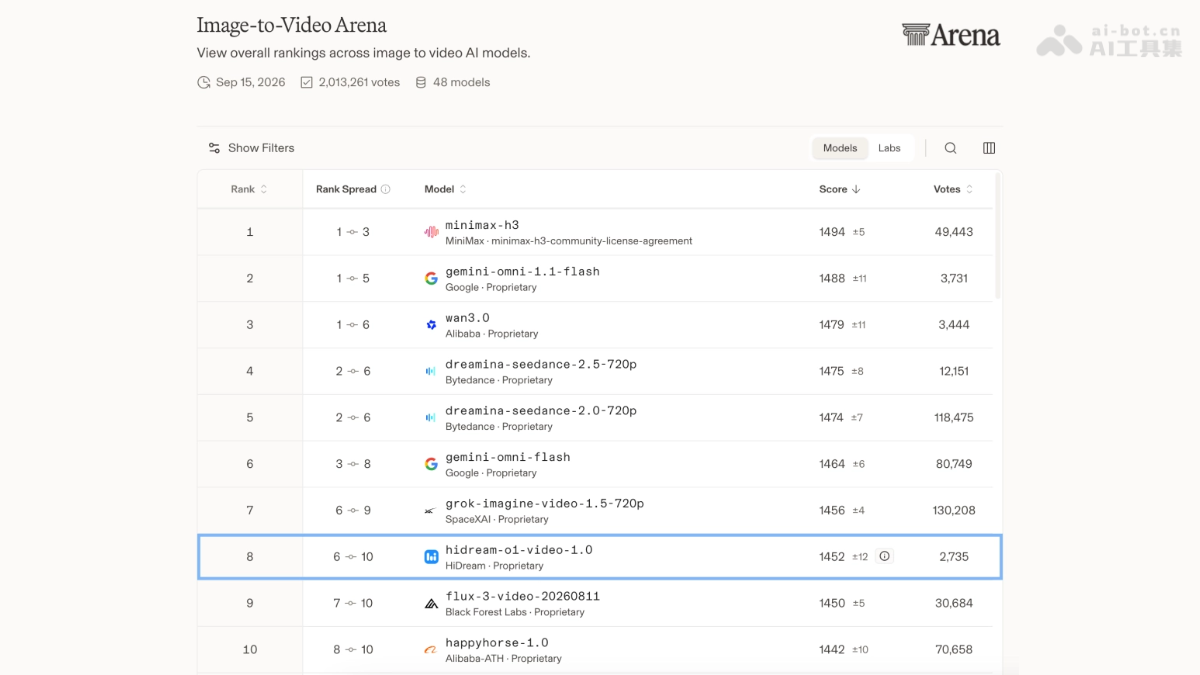
HiDream-O1-Video-1.0 (abbreviated as HD-V1) is a native multimodal video generation model developed by HiDream.ai. It supports multimodal inputs including text, images, and videos, and can generate 5–20-second 1080p videos with a single click. With physics-guided generation and native audio-visual integration, the model ranks fourth globally on the Artificial Analysis image-to-video leaderboard (With Audio) and eighth on the Arena.ai blind evaluation leaderboard, marking the entry of Chinese AI video into the global top tier.
02Key Features of HiDream-O1-Video-1.0
Multimodal input: Supports text, images, videos, and other modalities as generation conditions.
High-fidelity video output: Generate high-quality 1080p videos of 5–20 seconds with one click.
Intent understanding: A multimodal understanding module structures conversational input into professional plans covering shots, characters, actions, sound effects, and more.
Physics-based generation: Physical principles such as gravity, collisions, and inertia are incorporated into the generation logic, ensuring that deformations and movements align with the real world.
Intelligent duration planning: Automatically determines video length based on event logic and narrative pacing instead of mechanically filling a fixed window.
Integrated audio and visuals: Jointly models text, video, and audio signals to achieve native synchronization of lip movements, sound effects, and visuals.
Narrative and character consistency: Uses a plan-first, joint-generation, and Reward-alignment workflow to maintain coherent long-shot narratives and prevent character drift.
03Technical Principles of HiDream-O1-Video-1.0
Native unified multimodal architecture: HD-V1 adopts Zhipu AI's self-developed native multimodal architecture. From the outset, its design has targeted unified representations of text, video, and audio, jointly modeling, mutually constraining, and aligning all three within the same generation process. Visual motion drives the rhythm of sound, dialogue and sound effects feed back into the emotional tone of the shots, and text conditions run throughout.
Upfront multimodal intent-understanding module: The model first uses a multimodal understanding model to deeply interpret and structurally plan the user's input, converting colloquial and ambiguous natural language into professional fields such as shot duration, scene location, characters present, actions and expressions, shot scale and composition, camera movement and focal length, dialogue, and background sound. The deeper the understanding, the more stable the planning; the more stable the planning, the less likely the subsequent joint generation is to drift. This prevents misunderstandings of intent, inconsistent shots, and character drift at the source.
Generation logic grounded in physical laws: How objects fall under gravity, how collisions produce feedback, how inertia continues, how light and shadow decay, and how spatial continuity is maintained.
Three-stage planning-generation-alignment workflow: Zhipu AI proposes a technical approach of planning first, jointly generating next, and then aligning with multimodal rewards. The model first plans the narrative and character states at a global level, constrains visuals, actions, and semantics during joint generation, and uses multimodal reward signals to uniformly align image quality, coherence, and physical plausibility, ensuring overall consistency in long shots as characters, emotions, and motivations influence one another.
04How to Use HiDream-O1-Video-1.0
Confirm availability: The model is currently in closed beta and has not yet been fully released publicly. You need to apply for early access at https://n1y46cmwsp.feishu.cn/share/base/form/shrcnVBeO99NQQWARxNirglcbct.
Scan the QR code to fill out the application form: Press and hold to scan the QR code and open the application form.
Submit your application information: Fill in your personal or business information and intended use as required by the form, then wait for official review.
Wait for the activation notice: After approval, you will receive access to the closed beta.
Experience the model's capabilities: Once approved, use the official entry point to provide text, images, or videos and generate 5–20-second 1080p videos with synchronized audio and visuals in one click.
05Core Advantages of HiDream-O1-Video-1.0
Native multimodal architecture: The industry's first video model to jointly model text, video, and audio signals, enabling native integrated generation of visuals and sound.
Physics-guided generation: Physical laws such as gravity, collisions, inertia, light and shadow attenuation, and spatial continuity are genuinely understood by the model and incorporated into its generation logic. Scene deformation, motion responses, and sound effects all follow realistic causal relationships.
Deep intent understanding: A front-end multimodal intent understanding module structures colloquial and fragmented user input into professional plans covering shot duration, framing, camera movement, actions and expressions, dialogue, sound effects, and more, preventing missed intent and visually inconsistent shots at the source.
Duration follows the narrative: Breaking from the traditional logic of “filling content into a fixed-duration window,” the model autonomously plans duration according to event progression and narrative rhythm, avoiding meaningless pauses or slow motion after an action is completed.
Narrative coherence and character consistency: The model follows a technical approach of planning first, followed by joint generation and multimodal Reward alignment. Combined with Diffusion RL and Reward models aligned with human cognition, this ensures that characters, emotions, and motivations remain coherent and consistent without drifting across continuous shots.
06HiDream-O1-Video-1.0 Use Cases
Advertising and marketing videos: Generate 1080p product videos with synchronized audio and visuals, eliminating post-production voice-over costs. Physically realistic material rendering is well suited to premium product showcases.
Short-form video and social media content: The adaptive 5–20-second duration naturally matches short-video pacing, while conversational prompts can generate finished videos with sound effects and lip synchronization.
Film previsualization and storyboards (Previs): Structurally plan shots, framing, camera movements, and sound effects to help directors quickly validate narrative pacing and visual feasibility before filming.
Dynamic e-commerce product showcases: Generate videos of products in use from product images. Realistic physical motion and synchronized foley enhance conversion rates.
Educational and popular science content: Transform fragmented knowledge points into dynamic demonstrations with accurate physical principles. Synchronized audio and visuals lower the barrier to understanding.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0