
- Monthly visits
- 0
- Pricing
- Free & Paid
- Listed
- 2026-08-13
- Updated
- 2026-08-13
01What is dots.tts
dots.tts is a 2-billion-parameter fully continuous autoregressive speech synthesis foundation model jointly open-sourced by the Xiaohongshu dots team and the X-LANCE Lab at Shanghai Jiao Tong University. The model directly generates 48kHz audio chunk by chunk in a continuous latent space, achieving SOTA voice similarity and content accuracy on benchmarks such as Seed-TTS-Eval, while supporting zero-shot cloning, streaming output, and low-latency duplex dialogue. The project fully open-sources its code and weights, and also extends the precise speech editing capabilities of dots.tts.edit.
02Key features of dots.tts
Zero-shot voice cloning: With only 3–10 seconds of reference audio, the model can reproduce the voice to read any new text, supports cross-lingual cloning, and achieves SOTA content accuracy and speaker similarity on the Seed-TTS-Eval benchmark.
Text-to-speech synthesis: Provides high-quality speech generation ranging from sampling random voices to generating speech from a specified speaker, directly outputting 48 kHz audio based on a 2B-parameter continuous autoregressive model.
Streaming generation and low-latency interaction: Natively supports streaming output, generating audio chunk by chunk as soon as a text prefix is provided; in 1T1A duplex mode, the speech side responds immediately whenever the upstream LLM outputs a text Token, with first audio packet latency as low as 54.4 milliseconds, making it suitable for real-time voice Agents and duplex dialogue.
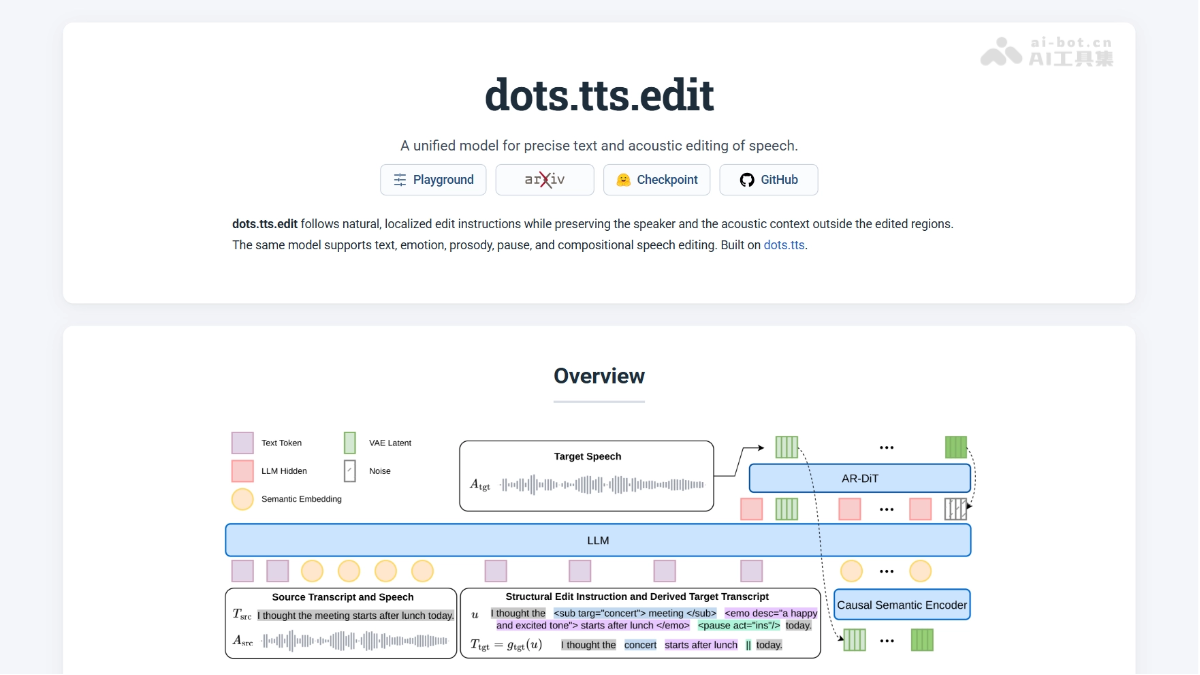
Precise speech editing: Supports text replacement, emotion adjustment, pitch and speech-rate modification, and pause insertion or deletion for existing recordings. Multiple operations can be combined and completed in a single instruction, while unedited regions remain unchanged.
Multilingual support: Covers 24 languages, achieving an average speaker similarity of 83.9 in the MiniMax multilingual evaluation, with 19 languages ranking first individually.
Multiple inference speeds: Provides multiple checkpoints, including Base, SOAR, MeanFlow (4 steps), two-step sCM, and one-step DMD, allowing users to choose between audio quality and inference speed as needed.
03Technical principles of dots.tts
Follow on WeChat and reply “开源” to join the AI open-source project discussion group
Fully continuous autoregressive architecture: dots.tts abandons the conventional approach of quantizing speech into discrete Tokens. The entire generation pipeline runs in a continuous latent space: the model autoregressively predicts acoustic segments chunk by chunk and reconstructs them into 48 kHz waveforms through a BigVGAN-style decoder, fundamentally avoiding the information bottleneck and loss of timbre details caused by discrete quantization.
Semantic continuous representations: The model uses an AudioVAE designed based on HoliTok to compress raw waveforms into continuous latent variables at 25 FPS. Through semantic training, the encoder balances reconstruction fidelity and latent-space structure, achieving a reconstructed speaker similarity of 0.969 and preserving a high ceiling for rich timbre and acoustic details in subsequent autoregressive generation.
Error control mechanism: To address the inherent problem in continuous autoregression where small deviations in earlier steps accumulate and propagate later, dots.tts introduces a causal semantic encoder that compresses generated VAE patches into compact semantic history in real time and feeds it back to the large language model. By stripping away high-variance local acoustic changes and retaining only long-range semantic summaries, it effectively suppresses error propagation, howling, and timbre drift during long-sequence generation.
Generation process: The generation process is centered on a large language model initialized from Qwen2.5-1.5B, which directly consumes BPE text Tokens and outputs hidden states at each step. An autoregressive flow-matching head (an 18-layer DiT) then performs denoising generation of the next acoustic patch based on the LLM hidden states and the autoregressive prefix, while the global x-vector provided by a frozen CAM++ speaker encoder ensures timbre consistency.
Post-training acceleration: Through SOAR self-correcting alignment, the team enables the model to simulate deviations from actual inference during training and learn to self-correct, improving stability without requiring a reward model. MeanFlow distillation compresses the teacher's multi-step trajectory into an average velocity for high-quality 4-step generation; a simplified consistency model (sCM) compresses it to 2 steps; and reward-aware distribution matching distillation (DMD), combined with a dual-time-scale update strategy, produces a natural and clear high-quality one-step model.
04How to use dots.tts
Installation: Run pip install dots.tts to install it, or clone the source code from GitHub and run pip install -e . for a local development installation. In high-concurrency scenarios, SGLang Omni can be additionally deployed to obtain CUDA Graph acceleration and continuous batching support.
Command-line synthesis: Use the dots.tts entry point and specify --model-name-or-path, --text, and the target --prompt-audio and --prompt-text to perform zero-shot voice cloning; omitting --prompt-text falls back to x-vector cloning, while omitting --prompt-audio performs random voice sampling.
Command-line editing: Use the dots.tts.edit entry point and provide --source-audio and an XML-style --instruction to perform precise edits such as text replacement and emotion or prosody modification on existing recordings.
Basic Python API call: Load the model through DotsTtsRuntime.from_pretrained(), then call generate(), passing text and optional reference audio to obtain a synthesized audio tensor and save it as a file.
Python API streaming output: Call generate_stream() to obtain audio tensors chunk by chunk and stream them to a player or WebSocket, enabling a low-latency experience with generation and playback happening simultaneously.
Python API duplex dialogue: Start a session with DotsTtsRuntimeDoubleStreaming, then push text Token by Token. The speech side starts generating immediately, with first audio packet latency as low as 54.4 milliseconds, making it suitable for real-time voice Agents.
Fine-tuning: Run accelerate launch scripts/train_dots_tts.py and configure your own data path to fine-tune the model for voice or domain adaptation based on a public checkpoint.
Distillation acceleration: Use scripts/train_dots_tts_meanflow.py to perform MeanFlow distillation with a SOAR checkpoint as the teacher, obtaining high-quality 4-step, 2-step, or 1-step student models to meet different latency and concurrency requirements.
Web interface: Run python apps/gradio/app.py to launch the visual synthesis interface, or run apps/edit_playground/app.py to launch Edit Playground, where you can upload audio, annotate editing regions, and preview results in real time in a browser.
05Core advantages of dots.tts
Continuous latent-space modeling: Abandoning discrete acoustic Tokens, the model directly generates speech autoregressively in a continuous latent space, preserving rich timbre details such as spectral texture and breathiness, with reconstructed speaker similarity reaching 0.969.
SOTA synthesis quality: Achieves SOTA content accuracy and timbre similarity simultaneously on the Seed-TTS-Eval benchmark, with an average SIM of 83.9 in the 24-language MiniMax evaluation, surpassing mainstream solutions in overall performance.
Native streaming with low latency: In 1T1A duplex mode, first audio packet latency is as low as 54.4 milliseconds. Combined with SGLang Omni, a single H100 GPU achieves throughput of 4.76 req/s with 16 concurrent sessions, meeting the needs of real-time voice Agents.
Unified editing capabilities: Based on the same foundation model, dots.tts.edit supports precise XML-structured editing of text, emotion, prosody, and pauses, leading other open-source systems overall in the doteBench evaluation.
06dots.tts project links
GitHub repository: https://github.com/studio-dots-ai/dots.tts
arXiv technical paper: https://arxiv.org/pdf/2608.02673
07Applications of dots.tts
Real-time voice Agents: With first audio packet latency as low as 54.4 milliseconds in 1T1A duplex mode, it is suitable for LLM-driven real-time duplex dialogue and voice assistants.
Zero-shot voice cloning: Any voice can be reproduced with only a few seconds of reference audio. Cross-lingual cloning is supported, making it suitable for audiobooks, dubbing, and personalized content creation.
Multilingual content generation: Covering 24 languages while maintaining high speaker similarity, it is suitable for multilingual voice broadcasting and localization services for global products.
Precise speech editing: dots.tts.edit can perform text replacement, emotion adjustment, prosody modification, and pause adjustment on existing recordings, making it suitable for podcast post-production and audio content refinement.
Live streaming and real-time broadcasting: Combined with streaming LLM output, it enables generation and playback simultaneously, making it suitable for news broadcasting, live commerce, and real-time information broadcasting scenarios.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0