
Large Models
AIEZZ tool tag
Browsing AI products tagged “Large Models”, with 10 matching results.
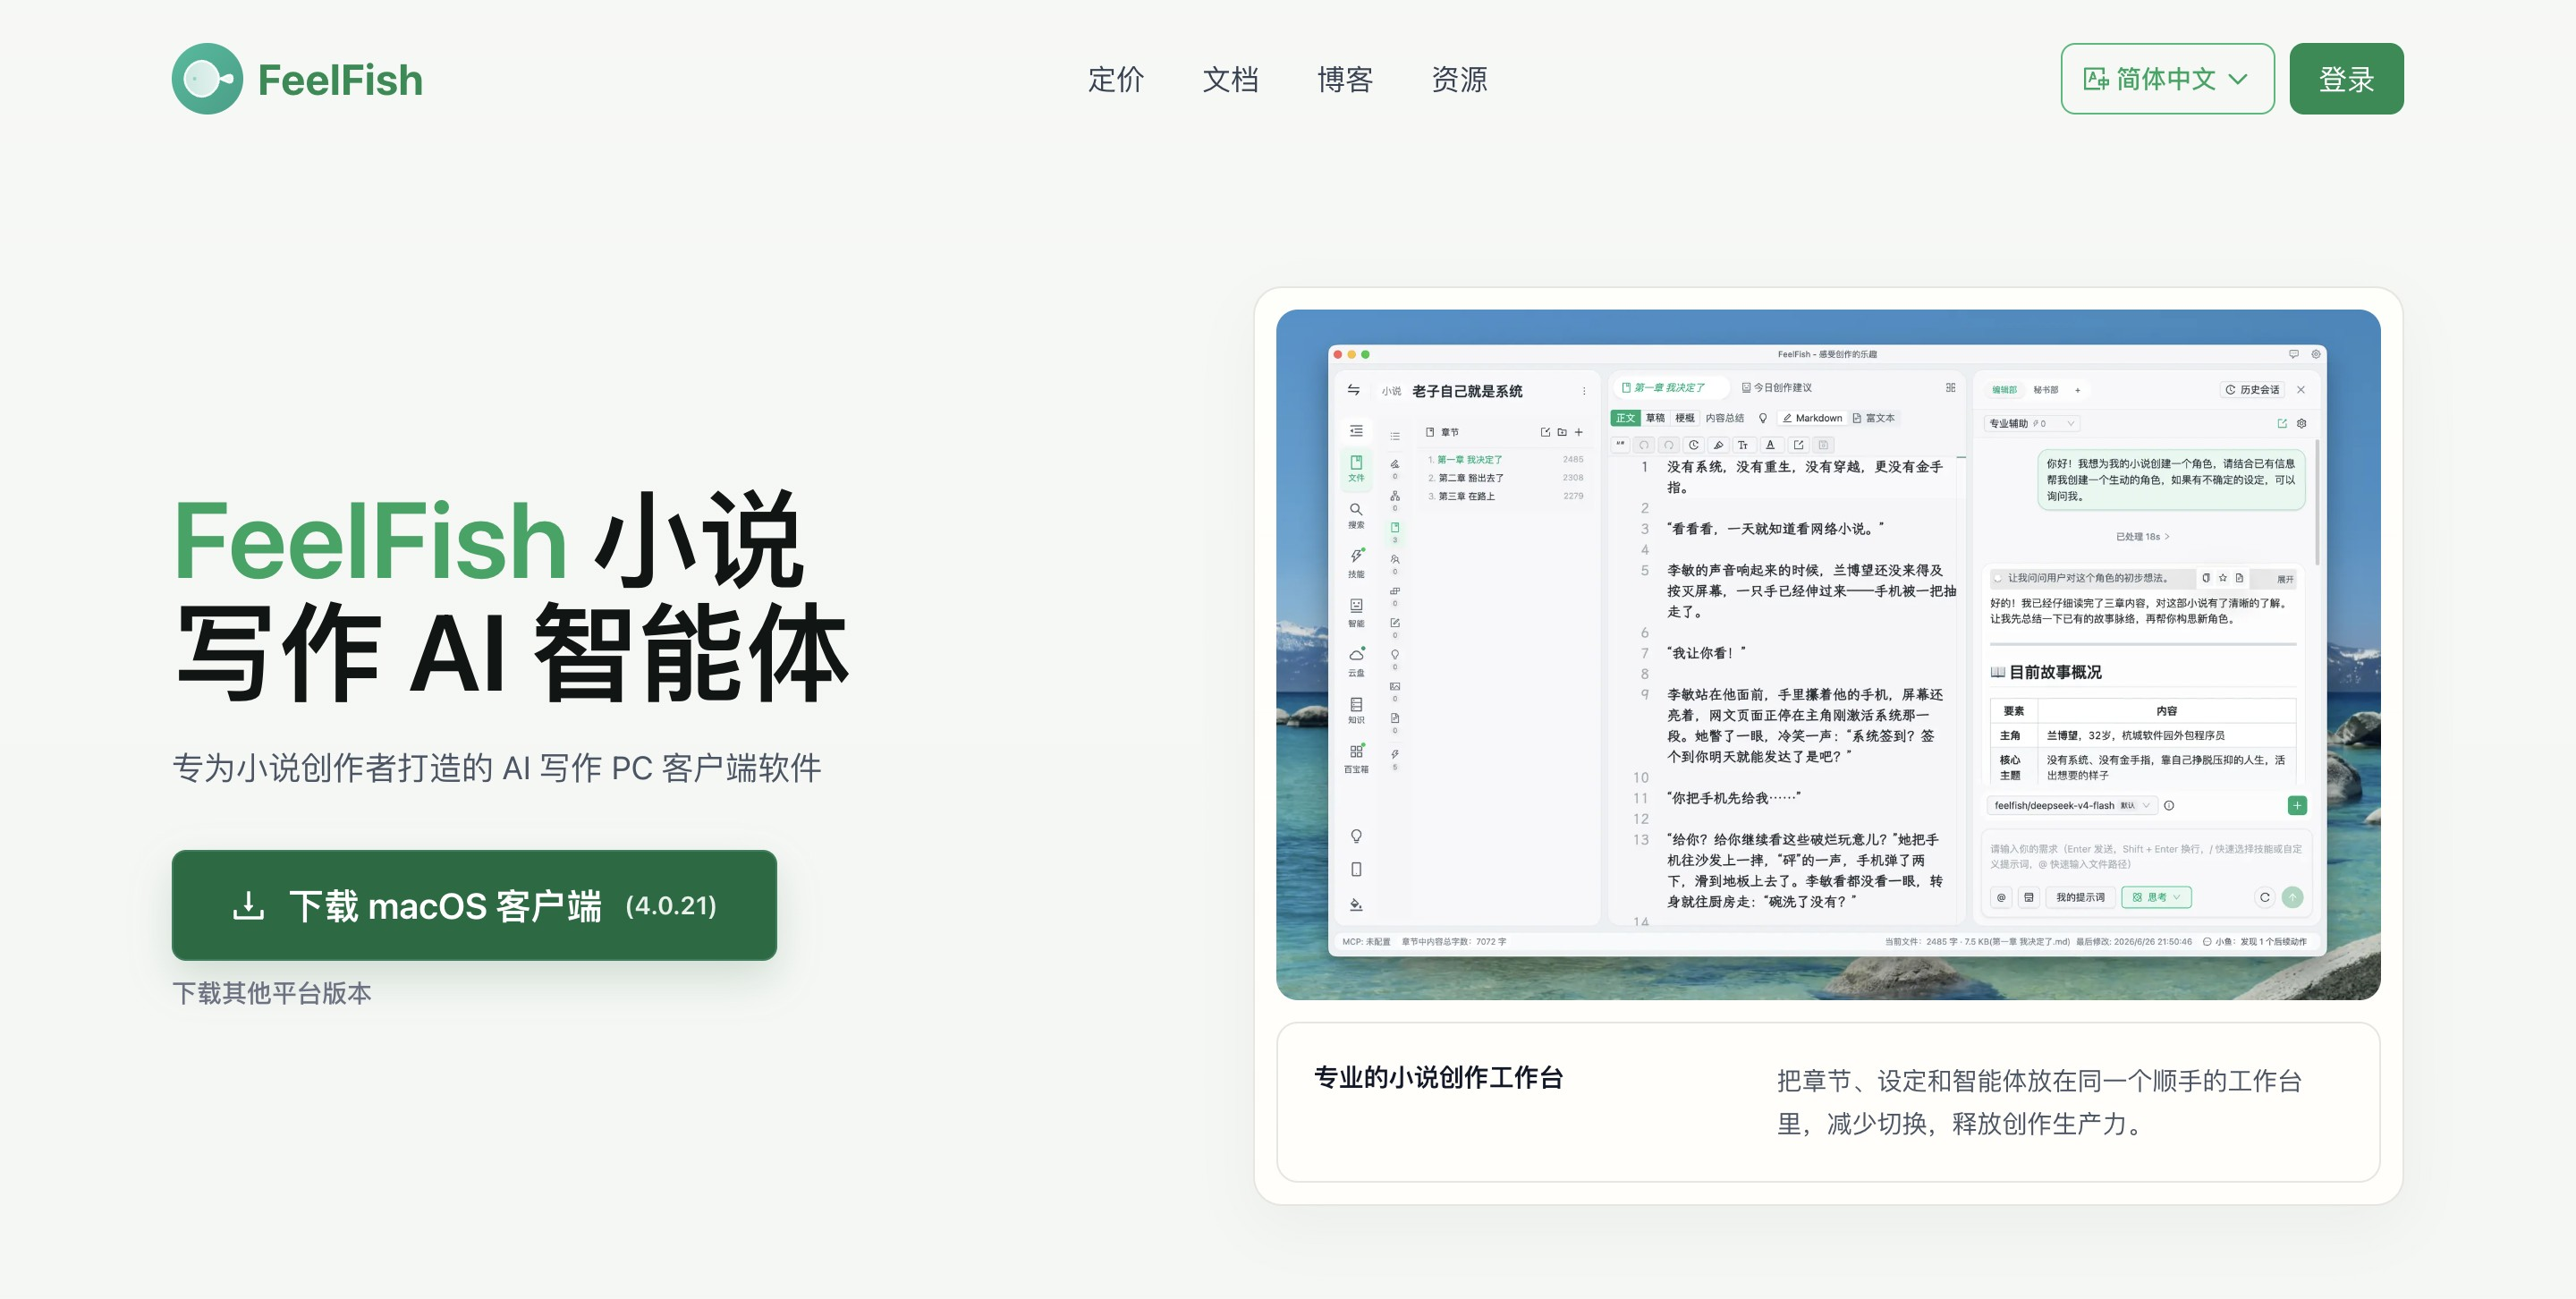 2026 Review of the Latest AI Novel Writing Software: FeelFish 4.0AI ProgrammingFeelFish 4.0 is professional novel writing software that transforms large AI models into a writing team that understands your project. It provides structured project management covering chapters, outlines, characters, and settings, and supports intelligent context to maintain logical consistency in long-form creation. The tool supports customizable multi-agent collaboration, desktop and mobile remote control, and cloud drive synchronization plus a local time machine to ensure manuscript security. It is designed to provide a complete human-AI collaborative workflow for long-form creators of online novels, screenplays, and more.00
 RabbitVis – RabbitPre Intelligence’s All-in-One AI Design and Production ToolImage EditingRabbitVis is a layer-based, all-in-one AI design and production tool launched by RabbitPre Intelligence. Based on its self-developed UniWorld-Design visual foundation model, it deeply integrates AI generation with layer editing. It supports generating professional design content such as posters, e-commerce product detail pages, and magazine spreads through natural language, along with ongoing layer-level editing, including background removal, text modification, element replacement, and transparent asset extraction. The tool is deeply optimized for Chinese-language scenarios and supports high-density layouts featuring complex artistic fonts, interleaved text and images, and infographics. Designed for e-commerce operations, social media operations, brand promotion, content creation, corporate work, and other users, it enables people with no design experience to produce professional-grade visual assets.00
 MemHarness – An Agent Memory Reconstruction Framework by Shanghai AI Lab and OthersAI AgentsMemHarness is an LLM Agent memory reconstruction framework released by Shanghai AI Lab in collaboration with Zhejiang University, Fudan University, Shanghai Jiao Tong University, and other universities. It inserts critique and reconstruction steps between retrieval and action, using the current context to retain, rewrite, or discard historical experiences. It uses GRPO for end-to-end training and requires no additional human annotations. The framework supports the complete workflow of memory retrieval, critique and reconstruction, action generation, experience write-back, and pruning, and provides a five-stage decision-making process. Its 7B-parameter model surpasses Gemini-2.5-Pro by 23.1% and 39.7% on ALFWorld and WebShop, respectively, achieving an average success rate of 85.9% in out-of-distribution scenarios. It is suitable for embodied household tasks, autonomous online shopping, intelligent customer service, code-assisted development, and other scenarios.10
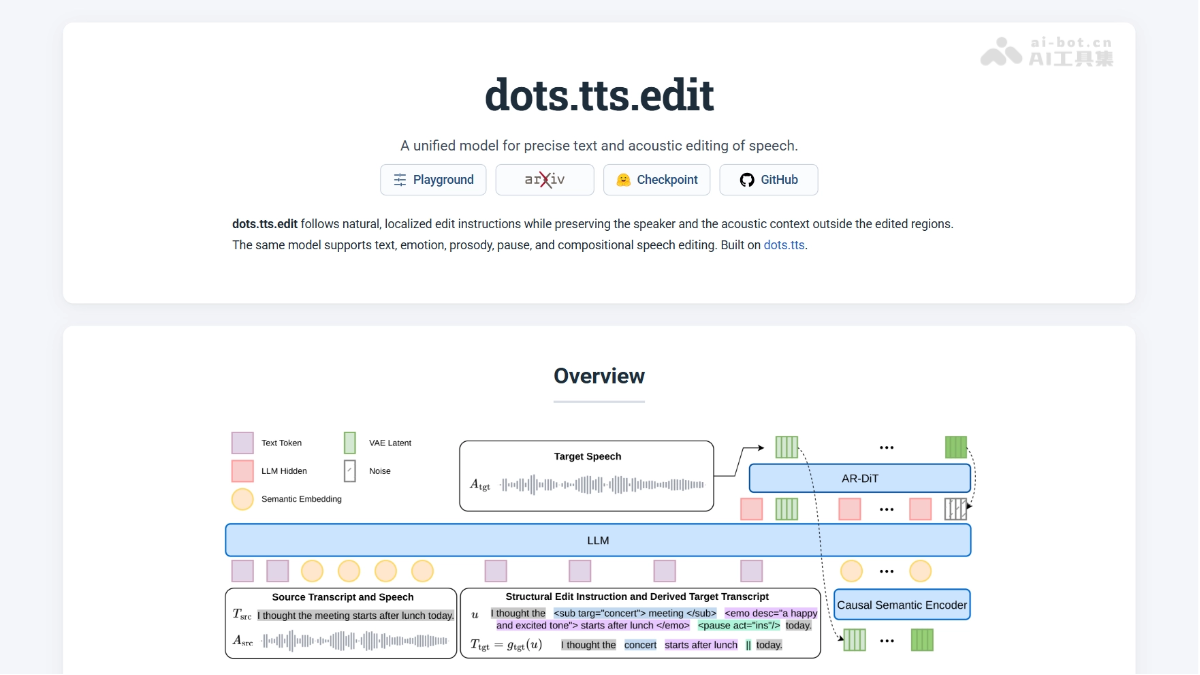 dots.ttsAI Voice Synthesisdots.tts is a 2-billion-parameter fully continuous autoregressive speech synthesis foundation model jointly open-sourced by the Xiaohongshu dots team and the X-LANCE Lab at Shanghai Jiao Tong University. The model directly generates 48kHz audio chunk by chunk in a continuous latent space, achieving SOTA voice similarity and content accuracy on benchmarks such as Seed-TTS-Eval, while supporting zero-shot cloning, streaming output, and low-latency duplex dialogue. ...00
 SeedRealtime – ByteDance’s Native Audio-Visual Full-Duplex Foundation ModelAI Large Language ModelsSeedRealtime – ByteDance’s Native Audio-Visual Full-Duplex Foundation Model is a native audio-visual full-duplex foundation model developed by ByteDance’s Seed team. Built on a unified architecture that natively integrates audio, video, and text, it enables fully multimodal real-time interaction while seeing, listening, and speaking simultaneously. Its core capabilities include joint audio-visual understanding, proactive interaction, smooth conversational pacing, and multi-person scene recognition. It can use visual context to resolve homophone ambiguity, proactively alert users when the scene changes, distinguish side conversations from background noise in noisy environments, and continuously associate each person’s voice with their identity. The model uses end-to-end unified modeling and a native full-duplex interaction mechanism to avoid information loss and accumulated latency in cascaded systems. It is now fully deployed in the Doubao app, becoming the industry’s first audio-visual full-duplex AI product to achieve large-scale deployment.10
 HOMIEAI Video GenerationHOMIE is an open-source digital human video generation framework from the Hong Kong University of Science and Technology, built on the Wan2.1-T2V-14B backbone and integrated with the Qwen3-VL multimodal large language model. The framework uniformly handles four elements—digital humans + products + logos + text—...00
 SenseNova U1.5-Lite-Preview – SenseTime's Open-Source Lightweight Multimodal ModelAI Large Language ModelsSenseNova U1.5-Lite-Preview – SenseTime's open-source lightweight multimodal model is based on the NEO-Unify architecture. With 8B-MoT parameters, it natively unifies visual understanding, reasoning, generation, and editing. The model supports native 4K ultra-high-definition image generation, with fine textures, realistic details, and Chinese and English text rendering in complex layouts. Its built-in Prompt Enhance Skill lowers the barrier to creation, enabling precise execution of long natural-language and structured visual instructions, as well as continuous iterative editing. Designed for designers, developers, and content creators, it provides a commercial-grade visual creation tool with low deployment costs and strong instruction-following capabilities.10
 IndexTTS-2.5AI Voice SynthesisIndexTTS-2.5 is an industrial-grade zero-shot voice cloning model open-sourced by Bilibili. With only 0.8B parameters, it supports cross-lingual transfer across Chinese, English, Japanese, Spanish, and Arabic.00
 MobvoiAI Learning PlatformsMobvoi is a company that provides artificial intelligence products and solutions across content generation, voice interaction, audio transcription, and smart hardware. Users can choose artificial intelligence voice-over, digital human, or video creation tools based on their tasks, or use TicNote for recording, real-time transcription, summaries, and question answering. Its services are suitable for short-video creators, marketing and self-media professionals, office workers who need to organize meeting materials, and businesses exploring digital services. The platform offers both free and paid products. Specific features and usage methods should be reviewed for each product, and generated content and transcription results should be manually checked.018
 Qwen 3.8-Max – The flagship large model launched by Alibaba Cloud’s Qwen teamAI Large Language ModelsQwen 3.8-Max – the flagship large model launched by Alibaba Cloud’s Qwen team, expanding the Qwen 3.5 architecture to 2.4 trillion parameters and positioned as an ultra-large language model for enterprise and research use. It supports long-horizon autonomous coding, paper reproduction, competition practice, workplace productivity, quantitative strategy development, and autonomous chip design. Through real-world reinforcement learning and a self-evolving feedback loop, the model can execute autonomously for days to tens of days and complete complex tasks without human intervention. Users can call it through APIs compatible with the OpenAI or Anthropic protocols on the Qwen AI platform, or deploy its open-source weights locally for easy integration with agent frameworks such as Claude Code, Codex, and Qoder. As a result, professional users in R&D, legal and compliance, design, and other fields can significantly improve productivity, compressing long-cycle projects into deliveries completed within a single conversation.10
All tools with this tag are shown.