
- Monthly visits
- 0
- Pricing
- Not set
- Listed
- —
- Updated
- 2026-09-17
01What Is Spark-Audio-1.0-Preview?
Spark-Audio-1.0-Preview is iFlytek's fully domestically developed foundational speech model, using a 0.65B audio encoder + 30B-A3B MoE language model architecture. It was trained on 13 million hours of audio and extensive text data using entirely domestic computing power. The model directly understands speech semantics, emotions, and contexts, supports recognition of 99 languages and 202 dialects, and performs tasks such as speech transcription, translation, speaker identification, emotion analysis, and audio question answering. It delivers leading performance in complex scenarios such as high noise and low volume, with broad applications in customer service, in-vehicle systems, healthcare, and more.
02Key Features of Spark-Audio-1.0-Preview
Speech transcription: Converts speech directly into text, supporting recognition of 99 languages and 202 dialects.
Multilingual translation: Enables speech-to-speech and speech-to-text cross-language translation while preserving prosodic information such as tone and intonation.
Multi-dialect recognition: Covers 202 dialects, including Cantonese and Wenzhou dialect.
Environmental sound recognition: Understands both human speech and ambient sounds, interpreting the context in which sounds occur.
Speaker identification: Automatically distinguishes who is speaking, making it suitable for meeting transcription, minutes generation, and more.
Emotion analysis: Captures tone and emotion in speech to make interactions more “human.”
Audio question answering: Understands and answers questions based on complex audio content, moving from “hearing clearly” to “understanding.”
03How Spark-Audio-1.0-Preview Works
End-to-end speech understanding architecture: Unlike the traditional cascaded approach of “transcribing speech into text first, then sending it to a large model,” the model combines a 0.65B audio encoder with a 30B-A3B large language model. Text and speech are directly input into the same model as two modalities, enabling it to understand speech, environmental sounds, music, semantics, emotions, and contexts in a single pass while avoiding information loss and error accumulation in cascaded pipelines.
Audio encoder pretraining: The model gradually expands its representational capabilities through audio encoder pretraining, then uses pretraining and post-training to improve its foundational capabilities, generalization in complex scenarios, and multitask performance. It ultimately achieves excellent results in real-world complex scenarios such as high noise and low volume.
Training on entirely domestic computing power: The model was trained on an entirely domestic computing cluster using 13 million hours of audio and extensive text data. It is the industry's first foundational speech model trained on entirely domestic computing power, demonstrating that domestic computing resources can train a speech model at a leading industry level.
Fine-tunable foundation system: Similar to the iFlytek Spark Large Model 1+N system, Spark-Audio can serve as a speech foundation model for further fine-tuning to develop specialized models or systems for speech recognition, simultaneous interpretation, voice interaction, and more, facilitating deployment across various speech-related applications.
04How to Use Spark-Audio-1.0-Preview
Open the official demo page: Visit the model demo URL https://iflytekresearch.iflytek.com/experience/spark-audio .
Try the model's capabilities online: Enter text or speech on the page to experience speech transcription, translation, dialect recognition, audio question answering, and other features.
05Core Advantages of Spark-Audio-1.0-Preview
Training on entirely domestic computing power: The industry's first foundational speech model trained on an entirely domestic computing cluster, demonstrating that domestic computing resources can train a model at a leading industry level.
Direct end-to-end speech understanding: Eliminates the cascaded approach of “transcribe first, understand later,” preserving key information such as tone, emotion, and ambient sounds while reducing pipeline fragmentation, latency, and stuttering.
Broad multilingual and multidialect coverage: Supports recognition of 99 languages and 202 dialects, with superior multilingual and multidialect recognition performance among models of comparable size.
Leading performance in complex scenarios: Shows clear advantages in real-world tasks involving high noise and low volume, with particularly strong noise resistance.
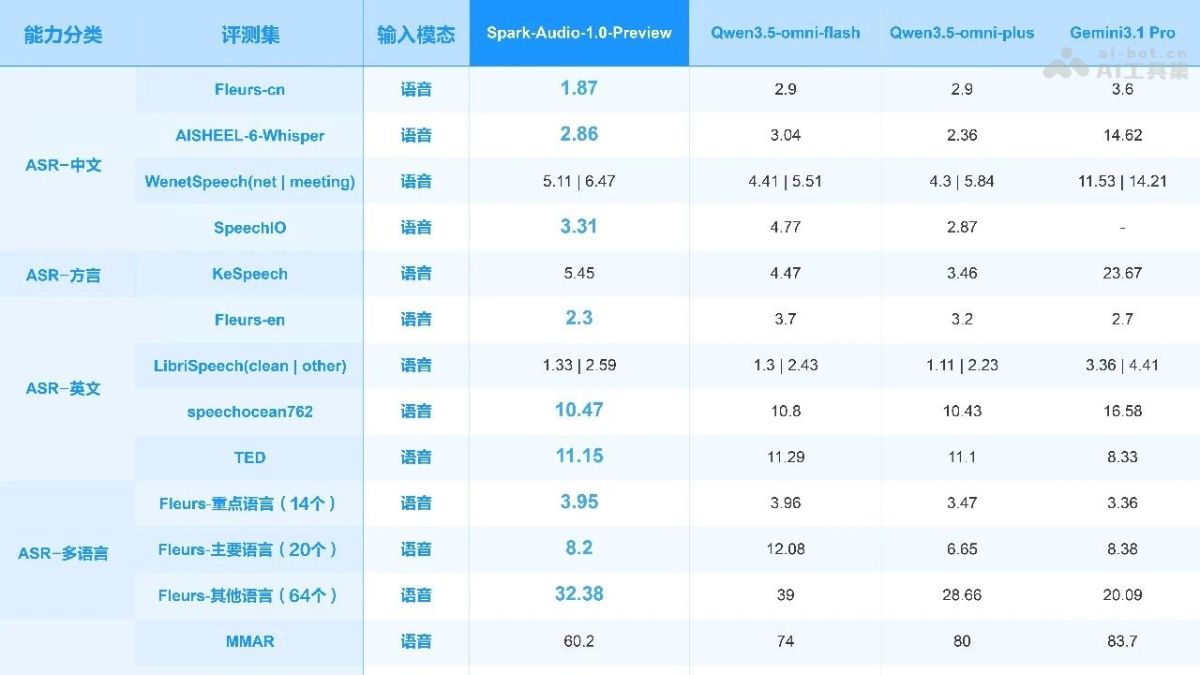
Competitive with much larger models: Delivers results close to Qwen3.5-omni-plus, a model an order of magnitude larger; achieves SOTA on the Chinese Fleurs test set and exceeds Gemini-3.1 Pro in multiple evaluations.
No loss of text capabilities: Shows no significant degradation on text tasks such as general knowledge, mathematics, and coding, overcoming a common challenge for speech foundation models.
Efficient architecture: Uses a 0.65B audio encoder + 30B-A3B MoE architecture to achieve performance close to that of larger closed-source models at a smaller scale.
06Applications of Spark-Audio-1.0-Preview
Intelligent customer service: Recognizes users' emotions and speaking styles to make conversations more coherent and human, improving the service experience.
Automotive cockpits: Accurately recognizes driver commands in noisy in-vehicle environments, supports dialect-based interaction, and delivers a more natural in-car voice experience.
Real-time translation and multilingual meetings: Provides simultaneous interpretation and multilingual translation while preserving prosodic information such as tone and intonation for more natural cross-language communication.
Meeting transcription and minutes generation: Automatically distinguishes speakers, extracts key decisions, and generates structured minutes, reducing repetitive organization work for staff.
Electronic medical records and content review: Uses speech for medical record creation and content review, reducing manual data entry and improving efficiency in professional settings such as healthcare.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0