
- Monthly visits
- 0
- Pricing
- Free & Paid
- Listed
- 2026-08-07
- Updated
- 2026-08-07
01What Is SALMONN-2
SALMONN-2 is a general-purpose audio large language model jointly open-sourced by Tsinghua University, Shanghai Artificial Intelligence Laboratory, and the University of Cambridge. Built on ByteDance's SPEAR unified self-supervised audio encoder and a multi-layer feature fusion adapter, with Qwen3 as its text backbone, it achieves the best performance among open-source models of comparable size on the three comprehensive benchmarks MMAU-Pro, MMAR, and MMSU using only approximately 18,000 hours of supervised data. It is also the first general-purpose ALLM to systematically implement advanced capabilities such as sound event detection, audio deepfake detection, speech quality assessment, and multimodal in-context learning for speech recognition.
02Key Features of SALMONN-2
General-purpose audio understanding: Supports cross-domain tasks including speech recognition, audio captioning, music understanding, emotion recognition, and speaker verification.
Sound event detection (SED): Locates and outputs the start and end time ranges of environmental sound events, such as barking dogs and footsteps.
Audio deepfake detection: Determines whether speech is authentic and locates the time ranges of suspected synthesized or edited segments.
Speech quality assessment (SQA): Perceives low-level acoustic features such as noise, distortion, and clarity, then provides quality scores and explanations.
Multimodal in-context learning for speech recognition (MICL): Combines text spellings with reference pronunciation audio to improve recognition accuracy for uncommon words and rare names.
03How SALMONN-2 Works
Follow the WeChat account and reply with “开源” to join the AI open-source project discussion group.
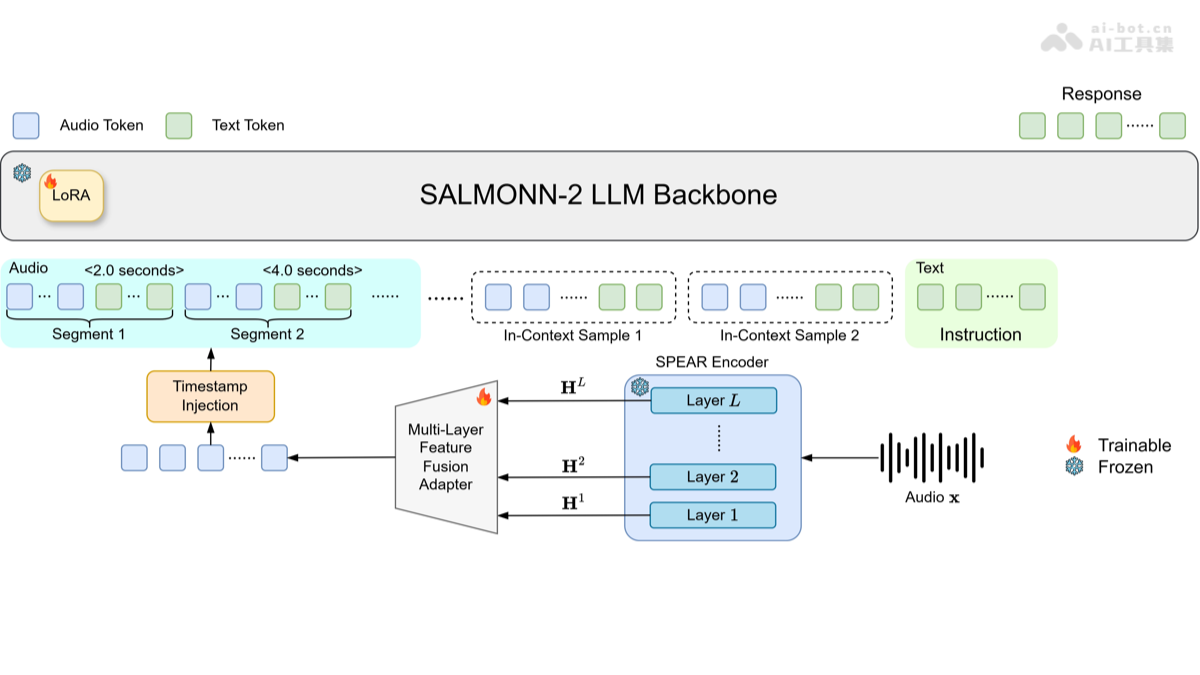
Unified self-supervised audio encoder: SALMONN-2 uses SPEAR as its sole audio front end. The encoder is trained through self-supervised learning on large-scale unlabeled audio data and can simultaneously capture semantic, pronunciation, timbre, speaker, and acoustic environment information. It replaces the traditional Whisper+BEATs dual-encoder architecture, simplifying the design while maintaining more balanced cross-domain capabilities.
Multi-layer feature fusion (MLF) adapter: Different SPEAR layers encode different levels of information: shallow layers retain acoustic and pronunciation details, middle layers carry timbre and speaker information, and deep layers accumulate semantic concepts. The MLF adapter first applies layer normalization and concatenation to the hidden states from each layer, then performs learnable down-projection and frame-group compression. Finally, it maps the fused hierarchical representations into the language model embedding space, enabling the model to flexibly use acoustic cues from different levels according to task requirements.
Timestamp injection mechanism: The model inserts timestamps directly into the audio sequence as natural-language text, such as <2.0 seconds>, and interleaves them with audio embeddings as input to the language model. This enables timestamp localization within a unified generation framework without requiring an additional timestamp-specific embedding layer.
Multimodal in-context learning (MICL) training: For contextual speech recognition, the model receives not only a text bias vocabulary but also reference pronunciation audio for those words as multimodal context. During training, random dropout of distractor and target words is introduced to prevent excessive bias, teaching the model to use contextual cues appropriately when supported by acoustic evidence.
04How to Use SALMONN-2
Access and clone the repository: Visit the GitHub repository at https://github.com/bytedance/SALMONN/tree/salmonn2 and use git clone to download the code locally.
Create the runtime environment: Run conda create -n salmonn2 python=3.10 to create and activate a virtual environment, then upgrade pip, setuptools, and wheel.
Install dependencies and the project: In the repository root, run pip install -r requirements.txt and pip install -e . --no-deps to install SALMONN-2 and its runtime dependencies.
Download the pretrained weights: Use the HuggingFace CLI to download the model checkpoint: hf download marcoyang/SALMONN-2-8B --repo-type model --local-dir /path/to/salmonn-2-hf.
Load the model and run inference: Use AutoProcessor and AutoModelForCausalLM to load the local weights, pass in an audio file and instruction text, and call model.generate() to obtain audio understanding results.
05Core Advantages of SALMONN-2
Data efficiency: Uses approximately 18,000 hours of supervised data—far less than the hundreds of thousands to millions of hours commonly used by competitors of comparable size—significantly reducing annotation costs.
More balanced unified front end: Replaces the dual-encoder architecture with a single SPEAR self-supervised encoder, achieving more balanced performance across speech, environmental sounds, music, and paralinguistic tasks.
Full use of hierarchical information: The MLF adapter fuses features from all encoder layers, avoiding the loss of key details such as acoustic and timbre information that can result from using only the final layer.
Expanded audio analysis capabilities: Systematically supports SED, deepfake detection, SQA, and other previously overlooked sound analysis tasks in a general-purpose ALLM for the first time.
Scalable architecture: After expanding the text backbone from 8B to 30B-A3B, scores on all three comprehensive benchmarks continued to improve, confirming the architecture's strong scale-up potential.
06SALMONN-2 Project Links
GitHub repository: https://github.com/bytedance/SALMONN/tree/salmonn2
HuggingFace model repository: https://huggingface.co/marcoyang/SALMONN-2-8B
arXiv technical paper: https://arxiv.org/pdf/2607.17079
07SALMONN-2 Use Cases
Intelligent meeting assistant: Transcribes meeting content in real time and accurately recognizes foreign names and technical terms using pronunciation examples from participants.
Audio content moderation: Automatically detects abnormal sound events in livestreams or podcasts and identifies deepfake speech to help prevent fraud.
Speech quality monitoring: Automatically scores the quality of customer service calls and studio recordings while locating noise and distortion segments.
Multimedia archive retrieval: Generates timestamped event descriptions for historical audio and radio programs, enabling precise content-based retrieval.
Assistive devices for people with hearing loss: Provides real-time text and timestamp alerts for environmental sound events such as doorbells and alarms.
© Disclaimer: domains and linked content may change over time. AIEZZ does not control third-party websites. Review external content and risks independently.
User reviews0